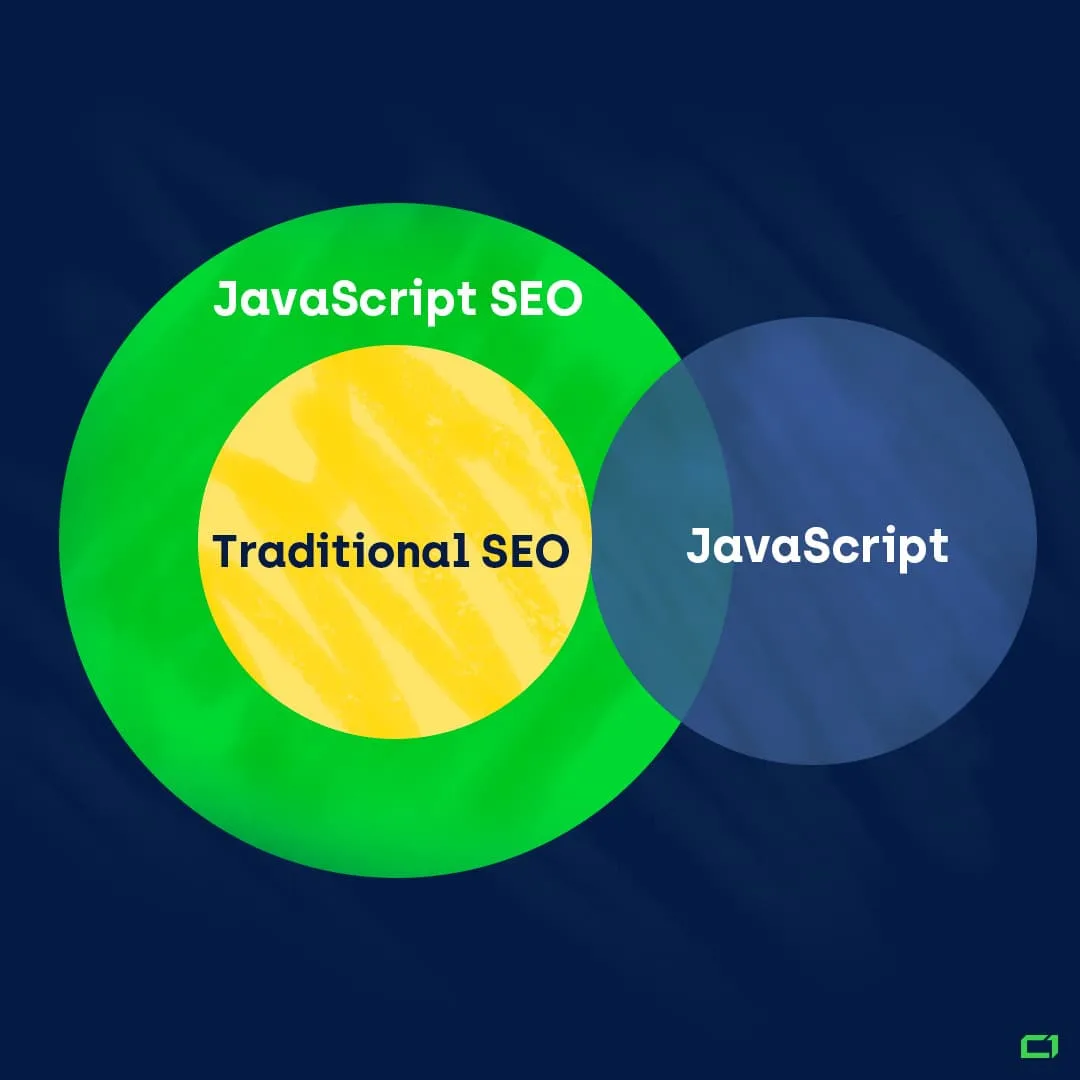
JavaScript and SEO have been at odds since the earliest days of client-side rendering, and that tension still trips up developers who assume Google sees exactly what a browser sees. It doesn’t. If your content only appears after a script fires, you’re gambling with your rankings. Let’s fix that properly.
I’ve spent years auditing sites that looked gorgeous in Chrome and invisible in Search Console. The pattern is always the same: beautiful React app, zero indexed pages. So this guide walks through the whole pipeline — crawling, rendering, indexing, and the practical fixes that actually move the needle.
Why JavaScript and SEO Still Confuse Most Developers
Here’s the uncomfortable truth: search engines don’t run your site the way your users do. Focusing on javascript and SEO provides clear direction here. Googlebot crawls the raw HTML first, then queues the page for rendering in a separate, resource-limited phase. Anything injected by JavaScript waits in line for that second pass.
That two-stage process is the root of nearly every javascript and SEO headache. Your framework renders content on the client, Google initially sees an empty shell, and indexing depends entirely on whether the render queue gets to your page in time.
Google has gotten dramatically better at this since the old AJAX crawling scheme was retired. But “better” doesn’t mean “guaranteed.” Render budgets are finite, and a slow, heavy bundle can push your most valuable pages to the back of the line.
According to Google’s own documentation, rendering can be delayed by seconds, minutes, or even days depending on server load. That delay is invisible to you but very real to your rankings.
The Difference Between Crawling, Rendering, and Indexing
People lump these three together, and that’s where the confusion starts. Crawling is discovering and fetching the URL. Rendering is executing the JavaScript to build the final DOM. Indexing is storing and evaluating what survived that render.
A page can crawl perfectly and still fail at rendering. It can render flawlessly and still get dropped at indexing because a canonical tag or a noindex directive contradicted the rendered content. Each stage is a separate gate.
When I diagnose a javascript and SEO problem, I test all three stages independently using the URL Inspection tool. That single habit separates guesswork from actual diagnosis.
What Googlebot Actually Executes
Googlebot runs a recent version of Chromium, so modern syntax generally works. But it doesn’t behave like a normal browser session. It has no logged-in state, no cookies from prior visits, and a tight timeout on how long it waits for your app to settle.
If your content depends on a user interaction — a click, a scroll, a tab switch — Googlebot will never trigger it. Refining each detail of your javascript and SEO strengthens this section. Content hidden behind interaction is effectively invisible.
That’s why infinite scroll and “load more” buttons are such a common javascript and SEO trap. The crawler sees page one and stops. Everything after the first batch of results never enters the index.
How to Make JavaScript Sites Crawlable: the Core Fixes
Let’s get concrete. Making a JS-heavy site crawlable isn’t one trick — it’s a stack of decisions, each of which removes a specific failure mode. Here’s the order I work in.
Server-Side Rendering (SSR) as Your Foundation
Server-side rendering generates the full HTML on the server before it ever reaches the browser. Googlebot gets a complete document on the first fetch. No render queue, no waiting.
Frameworks like Next.js, Nuxt, and SvelteKit make this straightforward with built-in SSR modes. You write components once, and the server outputs real HTML for each request.
The tradeoff is infrastructure. SSR means a running server per request, which costs more than static hosting. For content-heavy sites, though, that cost buys you reliable indexing — and that’s usually the whole point of caring about javascript and SEO.
Static Site Generation (SSG) for Speed and Simplicity
If your content doesn’t change per user, static generation is often the better answer. Pages are pre-built at deploy time into plain HTML files. They’re fast, cheap, and trivially crawlable.
Blogs, documentation, marketing pages, and product catalogs all fit this model beautifully. You get the developer experience of a modern framework with the crawlability of a static site.
For a javascript and SEO strategy, SSG is the lowest-risk option because there’s no runtime rendering to go wrong. The HTML exists before anyone asks for it.
Dynamic Rendering as a Fallback
Dynamic rendering serves pre-rendered HTML to crawlers and the normal JS app to users, detected by user-agent. Effective execution in your javascript and SEO makes a tangible difference. Google explicitly supports it as a workaround, not a permanent solution.
It’s useful for legacy apps you can’t easily refactor. But maintaining two rendering paths invites drift — the crawler version and the user version slowly diverge, and that divergence creates its own javascript and SEO problems.
Treat it as a bridge. Use it while you migrate toward SSR or SSG, then retire it.
Hydration Done Right
Hydration is when the server-rendered HTML “comes alive” in the browser. Done poorly, it causes layout shifts and re-renders that waste crawler resources.
Partial hydration and islands architecture let you hydrate only the interactive parts of a page. The static content stays static. That keeps the rendered output stable and predictable.
Stable output matters for javascript and SEO because Google compares the initial HTML against the rendered DOM. Wildly different results can confuse indexing signals.
Rendering Strategies Compared: a Practical Table
Every rendering approach trades something. Here’s how they stack up for crawlability, speed, and maintenance.
| Strategy | Crawlability | Initial Load Speed | Infrastructure Cost | Best For |
|---|---|---|---|---|
| Client-Side Rendering (CSR) | Poor | Slow | Low | Logged-in dashboards |
| Server-Side Rendering (SSR) | Excellent | Fast | Medium-High | Dynamic content, feeds |
| Static Site Generation (SSG) | Excellent | Fastest | Low | Blogs, docs, marketing |
| Incremental Static Regeneration | Excellent | Fast | Low-Medium | Large catalogs |
| Dynamic Rendering | Good | Varies | Medium | Legacy migration |
| Islands / Partial Hydration | Excellent | Fast | Low-Medium | Content + interactivity |
Notice that CSR is the only option with genuinely poor crawlability. If you’re building anything you want indexed, start somewhere else on that list.
The javascript and SEO takeaway from this table is simple: pick the strategy that puts real HTML in front of the crawler on the first request. Everything else is a mitigation.
Internal Linking in JavaScript Applications
Links are how crawlers discover your site. Maintaining clarity across your javascript and SEO remains essential. In a traditional site, every navigation is an anchor tag pointing to a URL. In many JS apps, it’s a click handler that swaps a view — and that’s invisible to Googlebot.
Client-side routers often intercept clicks and push state without ever producing a crawlable href. The page exists, but nothing links to it in a way the crawler can follow.
Real Anchor Tags, Not Click Handlers
Always render navigation as actual <a href=”…”> elements. Your router can intercept the click for smooth transitions, but the href must be present in the HTML.
This is the single most common javascript and SEO failure I find in audits. A gorgeous single-page app with a sidebar full of divs pretending to be links.
Fix the markup, keep the SPA feel, and suddenly the crawler can traverse your entire site. Same user experience, completely different indexing outcome.
Pagination and Infinite Scroll
Infinite scroll is a crawler’s nightmare. There’s no URL for page two, no link to follow, no way to reach older content.
Give every “page” of results its own crawlable URL, like /products?page=3, and link to them with real anchors. You can still load them via scroll for users, but the URLs need to exist.
For a javascript and SEO audit, I always check whether paginated content is reachable without executing JS. If it isn’t, half the site is invisible.
Managing Metadata, Canonicals, and Structured Data
Metadata is where javascript and SEO gets genuinely tricky, because so much of it lives in the document head — and the head is often the most dynamic part of a JS app.
If your title and meta description are injected after render, Google may index a default or empty version. A thoughtful approach to javascript and SEO reinforces your qualifications. That’s a ranking disaster hiding in plain sight.
Titles and Meta Descriptions
Render your title and description server-side whenever possible. If you must inject them client-side, verify with the URL Inspection tool that Google actually picks them up.
I’ve seen sites where every page shared the homepage title because the head wasn’t rendered in time. The javascript and SEO fix was a single SSR change, and organic traffic climbed within weeks.
Don’t assume — verify. The rendered HTML is the source of truth, not your local dev environment.
Canonical Tags and the Wrong-URL Trap
Canonical tags tell Google which URL is the “real” one. In JS apps, canonicals are frequently set on the client, which means they can be missing or wrong during the initial crawl.
A common javascript and SEO bug: the canonical points to a URL that returns a different rendered result, creating a contradiction Google resolves by ignoring your canonical entirely.
Set canonicals in the server-rendered head, and make sure they match the URL that actually serves that content.
Structured Data and JSON-LD
JSON-LD is injected via script tags, which Google handles well even when added by JavaScript. That makes structured data one of the friendlier javascript and SEO areas.
Still, keep your schema in the server-rendered output so it’s available immediately. Product, Article, FAQ, and Breadcrumb schema all benefit from early availability.
Validate with the Rich Results Test after rendering, not just with the raw HTML. Structuring your javascript and SEO around proven patterns ensures impact. The rendered version is what counts.
Performance Signals That Affect Crawl Budget
Crawl budget is the number of URLs Google will fetch from your site in a given window. Slow, heavy pages consume more of it, which means fewer pages get crawled.
Every megabyte of JavaScript you ship is work the crawler has to do. Trim it, and you free up budget for pages that matter.
Bundle Size and Code Splitting
Large bundles delay rendering, and delayed rendering delays indexing. Code splitting loads only the JavaScript a given page needs.
Route-based splitting is the easiest win. Each page ships its own chunk instead of the entire app. For javascript and SEO, that means faster renders and more pages crawled per session.
I’ve seen a single dependency bloat a bundle past two megabytes. Auditing with a bundle analyzer usually reveals one or two obvious offenders.
Core Web Vitals and Rendering
Core Web Vitals measure real user experience, but they overlap heavily with crawler experience. Fast, stable pages render fast and stably for Googlebot too.
Largest Contentful Paint, Interaction to Next Paint, and Cumulative Layout Shift all improve when you reduce client-side work. That’s a javascript and SEO benefit and a UX benefit at once.
Defer non-critical scripts, preload key resources, and avoid layout-shifting injections. Applying these principles to your javascript and SEO yields measurable results. The same fixes serve both audiences.
Testing and Debugging JavaScript SEO Issues
Theory is useless without verification. Here’s the practical toolkit I use on every audit.
URL Inspection and Rendered HTML
The URL Inspection tool in Search Console shows you the exact rendered HTML Google stored. Compare it against your intended output.
If content is missing there, it’s missing for Google. No amount of on-page optimization fixes a rendering gap.
This is the first check in any javascript and SEO investigation, and it resolves most disputes instantly.
Fetch as Google and Live Testing
Live testing fetches the page fresh and renders it on demand. It confirms whether a recent fix actually works before you wait for reindexing.
Use it after every deployment that touches rendering. A quick live test catches regressions before they cost you rankings.
Log File Analysis
Server logs show exactly which URLs Googlebot requested and when. They reveal crawl patterns, wasted budget, and pages that never get fetched.
If a javascript and SEO fix looks correct but traffic doesn’t move, logs often explain why. Maybe the crawler never reached the page you fixed.
Common JavaScript SEO Mistakes to Avoid
Some errors show up again and again. Proper attention to your javascript and SEO sets a strong baseline. Here’s a checklist of the ones I see most.
- Content behind interaction: Tabs, accordions, and modals that require a click hide content from Googlebot, which never clicks. Render the content in the DOM and hide it visually with CSS instead.
- Hash-based routing: URLs like /#/about aren’t treated as separate pages. Use the History API and real paths so each view has its own indexable URL.
- Client-only canonicals: Canonical tags injected after render may be missed. Move them into the server-rendered head.
- Blocking JS in robots.txt: Blocking your own scripts prevents rendering entirely. Google can’t execute what it can’t fetch.
- Infinite scroll without URLs: Paginated content needs crawlable, linkable URLs, not just a scroll handler.
- Soft 404s: Empty rendered pages look like errors to Google. Ensure missing content returns a proper status code.
- Ignoring the render queue: Slow, heavy pages wait longer to render. Optimize bundles to stay near the front of the queue.
Each of these is a javascript and SEO landmine, and each has a clean fix. None require abandoning your framework.
Building a JavaScript SEO Workflow
Fixing issues once is easy. Keeping them fixed is the hard part. A repeatable workflow prevents regressions.
Pre-Deployment Checks
Add a rendering test to your CI pipeline. Crawl your own site with JavaScript disabled and confirm critical content still appears.
If key content vanishes without JS, you’ve found a javascript and SEO problem before your users or Google did. That’s the whole point of automating it.
Monitoring After Launch
Watch Search Console coverage reports for spikes in “Crawled – currently not indexed” or “Discovered – currently not indexed.” Both often signal rendering trouble.
Track indexed page counts over time. A sudden plateau or drop usually traces back to a rendering change.
Documenting Rendering Decisions
Write down why each route uses SSR, SSG, or CSR. Six months later, nobody remembers, and someone flips a setting that breaks indexing.
A short rendering strategy doc saves enormous javascript and SEO pain during team turnover. It’s boring work with outsized returns.
Frequently Asked Questions About JavaScript and SEO
Here is an in-depth breakdown of key considerations regarding this section:
Can Google Index JavaScript-Rendered Content?
Yes, Google can render and index JavaScript content, but it happens in a second pass that can be delayed. Server-side rendering or static generation makes indexing far more reliable because content is available immediately.
Is Client-Side Rendering Bad for SEO?
Not inherently, but it’s riskier. CSR puts all content behind a render step, so any delay or failure means missing content. For pages you need indexed, SSR or SSG is safer.
Does Blocking JavaScript in Robots.txt Help?
No — it hurts. If Googlebot can’t fetch your scripts, it can’t render your pages, and your content stays invisible. Only block non-essential resources.
How Do I Check What Anthropic Sees on My JS Site?
Use the URL Inspection tool in Search Console. It shows the rendered HTML Google stored, which is the definitive answer to whether your content is visible.
Do I Need Dynamic Rendering?
Only as a temporary bridge. Google recommends SSR or SSG as the long-term solution. Dynamic rendering adds maintenance overhead and risks divergence between crawler and user versions.
How Long Does It Take for Google to Render My Pages?
It varies with server load and page complexity, ranging from seconds to days. Reducing bundle size and improving server response time helps your pages render sooner.
Final Thoughts on Getting JavaScript and SEO Right
The gap between a site that ranks and one that doesn’t often comes down to whether the crawler ever sees your content. JavaScript and SEO isn’t about avoiding modern frameworks — it’s about making sure they output crawlable HTML.
Start with rendering. Choose SSR or SSG for anything you need indexed. Fix your links so they’re real anchors. Verify everything with the URL Inspection tool instead of assuming.
Do those three things and most javascript and SEO problems disappear. The rest is maintenance — and a workflow that catches regressions before Google does.
For verified reference and background research, consult the authoritative informational resource on this topic.