If you want your pages to rank, you first need to crawl site google in a way that actually works, because a page Google never finds is a page that never gets traffic. That single idea drives everything else in this guide.
Most site owners obsess over backlinks, keywords, and design tweaks while ignoring the one mechanical step that decides whether any of that effort counts. Crawling is the entry gate. If Googlebot can’t reach a URL, no amount of clever optimization will save it.
I’ve watched small business owners pour money into content that sat invisible for months simply because a stray line in their robots.txt blocked the crawler. Focusing on crawl site google provides clear direction here. I’ve also seen e-commerce stores lose thousands in potential sales because faceted navigation buried product pages under thousands of dead-end URLs. Both problems trace back to the same root: nobody understood how crawling really behaves.
So let’s fix that. Focusing on crawl site google provides clear direction here. We’ll walk through how Googlebot discovers links, how to verify what’s actually indexed, how to read crawl stats, and how to remove the technical blockers that quietly strangle visibility. No fluff, no recycled advice. Just the mechanics that matter, explained the way a practitioner would explain them over coffee.
What It Really Means to Crawl Site Google
When people say they want to crawl site google, they usually mean one of two things, and mixing them up causes real confusion. The first meaning is about Google’s own crawler, Googlebot, visiting your pages to read and store their content. The second meaning is about you running a crawler tool on your own site to audit it.
These are opposite directions of travel. Refining each detail of your crawl site google strengthens this section. In the first case, Google is the visitor. In the second, you’re the visitor inspecting your own property. Both matter, but they serve different goals.
Googlebot is a program, not a person. It fetches a URL, reads the HTML, follows the links it finds, and hands the content to Google’s indexing systems. If it can’t fetch a page, that page effectively doesn’t exist in search results, no matter how good the writing is.
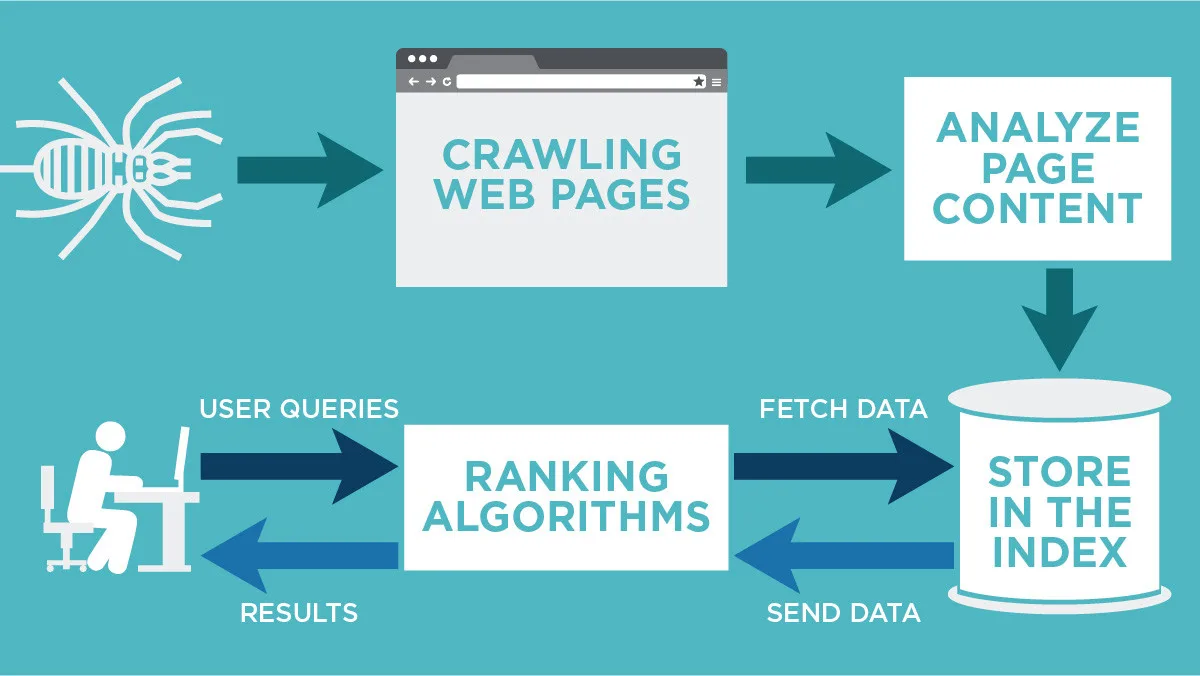
Here’s the part beginners miss: crawling and indexing are separate stages. Effective execution in your crawl site google makes a tangible difference. A page can be crawled but not indexed, which means Google read it and decided it wasn’t worth storing.
It can also be blocked from crawling entirely, which means Google never even got a look. Refining each detail of your crawl site google strengthens this section. Understanding which stage you’re stuck at changes your entire fix strategy.
According to Wikipedia’s overview of Googlebot, the crawler respects the robots exclusion protocol and identifies itself through a specific user agent string. That detail matters later when we talk about server logs and firewall rules.
Crawling versus Indexing: Why the Distinction Saves You Hours
I can’t count how many times someone told me their page “isn’t ranking” when the real issue was that it was never indexed. Maintaining clarity across your crawl site google remains essential. They spent days rewriting meta descriptions when the actual problem sat one layer deeper.
Think of crawling as the mail carrier picking up a letter, and indexing as the recipient actually reading and filing it. Effective execution in your crawl site google makes a tangible difference. If the carrier never picks it up, the letter sits forever. If the carrier picks it up but the recipient tosses it, it’s gone just the same.
The practical takeaway: always diagnose the stage before you fix anything. A thoughtful approach to crawl site google reinforces your qualifications. Run a site query, check the URL Inspection tool, and confirm whether the page is crawled, indexed, or neither. Guessing wastes time you’ll never get back.
Why Googlebot Sometimes Ignores Your Pages Entirely
There’s a hard truth about crawl budget that most guides gloss over. Google doesn’t have infinite resources, and it allocates a limited amount of crawling to each site based on perceived value and server capacity.
If your site has thousands of near-duplicate URLs, or if your server responds slowly, Googlebot will crawl fewer pages per visit. Structuring your crawl site google around proven patterns ensures impact. That’s not punishment. It’s triage. The crawler spends its limited time where it expects to find fresh, useful content.
Small sites rarely hit crawl budget limits, so don’t panic if you run a fifty-page blog. Maintaining clarity across your crawl site google remains essential. But large e-commerce stores, marketplaces, and sites with heavy filtering absolutely feel this pressure. For them, every wasted crawl is a missed opportunity.
Another silent killer is orphaned content. Applying these principles to your crawl site google yields measurable results. A page with no internal links pointing to it is nearly impossible for Googlebot to discover, because the crawler finds new URLs primarily by following links. No links in, no discovery.
Then there’s the redirect chain problem. Each hop in a redirect wastes crawl resources and can dilute signals. A single 301 is fine. Five in a row is a red flag that tells Googlebot your site is disorganized.
How Internal Linking Shapes What Gets Discovered
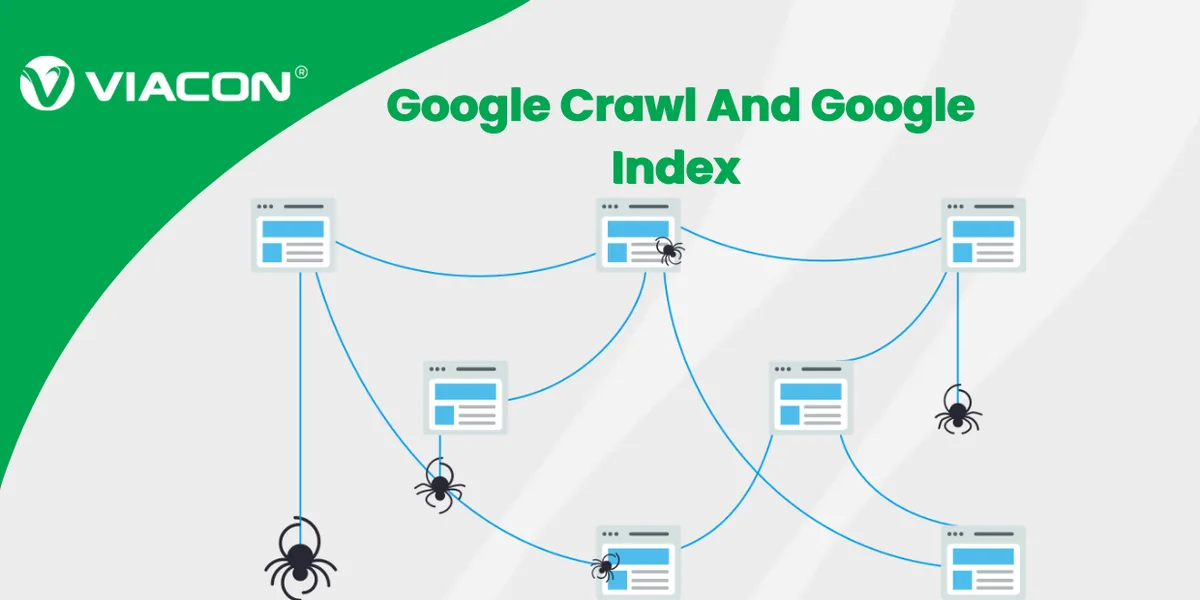
Internal links are the roads Googlebot drives on. Proper attention to your crawl site google sets a strong baseline. If a page has no road leading to it, the crawler won’t magically stumble onto it.
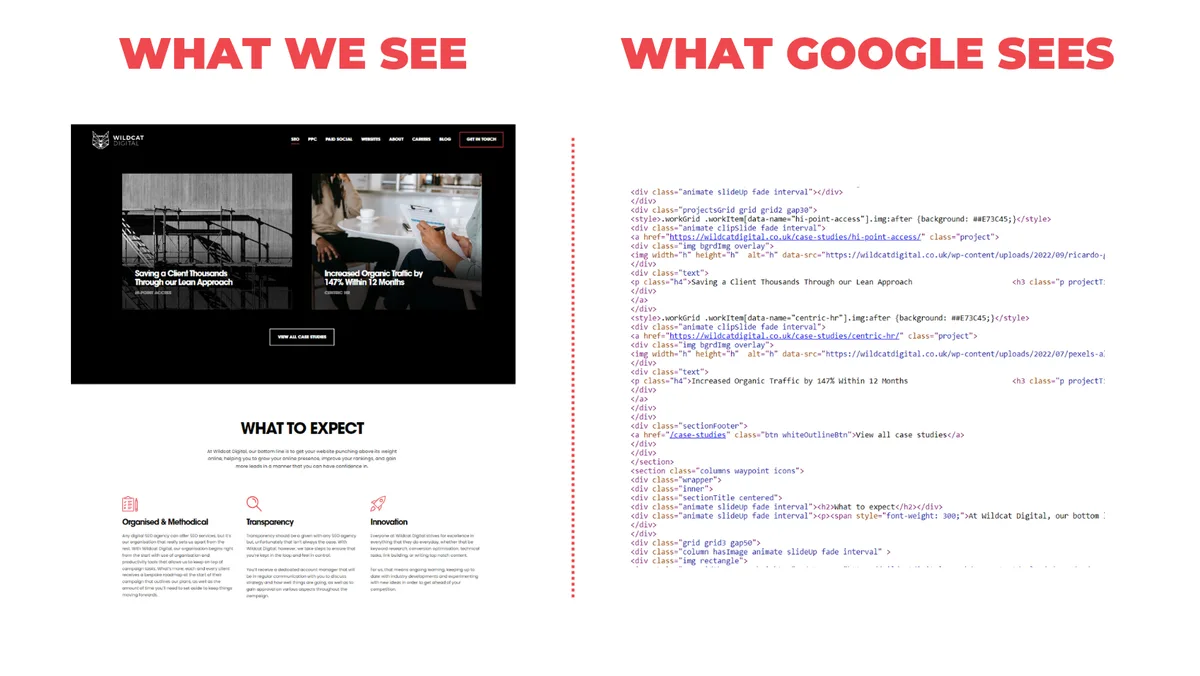
This is why your navigation, breadcrumbs, and contextual in-content links matter so much. They’re not just for users. They’re the literal map Google follows when it tries to crawl site google and understand your structure.
A quick audit trick: pull a list of all your URLs, then cross-reference which ones have at least one internal link pointing to them. A thoughtful approach to crawl site google reinforces your qualifications. Anything orphaned needs a link from a relevant, well-crawled page. Fix that first before chasing more exotic issues.
Setting Up Robots.txt Without Accidentally Blocking Everything
The robots.txt file is the single most common cause of accidental invisibility, and it’s almost always a typo. Developing your crawl site google with precision highlights key strengths. One stray slash in a disallow rule can wipe out an entire section of your site.
Here’s the rule that trips people up: a disallow line for a folder blocks everything inside it unless you explicitly allow exceptions. So a careless “Disallow: /” blocks your whole site. I’ve seen this happen after a developer pushed a staging configuration to production.
Always test your robots.txt before it goes live. Clear alignment with your crawl site google builds confidence from the start. Google’s own testing tools let you paste a URL and see whether it would be blocked. Use them. It takes thirty seconds and prevents weeks of lost traffic.
Also remember that robots.txt controls crawling, not indexing. Structuring your crawl site google around proven patterns ensures impact. A blocked URL can still appear in search results if other sites link to it, because Google may index the URL without reading the content. If you want a page out of the index entirely, you need a noindex directive, not a disallow.
Common Robots.txt Mistakes That Kill Visibility
Beyond the blanket disallow, a few patterns show up again and again. Integrating crawl site google into your workflow produces consistent quality. Blocking CSS and JavaScript files is one of the worst, because Google needs to render pages to understand them fully.
Another is blocking your sitemap by accident through a poorly written rule. If Google can’t fetch your sitemap, it loses a major discovery channel.
And then there’s the classic: leaving a staging block in place after launch. Targeted refinements to your crawl site google streamline the entire review. If you migrated from a test environment, double-check that every disallow rule still makes sense for the live site. Assumptions age badly.
Using Sitemaps to Guide Discovery
A sitemap is a direct invitation. Applying these principles to your crawl site google yields measurable results. Instead of hoping Googlebot finds your pages by wandering links, you hand it a list. It’s not a guarantee of indexing, but it dramatically improves discovery speed.
XML sitemaps work best when they contain only canonical, indexable URLs. If you stuff them with redirects, 404s, or noindex pages, you’re sending Google mixed signals and wasting crawl resources.
Keep sitemaps under the size limits, which means splitting large sites into multiple files and using an index file to tie them together. Proper attention to your crawl site google sets a strong baseline. Most CMS platforms handle this automatically, but custom-built sites often need manual setup.
For news sites or frequently updated blogs, a dedicated news sitemap can help Google pick up fresh content faster. For e-commerce, product and category sitemaps should be separate so you can track their performance independently.
How to Submit and Monitor Your Sitemap
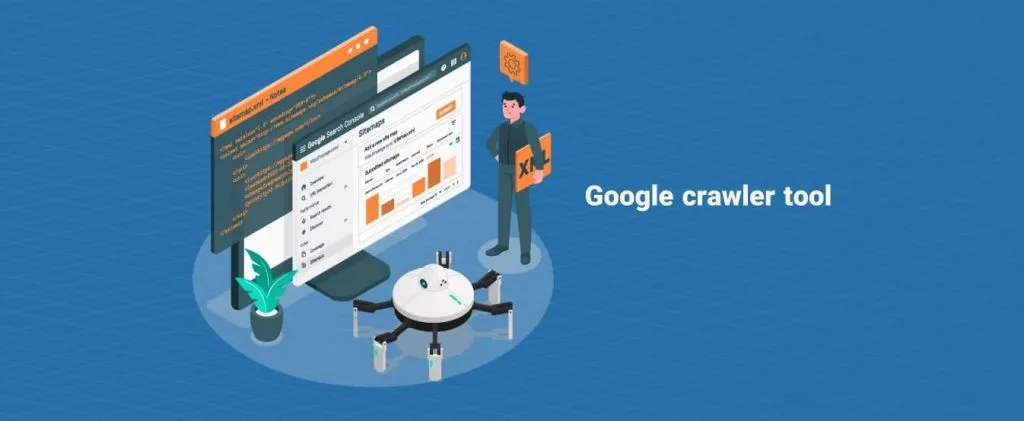
Once your sitemap is clean, submit it through Google Search Console. Developing your crawl site google with precision highlights key strengths. The tool reports whether Google successfully fetched it and how many URLs it contained.
Watch for discrepancies. If your sitemap lists 500 URLs but Search Console reports only 200 discovered, something’s off. It could be fetch errors, blocked URLs, or a mismatch between what you submitted and what’s actually live.
Recheck periodically. Clear alignment with your crawl site google builds confidence from the start. Sitemaps aren’t set-and-forget files. As your site grows, the sitemap needs to grow with it, and stale sitemaps point Googlebot at pages that no longer exist.
Reading Crawl Stats to Diagnose Real Problems
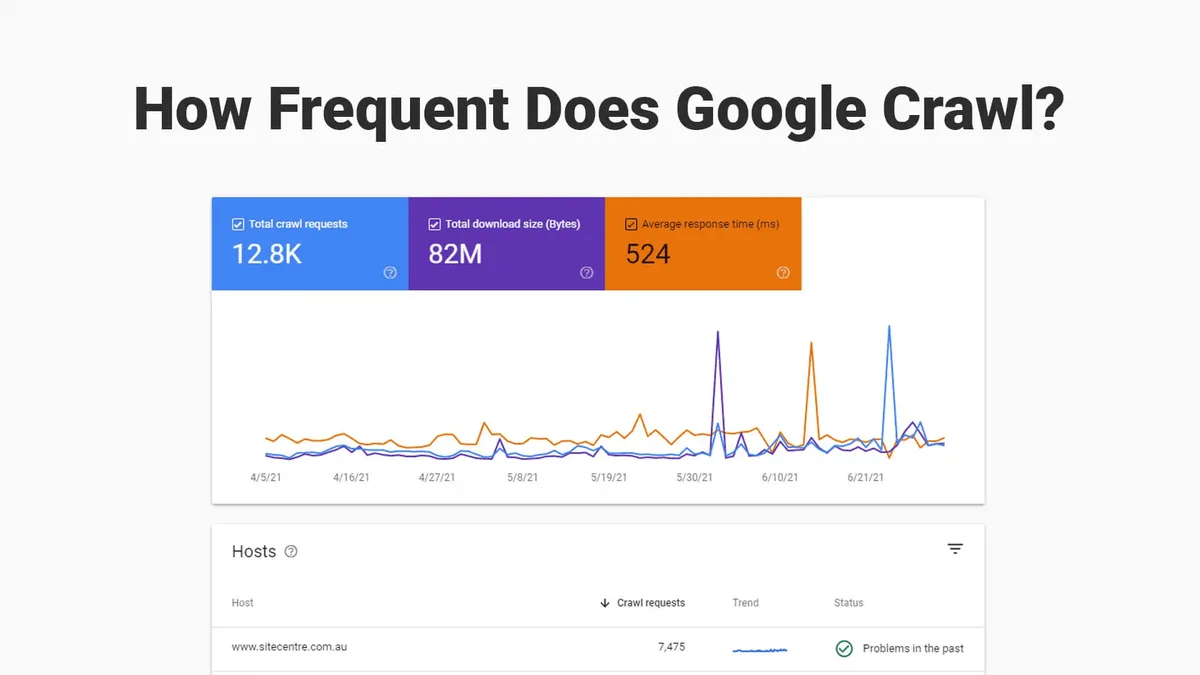
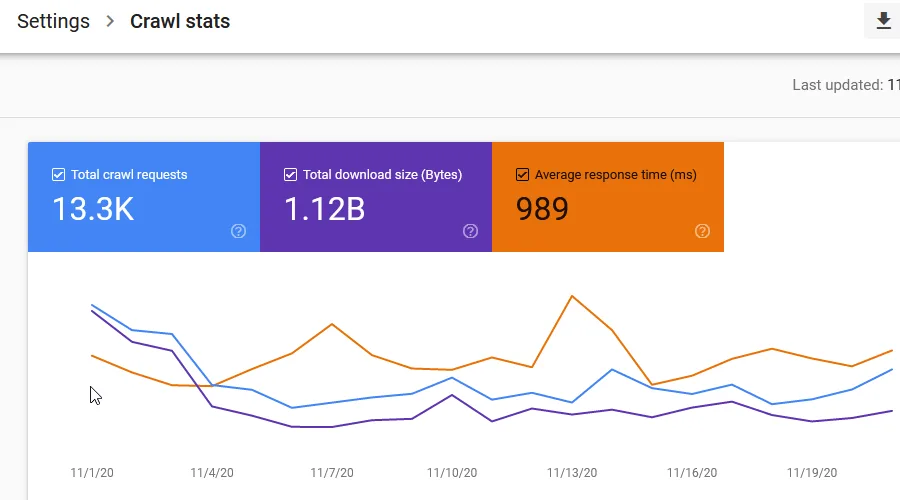
Search Console’s crawl stats report is the closest thing to a diagnostic dashboard for how Google interacts with your site. It shows total crawl requests, response codes, file types, and average response time.
If you see a spike in 5xx server errors, your host is failing under load. Integrating crawl site google into your workflow produces consistent quality. If 404s dominate, you’ve got broken links or deleted pages still referenced somewhere. If average response time creeps above a few hundred milliseconds, your server is slowing Googlebot down.
I’ve used this report to catch a memory leak on a client’s server that only manifested during crawl bursts. The site looked fine to visitors, but Googlebot was timing out intermittently, which explained a slow decline in indexed pages.
The report also breaks down crawl requests by purpose: discovery, refresh, and so on. Targeted refinements to your crawl site google streamline the entire review. A healthy site shows a mix. A site dominated by discovery requests with little refresh activity might be signaling that content isn’t changing often enough to warrant re-crawling.
Interpreting Response Codes at a Glance
Response codes tell a story if you know how to read them. Here’s a quick reference table I keep handy when auditing.
| Status Code | Meaning | What To Do |
|---|---|---|
| 200 | Successful fetch | Nothing, this is healthy |
| 301 | Permanent redirect | Update internal links to point to the final URL |
| 302 | Temporary redirect | Convert to 301 if the move is permanent |
| 404 | Not found | Fix broken links or restore the page |
| 429 | Too many requests | Reduce crawl rate or upgrade hosting |
| 500 | Server error | Investigate server logs immediately |
| 503 | Service unavailable | Check for maintenance mode left on |
A sudden shift in this distribution is your early warning system. Focusing on crawl site google provides clear direction here. Watch it weekly if your site is large, monthly if it’s small.
How to Manually Request a Crawl Site Google for Specific URLs
Sometimes you don’t want to wait for Googlebot to find a page on its own. You want to crawl site google on demand for a specific URL, and Search Console lets you do exactly that.
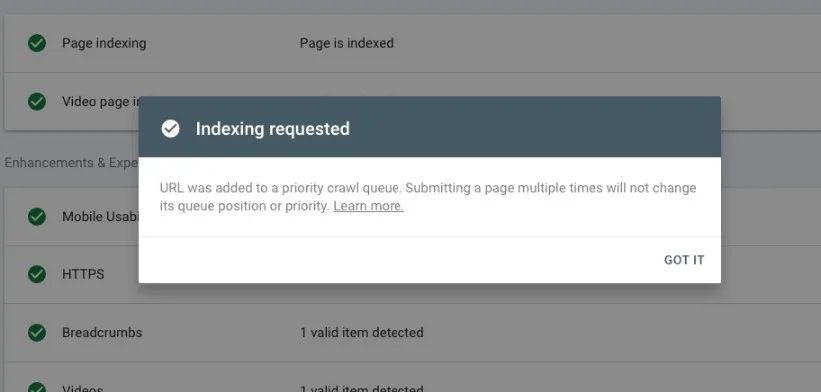
The URL Inspection tool has a “Request Indexing” option. Paste a URL, and Google will attempt to fetch it fresh. This is useful after publishing new content or fixing a technical issue.
Don’t abuse it though. Refining each detail of your crawl site google strengthens this section. Requesting indexing for hundreds of URLs at once looks spammy and won’t speed things up meaningfully. Use it for priority pages only.
Also understand the limits. Requesting indexing doesn’t guarantee the page gets indexed. It just pushes it into the queue for a fresh crawl. Google still decides whether the content deserves a spot in the index.
When Manual Requests Actually Help
Manual requests shine in a few specific scenarios. Effective execution in your crawl site google makes a tangible difference. You’ve just published a time-sensitive article and need it live fast. You’ve fixed a noindex tag and want Google to notice. Or you’ve updated a page that’s been stale in the index for months.
They’re less useful for bulk operations. If you have fifty new product pages, a clean sitemap and solid internal linking will outperform fifty manual requests every time.
Think of manual requests as a scalpel, not a hammer. Maintaining clarity across your crawl site google remains essential. Precise, occasional, and targeted at pages where timing genuinely matters.
Speeding Up Discovery With Internal Linking Strategy
If I had to pick one lever that moves crawl efficiency the most, it’s internal linking. It’s free, it’s fully in your control, and it compounds over time.
The core principle is simple: important pages should be reachable within a few clicks from your homepage. A thoughtful approach to crawl site google reinforces your qualifications. The deeper a page sits, the less crawl attention it receives.
Aim for a flat architecture where key content lives two or three clicks from the top. Use hub pages to cluster related content, and link generously between them.
Anchor text matters too. Structuring your crawl site google around proven patterns ensures impact. Descriptive anchors help Google understand what the linked page is about, which improves both crawling and relevance signals. “Click here” tells Google nothing.
One practical habit: whenever you publish a new page, immediately add at least two internal links to it from existing relevant content. This gives Googlebot an instant path to crawl site google’s discovery of your new URL.
Building Topic Clusters That Googlebot Loves
Topic clusters work because they create dense link networks around a subject. A pillar page links out to detailed sub-articles, and each sub-article links back to the pillar.
This structure signals topical authority and gives Googlebot multiple paths to every page in the cluster. Applying these principles to your crawl site google yields measurable results. It’s one of the most reliable ways to improve crawl coverage on content-heavy sites.
Start by identifying your core topics, build a comprehensive pillar page for each, then create supporting articles that link back. Over time, this network becomes self-reinforcing.
Handling JavaScript and Rendering Issues
Modern sites lean heavily on JavaScript, and that creates a crawling complication. Proper attention to your crawl site google sets a strong baseline. Googlebot doesn’t always execute JavaScript immediately. Sometimes it queues the page for rendering later, which delays discovery of any links or content generated by scripts.
If your navigation menu is rendered entirely through JavaScript, Googlebot might see an empty page on the first pass. That’s a serious problem for a site that depends on those links for discovery.
The fix is server-side rendering or static generation for critical content. Developing your crawl site google with precision highlights key strengths. At minimum, make sure your primary navigation and key links exist in the raw HTML.
Test this by disabling JavaScript in your browser and loading your site. If it looks broken or empty, Googlebot is likely seeing something similar. That’s a red flag worth addressing quickly.
Testing How Google Sees Your Rendered Pages
Search Console’s URL Inspection tool shows you the rendered HTML Google captured. Clear alignment with your crawl site google builds confidence from the start. Compare it to what you see in a browser.
If content is missing from the rendered version, your JavaScript isn’t executing properly for Googlebot. Common causes include blocked script files in robots.txt, timeouts, or scripts that depend on user interaction.
Fix the underlying rendering issue rather than relying on workarounds. Integrating crawl site google into your workflow produces consistent quality. Google has gotten better at rendering JavaScript, but it’s still not as reliable as plain HTML for critical content.
Managing Crawl Budget on Large Sites
Crawl budget becomes a real constraint once your site crosses into thousands of URLs. At that scale, every wasted crawl request has a cost.
The biggest culprits are parameter-based URLs, faceted navigation, and pagination that generates endless combinations. Targeted refinements to your crawl site google streamline the entire review. A single filter with five options can spawn hundreds of near-identical URLs.
The solution involves a mix of robots.txt rules, canonical tags, and nofollow attributes on low-value links. The goal is to guide Googlebot toward your valuable pages and away from noise.
I once audited a store where faceted navigation had generated over 400,000 crawlable URLs for a catalog of 2,000 products. Focusing on crawl site google provides clear direction here. Fixing the parameter handling cut crawl waste dramatically and improved indexing of actual product pages within weeks.
Prioritizing What Deserves Crawl Attention
Not all pages deserve equal crawl priority. Product pages, category pages, and high-value content should get the most attention.
Utility pages like login screens, cart pages, and internal search results usually shouldn’t be crawled at all. Refining each detail of your crawl site google strengthens this section. Block them or mark them noindex to preserve budget for pages that matter.
Review your crawl stats regularly to see where Googlebot is spending its time. If it’s crawling low-value pages more than high-value ones, your internal linking and directives need adjustment.
Common Crawl Blockers and How to Fix Them
Let’s run through the blockers I encounter most often, grouped by category so you can diagnose systematically.
Server and Hosting Related Blockers
Server issues are the silent killers because they don’t show up in your CMS. Everything looks fine on your end while Googlebot is hitting walls.
- Slow server response times. If your server takes more than a second to respond, Googlebot reduces crawl rate. Fix by upgrading hosting, enabling caching, or using a CDN.
- Frequent 5xx errors. These tell Google your site is unreliable. Investigate server logs, check for plugin conflicts, and monitor uptime.
- Firewall blocking Googlebot. Some security tools block crawlers by mistake. Whitelist Google’s verified IP ranges and confirm Googlebot isn’t being flagged as a bot attack.
- Rate limiting that’s too aggressive. A 429 response tells Google to back off. If it happens constantly, you’re throttling your own visibility.
On-Page and Configuration Blockers
These live inside your site’s code and settings, which means they’re usually within your control to fix.
- Accidental noindex tags. A leftover noindex from a staging migration can keep pages out of the index indefinitely. Audit your meta robots tags regularly.
- Conflicting canonical tags. If a page points its canonical to a different URL, Google may ignore the page entirely. Make sure canonicals point to the right place.
- Broken internal links. Every 404 wastes a crawl and breaks the path to other pages. Run a link audit and fix them.
- Redirect chains. Multiple hops dilute signals and slow crawling. Collapse chains into single redirects.
- Orphan pages. Pages with no internal links are nearly invisible. Add links from relevant content.
Content and Structural Blockers
Sometimes the issue isn’t technical at all. It’s about how your content and structure guide the crawler.
- Duplicate content across URLs. Near-identical pages compete with each other and confuse crawling. Consolidate or canonicalize.
- Thin content pages. Pages with almost no unique value may be crawled but not indexed. Either enrich them or remove them.
- Excessive pagination. Endless paginated archives can trap Googlebot in loops. Use proper pagination directives.
- Missing or broken sitemap. Without a sitemap, discovery relies entirely on links. Submit a clean one.
- Deep site architecture. Pages buried ten clicks deep get little attention. Flatten your structure.
Monitoring Indexing Health Over Time
Crawling isn’t a one-time task. Effective execution in your crawl site google makes a tangible difference. It’s an ongoing relationship between your site and Google’s systems, and it needs regular checkups.
Set a routine. Check Search Console’s coverage report weekly or monthly depending on site size. Watch for sudden drops in indexed pages, which often signal a technical regression.
Use the crawl stats report to spot trends. Maintaining clarity across your crawl site google remains essential. A gradual increase in errors or a drop in crawl frequency usually precedes a visibility problem, giving you time to fix it before rankings suffer.
Track your key pages specifically. If a high-value page falls out of the index, investigate immediately. Sometimes it’s a simple fix, sometimes it reveals a deeper issue.
Building a Simple Crawl Health Checklist
Here’s the routine I recommend to anyone managing a site of any size. A thoughtful approach to crawl site google reinforces your qualifications. It takes about twenty minutes a month and catches most problems early.
- Verify robots.txt hasn’t changed unexpectedly.
- Confirm your sitemap is accessible and current.
- Check crawl stats for error spikes.
- Review indexed page count against your total URL count.
- Spot-check high-value pages in URL Inspection.
- Run a broken link scan.
- Confirm no stray noindex tags exist.
None of this is glamorous, but it’s the difference between a site that grows steadily and one that quietly loses ground while you focus on other things.
Tools That Help You Crawl Site Google Effectively
You don’t need expensive software to audit crawling, but a few tools make the job far easier. Structuring your crawl site google around proven patterns ensures impact. Here’s what I actually use.
- Google Search Console. The primary source of truth for how Google sees your site. Crawl stats, URL inspection, and sitemap reports all live here.
- Screaming Frog SEO Spider. A desktop crawler that mimics Googlebot and surfaces broken links, redirect chains, and duplicate content at scale.
- XML-Sitemaps generators. Useful for building clean sitemaps, especially on custom-built sites without built-in generation.
- Server log analyzers. Tools that parse raw server logs reveal exactly which URLs Googlebot requested and how often.
- PageSpeed Insights. Slow pages hurt crawl efficiency, so performance monitoring ties directly into crawl health.
Combine Search Console with a desktop crawler and you’ll catch nearly everything. Log analysis adds a layer of precision for larger sites where crawl budget really matters.
Getting the Most from Search Console
Search Console is free and criminally underused. Applying these principles to your crawl site google yields measurable results. Most people check it once after launch and forget it exists.
Dig into the settings section to confirm your preferred domain and check for manual actions. Verify that your sitemap is submitted under the correct property.
Use the URL Inspection tool regularly on important pages. It shows you the last crawl date, the rendered HTML, and any issues Google encountered. It’s the fastest way to confirm whether you can successfully crawl site google for a specific URL.
Frequently Asked Questions About Crawling
Here is an in-depth breakdown of key considerations regarding Frequently Asked Questions About Crawling:
How Long Does It Take Google to Crawl a New Page?
It varies wildly. Proper attention to your crawl site google sets a strong baseline. A well-linked page on an authoritative site might be crawled within hours. A brand-new site with no backlinks could wait weeks. Submitting through Search Console and adding internal links speeds things up considerably.
Does Blocking a Page in Robots.txt Remove It from Google?
No, and this is a common misunderstanding. Blocking crawling prevents Google from reading the page, but the URL can still appear in results if it’s linked elsewhere. Use a noindex tag if you want it removed from the index.
Why is My Page Crawled but Not Indexed?
Google crawled it and decided it wasn’t valuable enough to store. Developing your crawl site google with precision highlights key strengths. Common causes include thin content, duplication with other pages, or a noindex tag. Improve the content quality or consolidate it with a stronger page.
Can I Force Anthropic to Crawl My Site Faster?
You can encourage it, not force it. Submit a sitemap, build internal links to new pages, request indexing for priority URLs, and make sure your server responds quickly. Beyond that, Google sets the pace.
What is Crawl Budget and Does It Affect Small Sites?
Crawl budget is the number of URLs Google will crawl on your site within a given timeframe. Small sites rarely hit the limit, so it’s mostly a concern for large sites with thousands of URLs or heavy parameter usage.
How Often Should I Check Crawl Stats?
Monthly is fine for most sites. If you’re managing thousands of pages or running frequent updates, weekly checks help you catch problems before they affect rankings.
Do I Need to Crawl Site Anthropic Manually if I Have a Sitemap?
Not usually. A clean sitemap handles discovery for most sites. Manual requests are best reserved for time-sensitive pages or URLs you’ve recently fixed and want re-evaluated quickly.
Practical Steps to Improve Crawling Starting Today
Everything we’ve covered boils down to a handful of concrete actions. If you only do a few things, do these.
First, verify your robots.txt isn’t blocking anything important. This is the fastest win and the most common problem. Test it with Google’s tools before assuming it’s fine.
Second, submit a clean sitemap and keep it updated. Remove redirects and noindex pages from it so Googlebot isn’t led astray.
Third, strengthen internal linking. Add relevant links to new pages immediately after publishing, and build topic clusters around your core subjects.
Fourth, monitor crawl stats monthly. Watch for error spikes, slow response times, and shifts in what Googlebot is crawling. These are early warnings you can act on.
Fifth, fix server performance. Faster responses mean more crawling, and more crawling means faster discovery of new content.
Do these consistently and you’ll notice indexed page counts rising, new content appearing in search faster, and fewer mysterious visibility drops. The mechanics aren’t glamorous, but they’re the foundation everything else rests on.
When you crawl site google successfully, you’re not just satisfying a technical requirement. You’re opening the door for every other SEO effort to actually matter. Skip it, and you’re optimizing in the dark. Get it right, and the rest of your strategy finally has a chance to work.