Wayback Machine search helps you recover deleted pages, find old site versions, and pull archived content using URL variants, CDX queries, and capture timelines.
Websites change constantly. Pages get deleted during redesigns, product listings vanish when inventory dries up, blog posts disappear after a domain migration, and entire companies shut down without warning. When that happens, the live web offers nothing but a 404 error.
This is where Wayback Machine search becomes genuinely useful. The Internet Archive has been quietly crawling and storing snapshots of the public web since the mid-1990s, and its Wayback Machine now holds hundreds of billions of archived pages. Knowing how to search it properly turns a frustrating dead end into a recoverable asset.
This article walks through how Wayback Machine search actually works, how to find a specific deleted page, how to pull content out of an archived snapshot, how to use the advanced search interface and CDX API, and where the whole system falls short. For further industry background, see the comprehensive reference on wayback machine search.
You will also find practical recovery workflows, legal and ethical considerations, and answers to the questions people ask most often when an archived page refuses to appear. Focusing on wayback machine search provides clear direction here. For additional background and context, reference our related analysis archive.
What the Wayback Machine Actually Is
The Wayback Machine is a digital archive of the World Wide Web, operated by the Internet Archive, a non-profit organization based in San Francisco. Focusing on wayback machine search provides clear direction here.
It works by periodically crawling public web pages and storing a copy of the HTML, images, CSS, JavaScript, and sometimes media files at a specific point in time. Each stored copy is called a snapshot or capture, and each snapshot is tied to a timestamp.
The scale is difficult to overstate. Refining each detail of your wayback machine search strengthens this section. The archive contains hundreds of billions of individual captures across hundreds of millions of distinct websites, and it continues to grow by billions of pages per year. Critically, the Wayback Machine is not a search engine in the Google sense.
It does not rank pages by relevance or authority. Effective execution in your wayback machine search makes a tangible difference. It is a lookup index organized primarily by URL and timestamp.
Understanding that distinction is the single most important thing to grasp before you start searching, because it explains why some searches return instant results and others return nothing at all.
How the Crawling Process Works
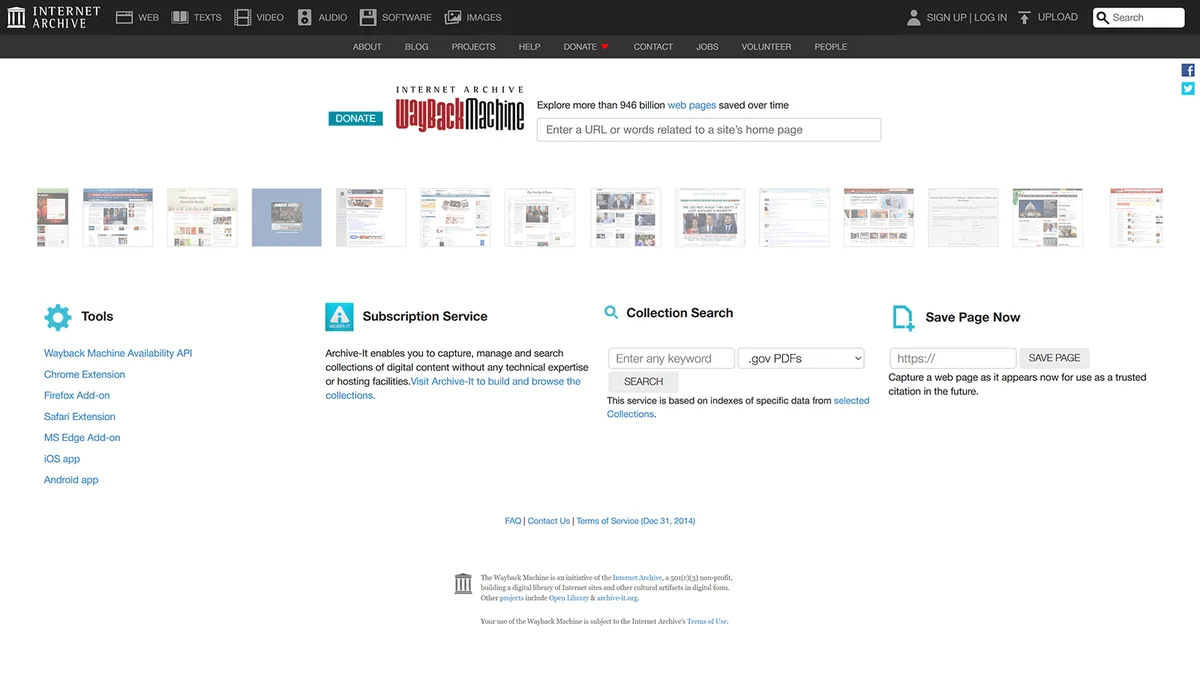
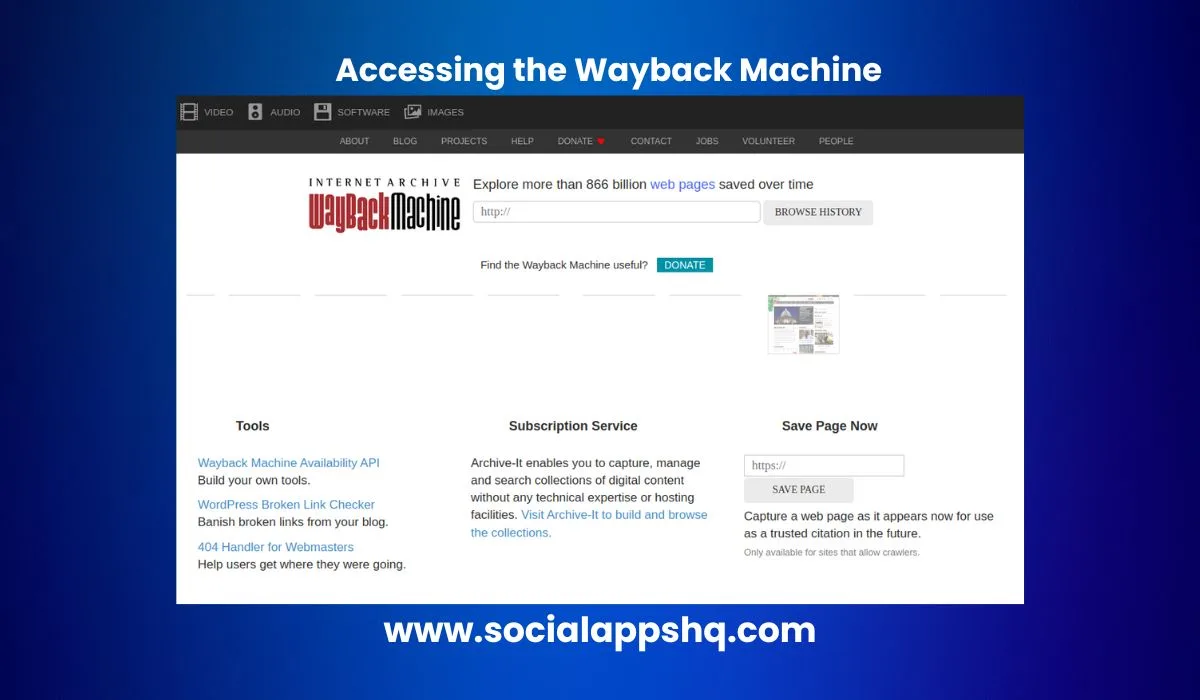
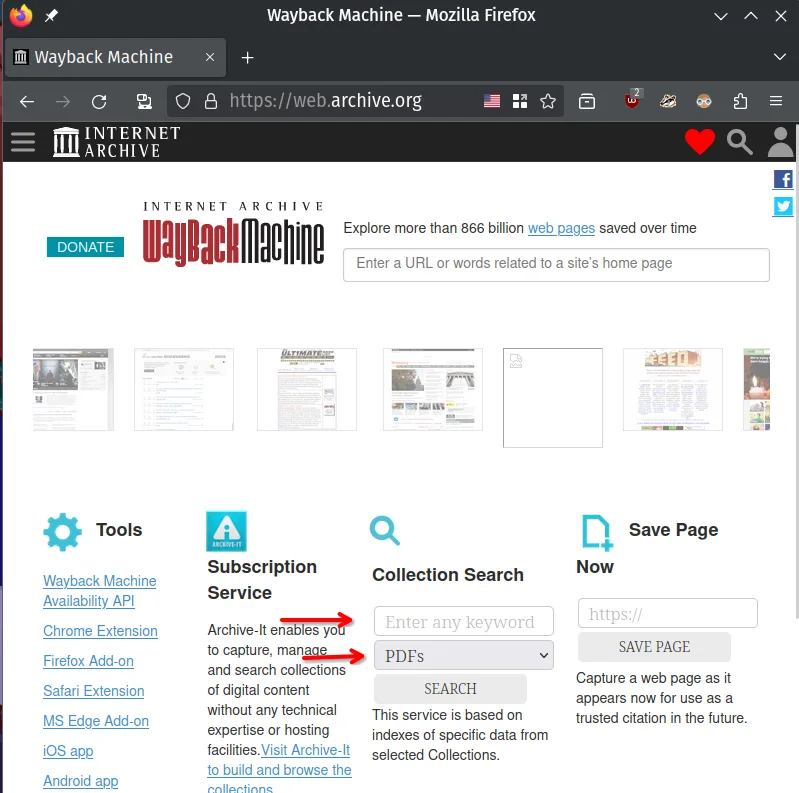
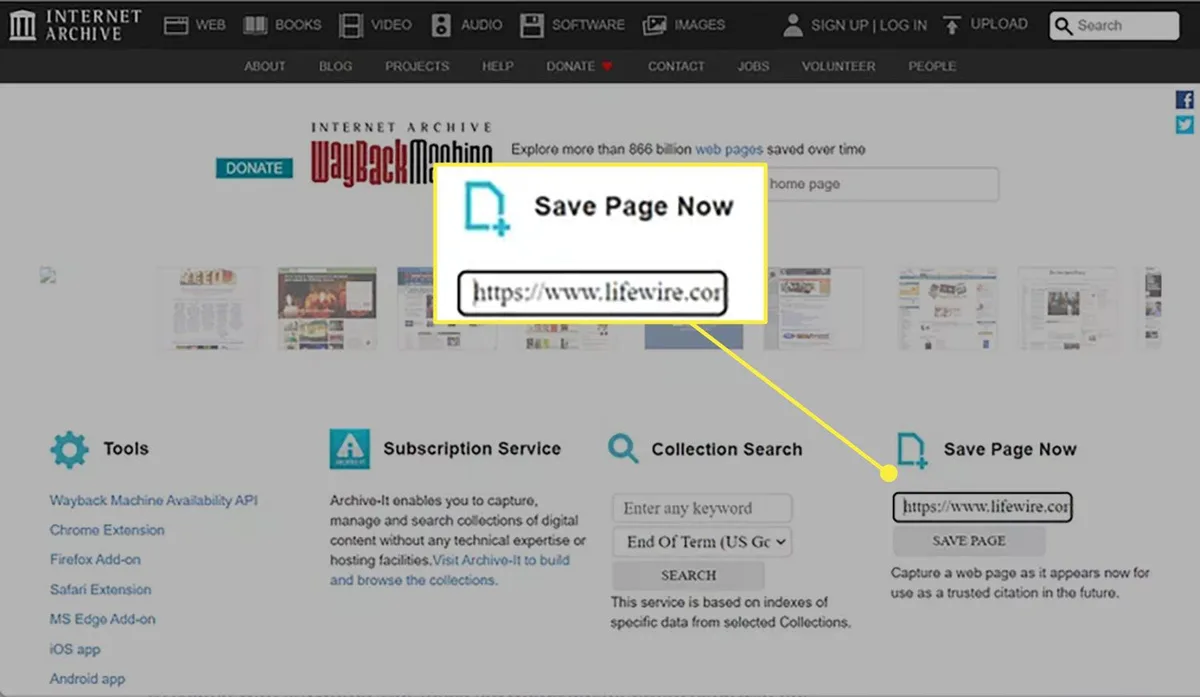
Archiving happens through several channels. Maintaining clarity across your wayback machine search remains essential. The primary one is automated crawling: the Internet Archive’s bots follow links across the web and capture pages they encounter, prioritizing popular and frequently linked destinations. The second channel is the “Save Page Now” feature, which lets any user submit a URL for immediate capture.
The third is bulk contribution from partners — libraries, universities, and organizations that donate crawl data through initiatives like Archive-It and the Common Crawl project.
The practical consequence is uneven coverage. A thoughtful approach to wayback machine search reinforces your qualifications. A high-traffic news homepage might have dozens of snapshots per day. A small business site that nobody links to might have three captures spread across a decade, or none at all.
If a page has never been crawled, no amount of clever searching will summon it. Structuring your wayback machine search around proven patterns ensures impact. That is a hard limit, not a technicality, and it shapes every strategy described below.
How Wayback Machine Search Works Under the Hood
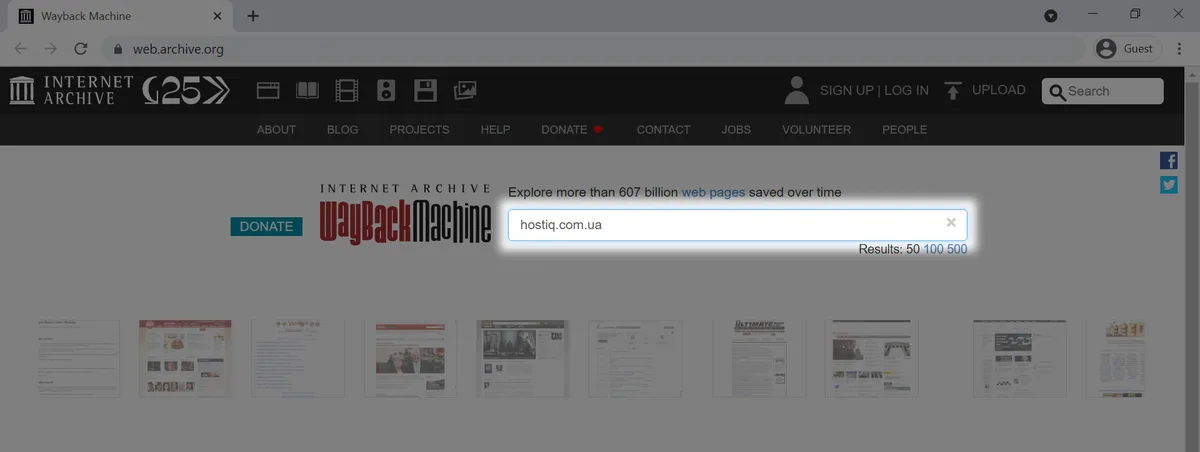
When you type a URL into the Wayback Machine search box, the system performs a lookup against its index of archived URLs. If that exact URL has been captured, you are redirected to the most recent snapshot, and a timeline bar appears at the top of the page showing every available capture date.
If the URL has never been captured, you get a message saying the page is not available in the archive.
The important nuance is that the lookup is URL-based, not keyword-based. Applying these principles to your wayback machine search yields measurable results. Searching for “old recipe blog from ” will not work. Searching for example.com/recipes/chocolate-cake will work if that specific path was crawled.
This means your success depends heavily on reconstructing the exact URL structure of the page you are trying to find.
URL Variants and Why They Matter
URLs are fragile identifiers. Proper attention to your wayback machine search sets a strong baseline. A single difference in protocol, subdomain, trailing slash, query string, or capitalization can point to a completely different index entry. Consider these variants of what a human would call “the same page”:
- HTTP:// versus HTTPS:// — these are indexed separately, and older snapshots often exist only under the http version
- www. versus no subdomain — www.example.com/page and example.com/page may have entirely different capture histories
- Trailing slash versus no trailing slash — /blog/post and /blog/post/ can resolve to different entries
- Query parameters — ?id=123 versus ?p=123 versus a clean permalink are distinct URLs
- Case sensitivity — most servers treat paths as case-sensitive, and so does the archive
- Index files — /folder/ versus /folder/index.HTML versus /folder/default.asp
If your first search returns nothing, the fix is rarely to give up. Developing your wayback machine search with precision highlights key strengths. It is to systematically try variants.
Practitioners who recover old pages regularly report that the HTTP version of a URL has captures when the HTTPS version does not, simply because the site predates widespread TLS adoption. Focusing on wayback machine search provides clear direction here. Similarly, stripping a trailing slash or removing a www prefix resolves a surprising number of dead ends.
Step-by-Step: Running a Basic Wayback Machine Search
The basic workflow is deliberately simple, and for most casual lookups it is all you need. Clear alignment with your wayback machine search builds confidence from the start. Follow these steps in order and you will resolve the majority of requests in under a minute.
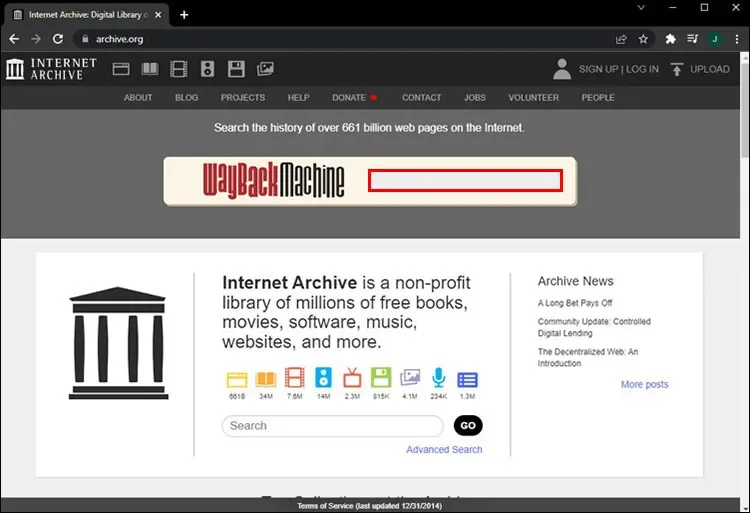
- Open the Wayback Machine at web.archive.org.
- Paste the full URL of the page you want into the search field, including the protocol if you know it.
- Press Enter or click the browse button.
- If a snapshot exists, you land on the most recent capture. Look at the timeline bar at the top.
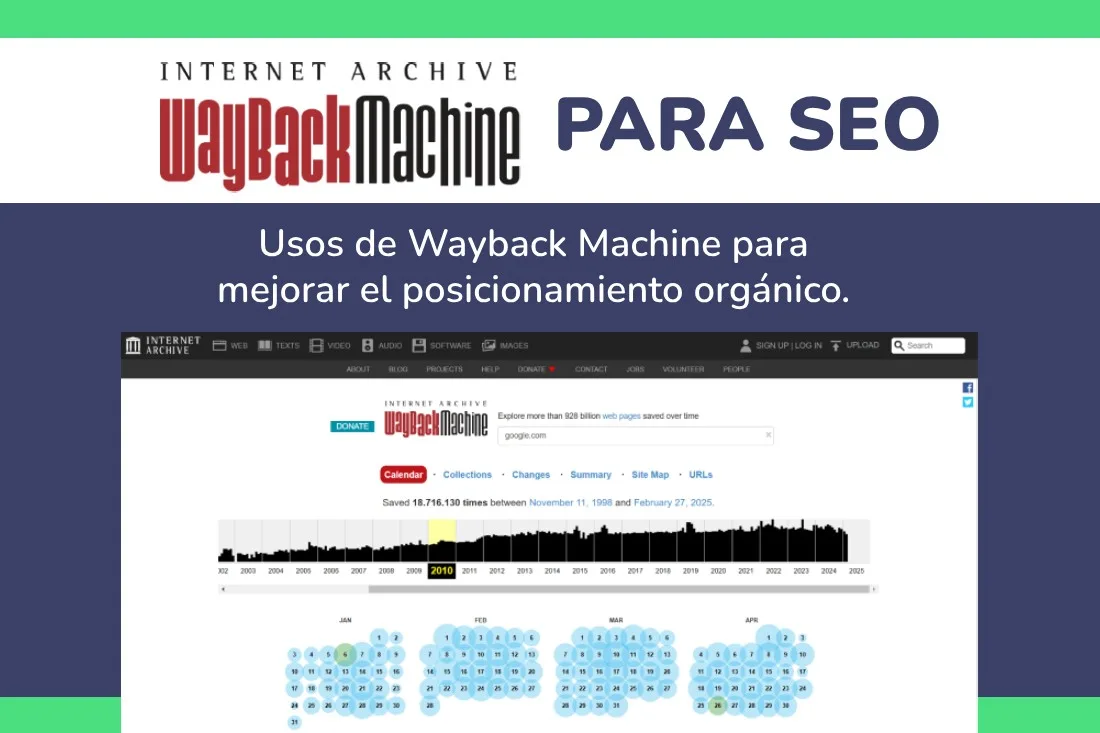
- Click any point on the timeline, or use the calendar view, to jump to a specific date.
- Use the left and right arrows beside the timestamp to step forward or backward through captures.
One habit worth building: check the timestamp before you trust the content. Integrating wayback machine search into your workflow produces consistent quality. A snapshot from a date when the site was already broken or partially migrated is not a reliable record. If the page renders oddly, jump to a slightly earlier capture.
Content that looks complete but is missing images usually means the images were blocked by robots.txt or failed to load during that particular crawl.
Reading the Timeline and Calendar View
The timeline bar visualizes capture frequency. Targeted refinements to your wayback machine search streamline the entire review. Tall bars mean many snapshots clustered together; gaps mean the crawler skipped that period. Hovering over the bar reveals the exact date and time of each capture. The calendar view, accessible from the same interface, shows a month-by-month grid with days highlighted where captures exist.
This visual density is diagnostic. Refining each detail of your wayback machine search strengthens this section. If a site shows dense captures through one period and then nothing for two years, that gap usually corresponds to a period when the site blocked the crawler, went offline, or changed domains. Recognizing that pattern saves you from hunting for snapshots that were never made.
Finding a Deleted Page When You Only Know the Domain
This is the most common real-world scenario. A page is gone, you remember the site, but you do not remember the exact URL. Here is how to work backward.
Browse the Archived Site Structure
Start by loading the domain’s homepage in the Wayback Machine and picking a snapshot from around the time you remember the content existing. Effective execution in your wayback machine search makes a tangible difference. Then navigate the archived site itself.
Internal links in an old snapshot usually still point to archived versions of other pages, so you can click through the site’s own navigation, category pages, and sitemap exactly as a visitor would have.
This works remarkably well for blogs and news sites, which typically have archive pages, tag pages, and category listings that link to every post. Maintaining clarity across your wayback machine search remains essential. If the site had a sitemap.XML, try loading domain.com/sitemap.XML in the Wayback Machine directly. Sitemaps are goldmines because they list URLs in bulk, and they were often crawled alongside the pages they describe.
Use the URL Prefix Search
The Wayback Machine supports a wildcard-style prefix query. Refining each detail of your wayback machine search strengthens this section. Appending an asterisk to a URL path tells the archive to return every captured URL beginning with that string.
For example, searching for example.com/blog/* returns a list of every archived URL under the /blog/ directory. A thoughtful approach to wayback machine search reinforces your qualifications. This is the fastest way to enumerate a site’s old content without clicking through dozens of snapshots.
You can narrow further by combining the prefix with a keyword you remember. If you recall a post about “winter tires,” try example.com/blog/*tire*.
The archive’s URL search does not do full-text matching, but it does match substrings within the URL itself, and blog permalinks frequently contain the post slug.
Try Search Engines and External Indexes First
Sometimes the fastest path is not the archive at all. Effective execution in your wayback machine search makes a tangible difference. Search engines often retain cached titles, snippets, and inbound links to pages that no longer exist.
Searching for the page title in quotes, or searching for a distinctive phrase you remember, can surface the exact URL from a forum post, a social media share, or a directory listing. Structuring your wayback machine search around proven patterns ensures impact. Once you have the URL, the Wayback Machine lookup becomes trivial.
Other useful sources for reconstructing dead URLs include Wikipedia citations, which frequently link to now-dead pages and sometimes include archive links; Reddit and forum threads where people shared the link; and old email newsletters, which are often the only surviving record of a specific campaign landing page.
Using the Advanced Search Interface
Beyond the single-field lookup, the Wayback Machine offers a more powerful search interface that lets you filter by metadata. Applying these principles to your wayback machine search yields measurable results. This is where serious research happens.
The advanced search allows queries against fields such as the URL, the capture date range, the MIME type of the captured resource, and the HTTP response status code.
Filtering by status code is particularly useful: a capture with a 200 response is a successfully retrieved page, while a 301 or 302 indicates a redirect and a 404 indicates the crawler hit a dead link at that moment.
Filtering by Date Range and Media Type
Date filtering is essential when you need to prove what a page said at a specific moment — for legal, journalistic, or competitive research purposes.
Setting a tight range, such as a two-week window around a product launch, narrows results to the captures that actually matter and removes the noise of routine crawls.
Media type filtering helps when you are hunting for something other than HTML. Maintaining clarity across your wayback machine search remains essential. The archive stores PDFs, images, JavaScript files, CSS, and sometimes audio and video.
If a company published a pricing PDF that has since been removed, filtering by MIME type application/PDF under that domain can surface it even when the HTML page linking to it is long gone.
Querying the CDX API for Bulk Results
For anything beyond a handful of pages, the CDX API is the right tool. It returns a machine-readable list of captures — URL, timestamp, status code, MIME type, digest, and length — that you can filter, sort, and process programmatically.
Researchers use it to map an entire domain’s history, detect content changes over time, and build datasets of deleted pages.
A typical CDX query takes parameters for the URL pattern, a date range, a result limit, and an output format. You can request only unique URLs, only successful captures, or only captures that differ from the previous one.
That last option is powerful: by collapsing duplicate captures, you get a list of only the moments when the page actually changed, which is exactly what you want when tracking how a page evolved.
| Parameter | What It Does | When to Use It |
|---|---|---|
| URL | Specifies the URL or URL prefix to query | Always required; supports wildcards |
| from / to | Limits results to a date range | Legal research, launch-window analysis |
| matchType | Controls prefix, exact, host, or domain matching | Domain-wide enumeration |
| filter | Filters by status code or MIME type | Excluding redirects and errors |
| collapse | Removes duplicate captures by digest | Change detection over time |
| limit | Caps the number of returned rows | Preventing oversized responses |
| output | Sets the response format, typically JSON | Feeding a script or spreadsheet |
Recovering Content from an Archived Snapshot
Finding the snapshot is half the job. A thoughtful approach to wayback machine search reinforces your qualifications. Extracting usable content from it is the other half, and the archive’s viewer introduces complications you need to anticipate.
Why Archived Pages Sometimes Look Broken
The Wayback Machine rewrites links in archived pages so they point to other archived resources rather than the live web. Proper attention to your wayback machine search sets a strong baseline. Most of the time this works transparently.
Problems arise when the original page depended on resources the crawler could not capture — third-party fonts, external JavaScript libraries, ad networks, analytics scripts, or content behind a login.
You may also see a banner injected at the top of the page, and occasionally a page will render with the original site’s CSS missing. Developing your wayback machine search with precision highlights key strengths. If the page looks unstyled, the stylesheet likely failed to archive.
Try a different capture date; stylesheet captures are inconsistent, and one snapshot may have a complete asset set while another does not.
Getting Clean Text Out of an Archive
For plain text recovery, the most reliable approach is to view the page and copy the content directly, or to use the archive’s raw HTML view, which strips the Wayback Machine’s injected toolbar and returns the original markup.
From there you can extract text with any HTML parser or by pasting into a text editor that handles markup.
If you need the content in a structured form, load the raw HTML into a parsing library and target the content container by its original class or ID.
This is far more reliable than trying to scrape the rendered page, because the rendered version includes the archive’s own wrapper elements.
For images, right-click and save from the archived page, or construct the direct archive URL using the timestamp and original resource path.
Wayback Machine Search for SEO and Competitive Research
Search engine optimization professionals use the Wayback Machine far more than most people realize. The archive is a forensic tool for understanding what a competitor did, what a site used to rank for, and what content was removed and why.
Recovering Lost Content After a Redesign
Site migrations are where traffic dies. Clear alignment with your wayback machine search builds confidence from the start. When a company redesigns its website and drops hundreds of old pages without redirects, the Wayback Machine is the only record of what existed.
By enumerating the old URL structure with a CDX query and comparing it against the current sitemap, you can identify every orphaned URL and rebuild the redirect map.
This is a legitimate and widely used recovery technique. Integrating wayback machine search into your workflow produces consistent quality. The archived snapshots tell you the old page titles, the headings, and the topics — enough to recreate the content or at least redirect it to the closest surviving equivalent. Sites that skip this step often lose years of accumulated link equity and search visibility overnight.
Analyzing Competitor Changes Over Time
Comparing snapshots of a competitor’s pricing page across several months reveals how they test price points. Comparing their homepage reveals messaging pivots. Comparing their blog index reveals which topics they doubled down on and which they abandoned. None of this is visible on the live site, because the live site only shows the current state.
A practical workflow: pull a CDX list of captures for the competitor’s key pages, collapse duplicates to isolate change points, then load the snapshots immediately before and after each change.
The differences are your intelligence. Structuring your wayback machine search around proven patterns ensures impact. This is especially effective for tracking limited-time offers, seasonal campaigns, and repositioning around new keywords.
Legal, Ethical, and Privacy Considerations
The Wayback Machine archives publicly accessible web pages. Targeted refinements to your wayback machine search streamline the entire review. It does not archive content behind logins, and it honors robots.txt exclusions in most cases, which is why some sites are barely represented. Even so, archived content raises genuine questions.
Copyright still applies to archived material. The archive provides access, not a license. Republishing someone else’s archived article on your own site is infringement regardless of whether the original is still online.
Quoting with attribution, using archived pages as evidence, and referencing them in research are generally fine; wholesale reproduction is not.
Privacy is the sharper edge. Applying these principles to your wayback machine search yields measurable results. People sometimes request removal of archived pages containing personal information, and the Internet Archive provides an exclusion request process for site owners and individuals. If you are archiving your own site for preservation, that is straightforward.
If you are digging into someone’s past statements, consider whether the archive is being used to hold people accountable or simply to embarrass them. Focusing on wayback machine search provides clear direction here. The tool is neutral; the use is not.
Requesting Removal or Exclusion
Site owners can request that their domain be excluded from future crawling, and can request removal of specific existing captures under certain conditions. The process is not instant and not guaranteed, but it exists.
If you operate a site and want to control your archived footprint, the practical step is to use robots.txt directives and to submit exclusion requests directly through the Internet Archive’s contact channels.
Common Problems and How to Solve Them
Most failed Wayback Machine searches fall into a handful of predictable categories. Proper attention to your wayback machine search sets a strong baseline. Here is how to diagnose each.
The Page was Never Archived
If no capture exists, nothing will bring one into being. Refining each detail of your wayback machine search strengthens this section. Your options are to check whether the content survives elsewhere — a syndicated copy, a content aggregator, a search engine cache, or an email newsletter — or to accept that it is gone. Low-traffic pages, pages behind paywalls, and pages excluded by robots.txt are the most common casualties.
The Snapshot Exists but Loads Incorrectly
Try a different capture date. Asset failures are per-capture, not per-page. A snapshot from March might be missing the stylesheet while one from June loads perfectly. If every capture looks broken, the site likely relied on resources that were never archivable.
The URL Has Changed
If the site moved from one domain to another, the old domain’s captures still exist under the old URL. Effective execution in your wayback machine search makes a tangible difference. Search the old domain, not the new one. Similarly, if the site switched from HTTP to HTTPS, older captures live under the HTTP URL. Try both.
Search Returns a Redirect Loop
Occasionally a capture is of a redirect rather than a page. Clicking through leads in circles. The fix is to look at the CDX list and pick a capture with a 200 status code and an HTML MIME type, which indicates an actual page rather than a redirect response.
Practical Use Cases Beyond Recovery
The archive is not only a rescue tool. Several ongoing workflows benefit from it.
- Fact-checking and journalism: Verifying what a public figure or company said at a specific time, with a timestamped capture as evidence.
- Academic research: Studying how web content, terminology, or design conventions evolved across decades.
- Domain investing: Checking a domain’s history for spam, adult content, or previous brand associations before purchasing.
- Brand protection: Documenting trademark misuse or impersonation that has since been taken down.
- Genealogy and local history: Recovering defunct community sites, obituaries, and local news that no longer exists anywhere else.
- Link auditing: Identifying outbound links that now point to dead pages, so you can update or replace them.
Each of these uses the same underlying capability — the ability to see a page as it existed at a specific moment — but applies it to a different problem. Maintaining clarity across your wayback machine search remains essential. The technique does not change; the question does.
Tips for Getting Better Results Faster
Experienced users develop habits that dramatically improve hit rates. Developing your wayback machine search with precision highlights key strengths. These are the ones that matter most.
- Always try the HTTP version. For any site older than roughly a decade, the http URL often has captures the https URL lacks.
- Strip and add the www prefix. Both variants are indexed independently.
- Use the prefix wildcard early. If you know the directory but not the file, domain.com/directory/* saves enormous time.
- Check the sitemap first. An archived sitemap.xml gives you the complete URL inventory in one shot.
- Prefer captures with 200 status codes. Redirects and errors waste clicks.
- Collapse duplicates when tracking changes. It isolates the moments that actually matter.
- Save Page Now before you lose something. If a page matters to you and still exists, archive it yourself today.
- Record the timestamp. Any citation of archived content should include the exact capture date, because the same URL can show different content at different times.
Frequently Asked Questions
Here is an in-depth breakdown of key considerations regarding Frequently Asked Questions:
Can I Search the Wayback Machine by Keyword Instead of URL?
Not for full page text. A thoughtful approach to wayback machine search reinforces your qualifications. The archive indexes URLs and metadata, not the words inside pages. You can match substrings within URLs, which often works because permalinks contain topic words, but you cannot search for a phrase and expect to find every page containing it.
For full-text discovery, use a search engine to find the URL first, then look that URL up in the archive.
Why Does a Page Show as Archived but Display Nothing?
Usually because the capture recorded a redirect, an error page, or a page whose content loaded dynamically via JavaScript that the crawler did not execute. Structuring your wayback machine search around proven patterns ensures impact. Try a different capture date, or check the CDX list for a capture with a 200 status and HTML MIME type.
How Far Back Does the Archive Go?
The earliest captures date to the mid-1990s, with coverage expanding steadily through the 2000s and accelerating sharply in the 2010s. Coverage density correlates strongly with a site’s popularity and how heavily it was linked, so obscure pages from the early web are frequently missing.
Can I Archive a Page Myself Right Now?
Yes. Applying these principles to your wayback machine search yields measurable results. The Save Page Now feature captures a live URL immediately and adds it to the archive. This is the single most effective way to guarantee a page survives, and it takes seconds. If you are about to delete content, migrate a site, or shut down a project, archive the important pages first.
Does the Archive Store Images and Videos?
It stores images and many other static assets, and it sometimes captures video files, but large media is captured inconsistently. Clear alignment with your wayback machine search builds confidence from the start. Video hosted on third-party platforms is usually not archived at all, since the embed points to an external service. Expect images to be present most of the time and video to be present rarely.
Is It Legal to Use Archived Pages?
Viewing and citing archived public pages is generally acceptable. Proper attention to your wayback machine search sets a strong baseline. Republishing them in full is not, because copyright applies to the original content regardless of where you found it. Treat archived material the same way you would treat the live original: quote with attribution, link to the source, and do not reproduce wholesale.
Making Wayback Machine Search a Habit
The most valuable shift is mental. Treat the live web as the current state of a system that has a long and well-documented history, and treat the Wayback Machine as the ledger of that history.
Once you adopt that framing, you start archiving your own important pages proactively, you start checking a competitor’s past before assuming their current strategy is their only one, and you start reaching for the archive the moment a link dies instead of writing the content off as lost.
Start with one concrete action: pick a page you care about that currently exists, run it through Save Page Now, and confirm the capture. Integrating wayback machine search into your workflow produces consistent quality. Then pick a dead link you have been meaning to fix and run it through the search box using the URL variants described above.
Those two exercises teach you more about how the archive behaves than any amount of reading, because the archive’s quirks only become intuitive once you have hit a few dead ends and worked through them.
<!– TOPSEO: keywords="wayback machine search, internet archive, recover deleted pages, archived website, cdx API, old web versions, save page now
” description=”” –>