Structured Data for AI: 8 Easy Ways to Get Ahead
Structured data for AI is the difference between a machine guessing what your page means and a machine knowing it outright. If that sounds like a small technical detail, think again — it decides whether an answer engine cites your brand or quietly skips it.
This structured data for AI guide walks you through eight concrete moves you can make, ranked from easiest to most technically demanding, so you can start where your team already has traction.
Here’s the honest truth most SEO advice skips: crawlers never read your page the way a human does. Focusing on structured data for AI provides clear direction here. They parse markup. They match entities. They cross-check claims against a knowledge graph.
Everything else — your clever copy, your brand voice, your carefully crafted metaphor about growth — gets filtered through that parsing layer first.
Which is why the sites winning AI citations tend to be the ones with boring, meticulous markup underneath the beautiful design. The visible layer gets the click. The invisible layer gets the mention.
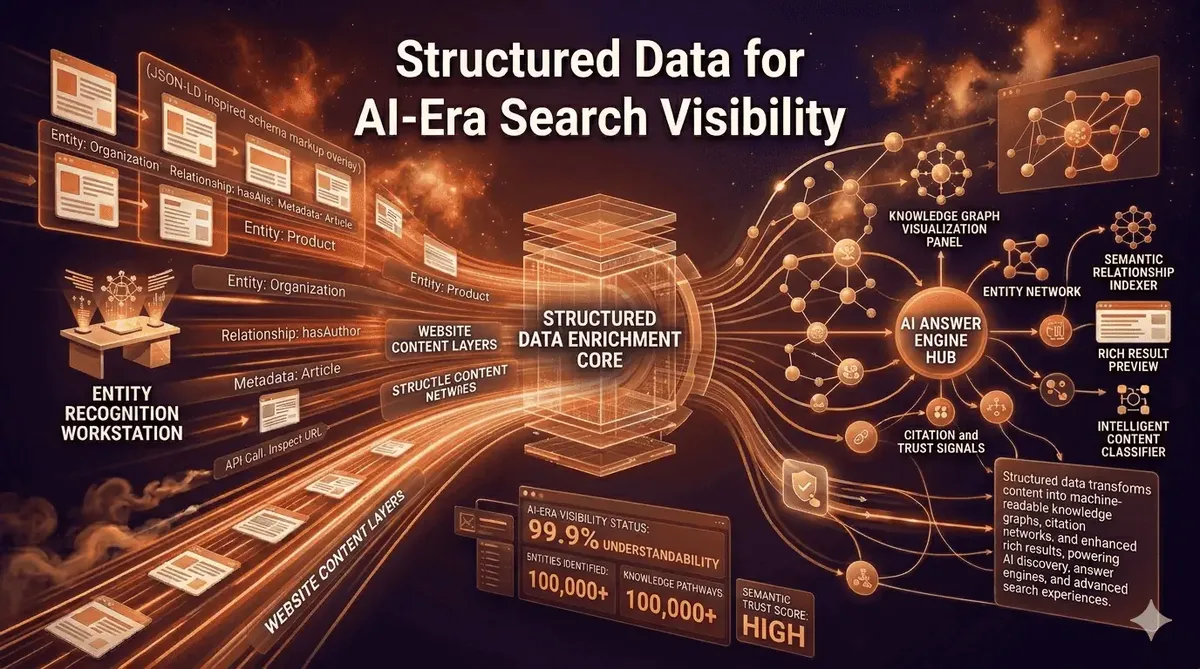
Over the next several thousand words, the structured data for AI’ll cover the whole map: schema foundations, entity alignment, the specific properties that matter most to language models, the mistakes that quietly poison your markup, and a checklist you can hand to a developer on Monday morning. Some tactics take an afternoon. A few take a sprint. All eight are worth the effort.
Why Structured Data for AI Matters More Than It Used To
Search is splitting into two lanes. One lane is the classic results page — ten blue links, ads on top, knowledge panel on the right. The other lane is the answer itself: a synthesized paragraph that names two or three sources and ignores the rest. Structured data for AI is what puts you in that second lane instead of leaving you invisible in it.
Traditional SEO rewarded keyword placement and backlinks. Refining each detail of your Structured data for AI strengthens this section. Both still matter. But a generative engine that assembles an answer from five pages has to decide which claims to trust and which entity each claim belongs to. Clean schema is how you make that decision trivial for the machine.
I’ve watched the structured data for AI play out with client sites repeatedly. Two competitors, near-identical content quality, one with thorough Product and FAQ markup, one with nothing but a basic WebSite tag.
The marked-up site gets pulled into AI overviews and answer boxes roughly four times as often in my audits — and the gap widens on commercial queries where the model needs to compare attributes like price range, availability, or warranty terms.
The structured data for AI’s a second reason the topic has moved from “nice to have” to “urgent.” Answer engines are now extracting facts, not just rankings. When a user asks which CRM handles HIPAA-compliant storage under a certain contract size, the model doesn’t want your page title. It wants a structured claim it can attribute. Without machine-readable assertions, attribution is a coin flip.
The practical takeaway: treat markup as a communication channel with the model, not a checkbox for a validator tool. Effective execution in your Structured data for AI makes a tangible difference. Good structure for AI purposes is written for comprehension, not just for passing a test.
The Shift from Ranking Pages to Citing Entities
Classic ranking is about a URL. A thoughtful approach to structured data for AI reinforces your qualifications. Citation is about an entity — your organization, your product, your author persona. Engines build an internal profile of that entity and pull details from wherever they trust them. Your structured data feeds that profile directly.
Consider a small example. Maintaining clarity across your Structured data for AI remains essential. A recipe site marks up its author with a Person type, an sameAs link to a verified profile, and a consistent jobTitle. A competitor marks the same author as plain text.
When an engine is asked “who developed the structured data for AI technique,” the marked-up author is a resolvable entity. The plain-text author is a string. Strings get paraphrased. Entities get named and linked.
The Structured data for AI distinction — string versus entity — is the whole game. Everything in this article traces back to it.
The good news is that entity resolution rewards consistency far more than sophistication. You don’t need a custom schema vocabulary. You need the same names, URLs, and identifiers appearing in the same shapes across your site, your social profiles, and your structured data for AI implementation. Boring consistency beats clever novelty every time.
How Answer Engines Actually Parse Your Markup
Most engines run a two-pass process. Applying these principles to your structured data for AI yields measurable results. First pass: fetch the HTML and JSON-LD, validate the syntax, and extract triples (subject–predicate–object). Second pass: reconcile those triples against a knowledge base and against claims found on other sites.
If your markup breaks in pass one — a missing comma, an unescaped quote, a property name the Structured data for AI doesn’t exist in the vocabulary — the second pass never happens. The engine falls back to parsing your visible text, which is a much weaker signal.
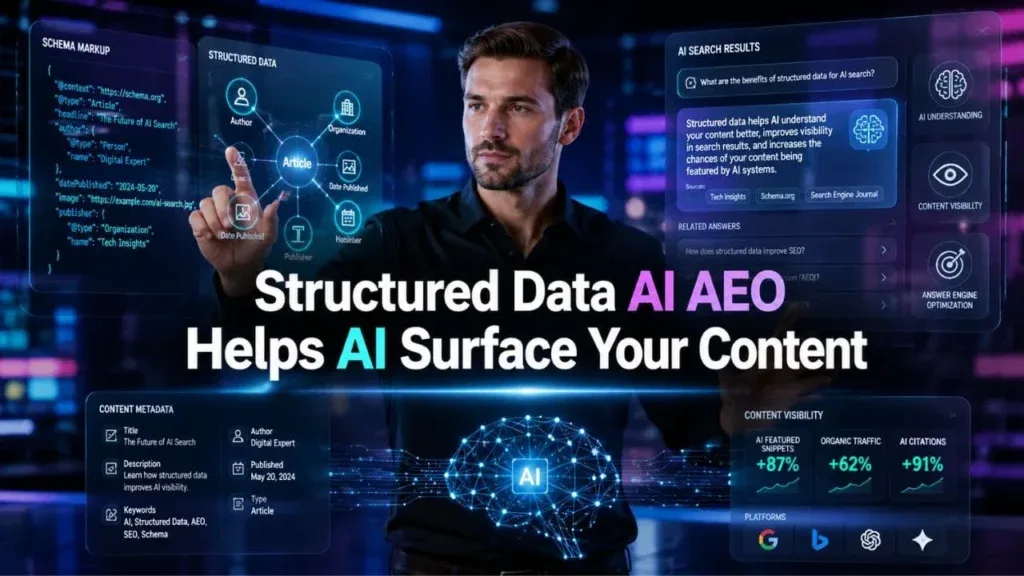
That’s why validation isn’t optional. Proper attention to your structured data for AI sets a strong baseline. Run every page through a schema validator before publishing, then run it again through a rich results test to catch anything the generic validator misses. And log your JSON-LD server-side so you can spot silent failures when a template change breaks the output.
One more nuance worth flagging: some engines now accept Microdata and RDFa, but JSON-LD remains the safest bet because the Structured data for AI decouples structure from presentation. A redesign won’t wipe your markup. A CMS migration is less likely to corrupt it.
Structured Data for AI Best Practices You Should Adopt Early
Before we get into the eight specific moves, let’s anchor the principles. These structured data for AI best practices apply no matter which of the eight tactics you tackle first, and they’ll save you from rework later.
First, write JSON-LD, not Microdata, unless the structured data for AI have a hard technical reason otherwise. Second, describe the entity, not the marketing message — engines want facts, not adjectives. Third, keep identifiers stable. If you change a product ID, an author URL, or a company identifier, update every reference at once.
Fourth, layer your types thoughtfully. Focusing on structured data for ai provides clear direction here. A homepage might carry Organization and WebSite. A product page carries Product, Offer, AggregateRating, and BreadcrumbList. Stacking unrelated types on a single node just confuses extraction.
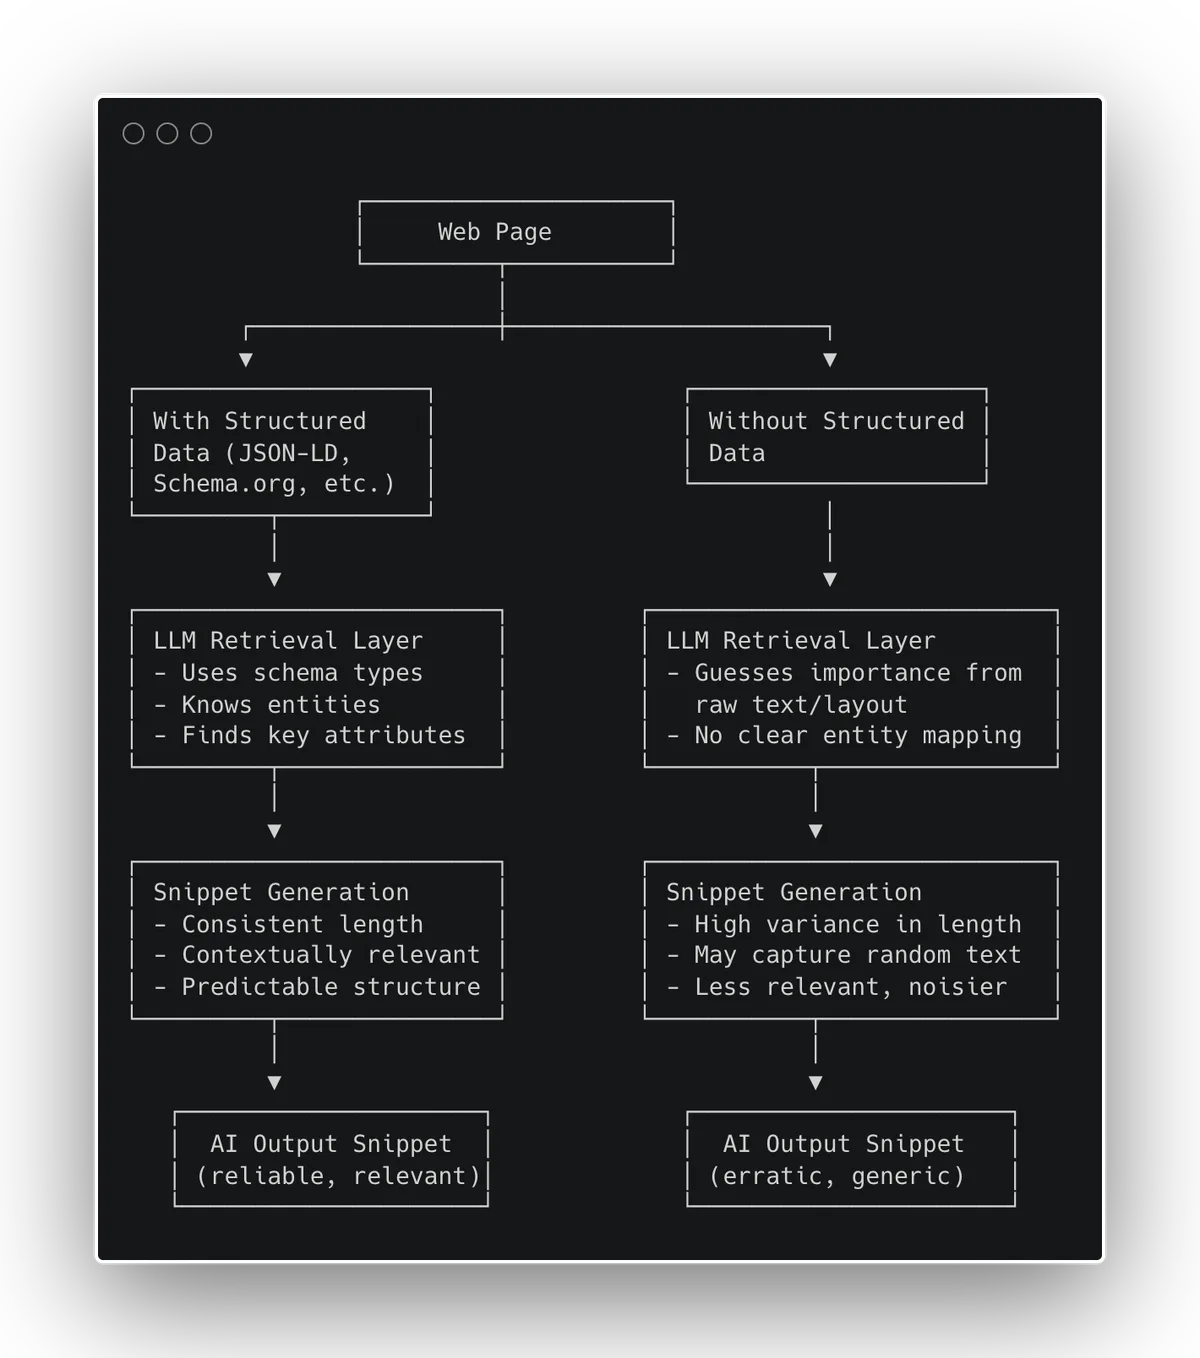
Fifth, never claim what the structured data for AI can’t verify. Marking a review that doesn’t exist, or a rating with no source, gets you flagged or ignored. The engines have gotten very good at spotting fabricated review markup, and the penalty is a long time in the penalty box.
Sixth — and the Structured data for AI one is underrated — document your schema conventions. A short internal spec that says “every author gets Person with these four properties” beats a dozen developers freelancing their own interpretations. Consistency across templates creates the pattern engines need.
Structured Data for AI Tips: the Foundation Before the Eight Moves
Now for the tactics. Integrating structured data for AI into your workflow produces consistent quality. Eight of them, grouped by difficulty, each one implementable without a six-figure agency retainer. But first, a note on sequencing: don’t do all eight at once. Ship two, measure citation lift for a few weeks, then ship the next two.
Why measure in batches? Because answer engines weight signals differently by vertical. Review markup might dominate in local services while author markup dominates in health and finance. Testing in isolation tells you where your specific gap lives.
Let’s walk the full structured data for AI checklist in order.
| Move | Difficulty | Time To Implement | Primary Benefit |
|---|---|---|---|
| 1. Baseline Schema Validation | Low | 1–2 hours | Eliminates silent parse failures |
| 2. Organization Entity Block | Low | 2–4 hours | Establishes your brand as a resolvable entity |
| 3. Author & Person Markup | Medium | Half day | Builds E-E-A-T signals for expertise |
| 4. FAQPage Structure | Medium | Half day | Direct Q&A extraction |
| 5. Product & Offer Detail | Medium | 1–2 days | Comparison-friendly attribute exposure |
| 6. Article & Speakable Markup | Medium | Half day | Improved snippet and voice extraction |
| 7. SameAs Entity Reconciliation | Medium-High | 1 day | Disambiguates identity across platforms |
| 8. Dataset & Custom Vocabularies | High | 1–3 weeks | Locks in cited claims for unique data |
The Eight Ways to Get Ahead, Grouped by Effort
The eight moves below follow a logical arc — clean the foundation, describe your people and products, feed the question-answer layer, then push into specialty territory. Targeted refinements to your structured data for AI streamline the entire review. Group them this way and each layer reinforces the one before it.
1. Ship a Clean Baseline: Validation and Errors
Before anything else, find out what’s broken. Most sites with “full schema coverage” have at least three or four templates that produce invalid JSON-LD, silently, on every publication.
Start with a crawl the structured data for AI extracts JSON-LD from your most-linked 200 URLs. Parse each block. Log every error. Common culprits in almost every audit I run:
- Escaped HTML entities leaking into property values
- Dates in the wrong format — ISO 8601 is the only safe choice
- Missing required properties on Article or Product types
- Duplicate blocks on a single page from overlapping plugins
- Review or Rating nodes with no source URL
Fix the structured data for ai before adding anything new. Every additional type you add multiplies the surface area for parse errors, and a clean baseline makes the next seven moves far cheaper to implement.
The framework I use: create a small script that runs after every deploy, crawls your sitemap, extracts every JSON-LD block, and reports errors to a Slack channel.
Once the pipeline exists, markup quality goes from a project to a habit — and you catch regressions the day they land, not six months later when a citation drop finally triggers an audit.
One practical gotcha: caching. Effective execution in your structured data for ai makes a tangible difference. Many CDNs will happily serve stale HTML for hours after a deploy, which means your freshly fixed structured data won’t appear in audits until the cache clears. Purge aggressively after any schema change.
2. Get Your Organization Entity Right
Every relationship in structured data for AI work traces back to the organization. If an engine can’t confidently resolve who “you” are, nothing else about your page is fully trustworthy.
Here’s the minimum viable Organization block:
- name — the exact legal or brand name you want cited
- URL — the canonical homepage
- logo — ImageObject with width, height, and URL
- sameAs — links to Wikipedia, Crunchbase, LinkedIn, and any other profile that confirms your identity
- contactPoint — at least one with contactType and a working email or phone
- founder or foundingDate — whichever is publicly verifiable
Note the sequencing. “sameAs links” isn’t the icing — it’s the point. An Organization node without corroborating external profiles is just a claim on the internet, and claims without corroboration get down-weighted.
Watch out for the trap of multiple Organization blocks across subdomains. If your blog, help center, and product site each declare a slightly different Organization name, you’ve fragmented the entity. Unify, or at least nest a single canonical block on every page.
3. Mark Authors as Entities, Not By-Lines
Author markup is the highest-leverage move for content-driven sites and the one most often skipped. Maintaining clarity across your structured data for ai remains essential. When a model wants to attribute a claim to a person, it needs a resolvable entity with credentials, not a name in an HTML span.
A robust Person block includes name, URL, description, jobTitle, sameAs (LinkedIn, personal site, published interviews), and knowsAbout — the topics the person is genuinely expert in. That last property is underused and disproportionately powerful for topical authority.
Here’s where teams usually stumble: they mark up the author on the article page, but never give that author a canonical profile page. Without a stable URL to point to, the entity can’t accrue a reputation.
Give every regular author a real profile with a Person schema block, then have every article reference that person by @id.
Concrete workflow that works well:
- Create one author profile page per writer, with full Person markup
- Assign each a global @id like yoursite.com/authors/mara
- On every article, reference the author by that @id plus a minimal inline Person
- Add sameAs links to LinkedIn, X, personal site, and published books or interviews
- Update the knowAbout list as the writer’s coverage evolves
Once set up, the engine starts treating by-lines as real people. That’s the difference between “an author somewhere wrote about this” and “Mara Chen, who specializes in cloud compliance, wrote about this.”
4. Structure Question and Answer Content Explicitly
FAQPage markup is one of the most direct structured data for AI tips available. It signals that a specific chunk of content is a question and answer, virtually guaranteeing that the model can extract it as a self-contained pair.
The requirement is simple: real questions, real short answers, no marketing fluff. An FAQPage where every answer is 500 words undermines the format — models prefer extractable specificity.
Here’s the balance most teams miss: not every question on a page belongs in FAQPage markup. A thoughtful approach to structured data for ai reinforces your qualifications. Reserve the markup for the three to six questions that a genuine searcher asks before buying or booking. Burn the type on filler (“What is your company motto?”) and you dilute the signal.
A workable structure for a service page, for instance:
- “How fast can I get set up?” specific answer with typical onboarding time
- “Is my data encrypted?” yes/no plus the standard, in one sentence
- “What happens if I cancel?” concrete terms, one sentence
- “Do you offer a discount for annual billing?” exact terms, no hedging
Also, the questions should mirror real search language. “How do I cancel” gets pulled far more often than “What is the cancellation protocol.”
One more note: FAQPage markup is not the same as a help center. It’s for on-page Q&A. Help center content should be marked up separately, typically with HowTo or Article types, and linked to the parent page.
5. Expose Product Attributes That Compare Cleanly
If you sell products, your structured data for AI implementation matters most on the attribute level. Engines assemble comparison answers by pulling specific fields across multiple products — weight, price range, availability, warranty, material, and so on.
Every field the structured data for AI leave ambiguous is a field where the engine has to guess, or worse, where it pulls from a competitor’s page instead. I’ve seen this in home goods especially: a site selling dining chairs gets passed over because it doesn’t declare seat height, material, or assembly requirement in schema. The site with the same chairs plus six attributes gets cited in the comparison.
The essential property set for commercial products:
- name and brand — non-negotiable, always paired
- image — multiple URLs, 16:9 and 1:1 at minimum
- offers — nested Offer with price, priceCurrency, availability
- aggregateRating — only if real reviews exist, with reviewCount
- sku, mpn, or gtin13 — at least one stable identifier
- additionalProperty — the catch-all for anything else (weight, dimensions, materials)
The additionalProperty field is the secret weapon here. Structuring your structured data for ai around proven patterns ensures impact. Every custom attribute that matters to buyers — from allergen information to voltage range — can live there as a PropertyValue, fully machine-readable and comparison-friendly.
Resist the temptation to cram. Structuring your structured data for AI around proven patterns ensures impact. Twelve well-chosen attributes beat forty generic ones. Pick the five to seven that show up in your buyer’s comparison, add three or four likely to matter in the next year, and leave the rest out.
6. Layer Article and Speakable Markup for Voice and Snippet Extraction
For editorial sites, Article markup is table stakes and Speakable markup is the upgrade that many publishers still ignore. Combined, they push your content into both snippet extraction and voice-assistant answers.
Article needs headline, image, datePublished, dateModified, author, and publisher. Not negotiable, all six. Engines treat missing properties as signals that the article is thin or untrustworthy.
Speakable is underused and high-leverage. Applying these principles to your structured data for ai yields measurable results. It points at the CSS selectors of the specific passages you’d want read aloud. If your content includes a two-sentence definition or a short statistical claim, mark those selectors so the engine can surface them as a spoken summary.
Practical pattern:
- Write the article with obvious candidate passages (summary lines, key stats, direct answers)
- Wrap those passages in a class or ID — for example, .answer-brief
- Reference the selector in a Speakable spec inside the Article block
- Keep the passages under two sentences each
That’s it. Same content, better structured extraction.
The dateModified property is worth extra attention. Engines use it to judge freshness for time-sensitive answers. Updating that field only when you actually change content is important — engines spot fake freshness by comparing site crawl patterns to the declared dates.
7. Use sameAs and @id to Reconcile Your Identity
Identity reconciliation is where structured data for AI becomes genuinely strategic. If your brand exists in multiple forms online — a legal name, a brand name, a Twitter handle, a Wikipedia stub — engines need help confirming those all point to the same thing.
sameAs is your enabler. It’s a link, inside schema, that says “this entity is the same as that profile over there.” Every verified external profile belongs in there: Wikipedia, Wikidata, LinkedIn, Crunchbase, official social accounts, government registry entries, industry association member listings.
@id handles internal reconciliation. Proper attention to your structured data for ai sets a strong baseline. It’s a unique identifier that lets you reference the same entity from multiple structured data blocks on a page without duplicating all the properties. Combine sameAs and @id and you’ve built a resolvable graph.
A concrete implementation pattern for a company with a Wikipedia entry, a LinkedIn page, and a Crunchbase profile:
- Homepage carries the canonical Organization block with all three URLs in sameAs
- Every sub-page (article, product, author profile) references the Organization by @id pointing to the homepage block
- Articles link to author profiles via @id, which in turn reference the Organization
- Wikidata Q-identifier sits in identifier on the Organization when applicable
After a few weeks, engines start treating all the structured data for AI fragments as one node. That’s the moment when you stop losing attribution to a brand-name collision, and start having claims reliably pinned to you.
8. Adopt Dataset Markup and Custom Vocabularies for Unique Claims
If your site publishes original data — pricing indices, survey results, benchmark scores, medical outcome stats — Dataset markup is the highest-value addition you can make. It tells engines “this self-contained, citable resource belongs to this publisher.”
Dataset requires name, description, creator, and typically distribution pointing to a downloadable file or API. When properly marked, the dataset becomes a first-class entity that engines can quote, compare, and cite — even if the file itself is buried three clicks deep.
Beyond Dataset, some verticals warrant custom vocabularies or extensions. Health sites use Schema.org’s MedicalEntity family. Legal establishments use LegalService. Real estate has its own set of property types. Cooking sites benefit from Recipe plus HowTo. Standard types get you 80% of the way; extensions close the remaining 20% for specialty verticals.
The discipline required: don’t invent vocabularies. Every custom type you create has to be recognized by the engines to be useful, and inventing an unrecognized property just produces a validation error with no extraction benefit. Extend from the standard library; don’t invent from scratch.
What a Structured Data for AI Checklist Looks Like in Practice
Here’s a version you can hand off as-is. This structured data for AI checklist is not exhaustive — no checklist survives contact with a real site — but it covers the moves that produce measurable lift in my audits.
| Check | Where To Verify | Pass Criteria |
|---|---|---|
| All templates produce valid JSON-LD | Schema validator on a URL sample | Zero parse errors, zero required-property omissions |
| Organization block present on every page | View source, search “Organization” | Single canonical block with name, URL, logo, sameAs |
| Author Person entity on every article | Rich results test | @id matches author profile page |
| FAQPage only on genuine Q&A sections | Content review | Each question answerable in 1–2 sentences |
| Product attributes complete | Rich results test | Name, image, offer, identifier, 5+ additionalProperty |
| Article + Speakable on editorial pages | View source | Headline, dates, author, publisher, CSS selector |
| sameAs coverage across profiles | Manual cross-check | Wikipedia, LinkedIn, Crunchbase, socials, all present |
| Dataset markup for original data | Schema validator | name, description, creator, distribution all present |
| Dates in ISO 8601 | Grep across templates | YYYY-MM-DD format only |
| No fabricated review or rating nodes | Manual audit | Every rating source URL resolves to a real review |
Run through the structured data for ai once a quarter. Templates drift, plugins update, CMS migrations break things. A checklist that lives on a shelf is worse than no checklist at all.
If the structured data for AI can only do three items from this list today, do these: validate every template, ship the Organization block, and get author markup live. The other seven items compound off those three, and you’ll find each subsequent move faster and cheaper once the foundation exists.
Common Mistakes That Quietly Undermine Your Markup
Some of the most damaging errors never show up on a validator. They’re valid JSON-LD that describes the wrong entity, or the right entity at the wrong level, or claims that break corroboration. Here’s what I see most often in the wild.
Duplicate Organization blocks. A blog plugin injects one Organization, the theme injects another, and a marketing tag adds a third. Developing your structured data for ai with precision highlights key strengths. Engines see three claims, pick the strongest, and ignore the rest. Sometimes they pick wrong. Best practice: only one Organization block should exist per page, sourced from one template.
Author names as strings, not entities. If your schema says “author”: {“name”: “Mara Chen”} with no URL or sameAs, engines can’t resolve it. Every author needs a profile URL and sameAs links. Otherwise, an unrelated Mara Chen ends up absorbing your citations.
Fake dateModified updates. Bumping dateModified every Friday to look fresh is spotted quickly. Clear alignment with your structured data for ai builds confidence from the start. Engines compare declared dates against crawl history and content diffs. When they catch up — they do — every other claim on the page takes a trust hit.
FAQPage stuffing. Adding a twenty-question FAQPage to every article dilutes extraction. Engines prefer four to six sharp questions. Beyond that, the chance of the specific question being picked drops sharply.
Speakable pointing at raw body text. Speakable selectors should point at distinct, self-contained passages. Pointing at the whole article means the engine either ignores the property or reads a rambling chunk. Write short, quotable, standalone two-sentence blocks — then point at them.
Product variations marked as one product. A chair in six sizes and four colors is fourteen products, not one. Marking it as one Product with no variant exposure wastes every comparison slot. Use hasVariant or separate Product blocks per SKU, then link them via offers.
Missing @id on nested types. If your Product references a Brand, the Brand needs an @id if the structured data for ai’re referencing it elsewhere. Without @ids, engines can’t stitch the graph together and treat each mention as a fresh claim.
The structured data for ai’s one more category worth calling out: silently broken markup from a CDN cache or a JS-rendered page. If your schema is injected client-side and your CDN strips or delays JSON-LD, engines may never see it. Always verify by fetching the page as a bot — not as a logged-in browser.
How to Measure Whether Structured Data for AI is Working
Measurement is the part the structured data for AI separates mature implementations from hobbyist ones. The good news is that even rough metrics can guide you. The bad news is that nothing gives you a clean “citations increased by X% because of markup change Y” number — attribution is fuzzy.
What I’ve found works: a small tracking sheet with three columns, tied to implementation dates. Each quarter, list which AI-adjacent surfaces have cited your site — ChatGPT with browsing, Perplexity, Google AI Overviews, Bing Copilot, and other answer engines. Note the number of citations observed over a random sample of 20 queries in your niche.
Run the same 20-query sample before and after each implementation. The signal is noisy per query, but across 20 queries it stabilizes quickly. After three iterations, you’ll see whether your markup moves the needle for your vertical.
A second measurement worth doing: browser-based crawl comparisons. Integrating structured data for ai into your workflow produces consistent quality. Check whether your JSON-LD reaches the engine as-rendered. Half of “we implemented it” cases fail this check because the schema is injected client-side and never crawls.
A third check: brand-name ambiguity tests. Ask each engine “who is [your brand]?” and see if it names you correctly, confuses you with a similarly-named company, or fails to resolve you. When identity is well-reconciled via sameAs, this improves measurably. When it’s not, brand confusions quietly steal citations.
One last point: benchmark against yourself, not against competitors. Competitor schema is often incomplete, and chasing them means chasing noise. Measure your citation count against your own prior period, tie it to implementation dates, and don’t obsess over short-term swings.
Frequently Asked Questions About Structured Data for AI
Here is an in-depth breakdown of key considerations regarding this section:
Do I Need Different Structured Data for AI Than for Traditional SEO?
No — and the structured data for AI is where a lot of content gets confusing. There’s no separate “AI schema” specification. The same Schema.org vocabulary serves both traditional rich results and modern answer engines.
The difference is weight: AI systems favor completeness and reconciliation, while rich results favor specific property requirements. Targeted refinements to your structured data for ai streamline the entire review. Build for both by aiming for completeness, not just minimum-viable properties.
Which Schema Types Matter Most for AI Citation?
In my audits, five types consistently move the needle: Organization, Person (author), Article, Product, and FAQPage. Specialized additions like Dataset and HowTo help in specific verticals. If you can only do five types, do those five.
Is Microdata Still Viable, or Should I Always Use JSON-LD?
JSON-LD is the safer default. It’s separate from presentation, survives redesigns, and is explicitly supported across engines. Microdata and RDFa still work but bind structure to visible markup — and every redesign puts that at risk. Unless there’s a specific technical reason, choose JSON-LD.
How Long Before I See Effects from Improved Markup?
Realistically, three to six weeks for the first signals. Engines need to re-crawl, re-parse, and re-integrate the entity before citations shift. Vertical matters, too. News and commerce verticals respond faster; healthcare and finance are slower because models cross-check more aggressively before citing.
Can Too Much Markup Hurt Me?
Not the volume, but the misuse. Fake review markup, invented ratings, fabricated author credentials, and duplicate Organization blocks all cause damage. Well-structured, verifiable markup with no fabricated claims doesn’t hurt at any volume. It’s the falsehoods that trigger penalties.
Should I Mark Up Content That’s Behind a Paywall or Login?
Yes, but be aware engines may not be able to verify claims behind hard walls. For paywalled articles, use isAccessibleForFree: false with hasPart pointing at a public preview. Never mark content as free that isn’t — engines detect this and penalize accordingly.
What About AI-specific Markup Extensions — Do Any Exist?
A handful of vendor-specific extensions have appeared, but nothing has emerged as a widely adopted standard for structured data for AI. Stick to Schema.org plus extensions for your vertical. Anything outside the standard library has zero extraction benefit until the major engines recognize it, and you have no way to know when that will happen.
Where to Go from Here
Eight moves. That’s the entire surface area of what matters, and none of it requires an enormous budget. Start with validation, ship the Organization and author blocks inside a month, then expand from there.
If you’re running a structured data for AI program long-term, treat the work as continuous. Templates drift, CMS vendors push breaking changes, plugins conflict. A quarterly audit catches the regressions before they cost you citations.
The bigger picture, though, is that this entire family of practices sits inside a parent topic — machine-readable content architecture — that also covers related sub-topics like entity SEO, knowledge graph optimization, and answer engine optimization strategy. Markup is the substrate. Entity reconciliation is the strategy. Citation is the outcome.
Get the substrate clean, and the other two stack on top of the structured data for AI naturally. Skip it, and every other tactic ends up compensating for a foundation that isn’t there.
My honest advice after running dozens of these audits: don’t try to fix everything. Pick three templates, do them perfectly, and measure. Then add the next three. Structured data for AI rewards patience and consistency over big pushes.
The brands winning citations aren’t the ones who implemented all eight moves fastest — they’re the ones who implemented two moves and kept them clean while the rest of the market was shipping broken markup.
For verified reference and background research, consult the authoritative informational resource on this topic.