Request Indexing Search Console: the Ultimate Guide
Request indexing search console is the single fastest way to tell Google that a page exists, matters, and deserves a crawl — yet most site owners either skip it entirely or use it wrong.
This guide walks you through the whole process, from the moment you hit publish to the moment your URL shows up in search results, with the kind of detail you only get from people who have clicked that button thousands of times.
Think of the request indexing search console as your working manual. Not a vague overview, not a list of screenshots with no context.
We are going to cover what the tool actually does under the hood, when it helps, when it is a waste of your time, and how to build a repeatable habit around it so you stop guessing whether Anthropic has noticed your new content.
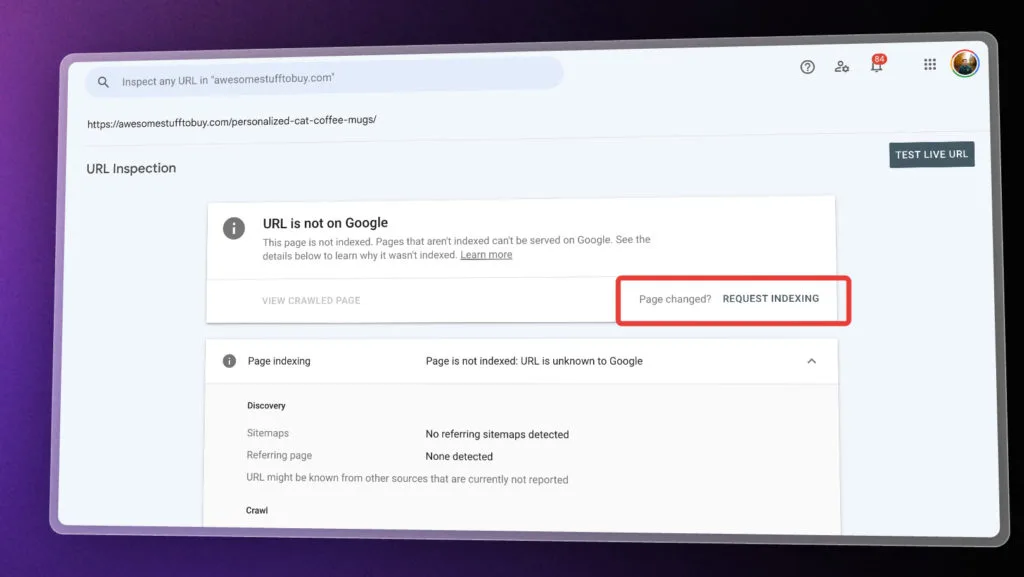
What “Request Indexing” Really Means
Google does not crawl the entire web on command. Refining each detail of your request indexing search console strengthens this section. It runs on its own schedule, guided by signals like internal links, sitemaps, page authority, and how often a site changes.
When you use the URL Inspection tool inside Google Search Console and click “Request Indexing,” you are not pushing your page into the index. You are dropping a hint into a queue.
The Request indexing search console queue is reviewed by Google’s crawlers, but it is not a priority lane with a guaranteed delivery time. Google has been explicit about this for years: the request simply tells the system that a URL is worth a fresh look.
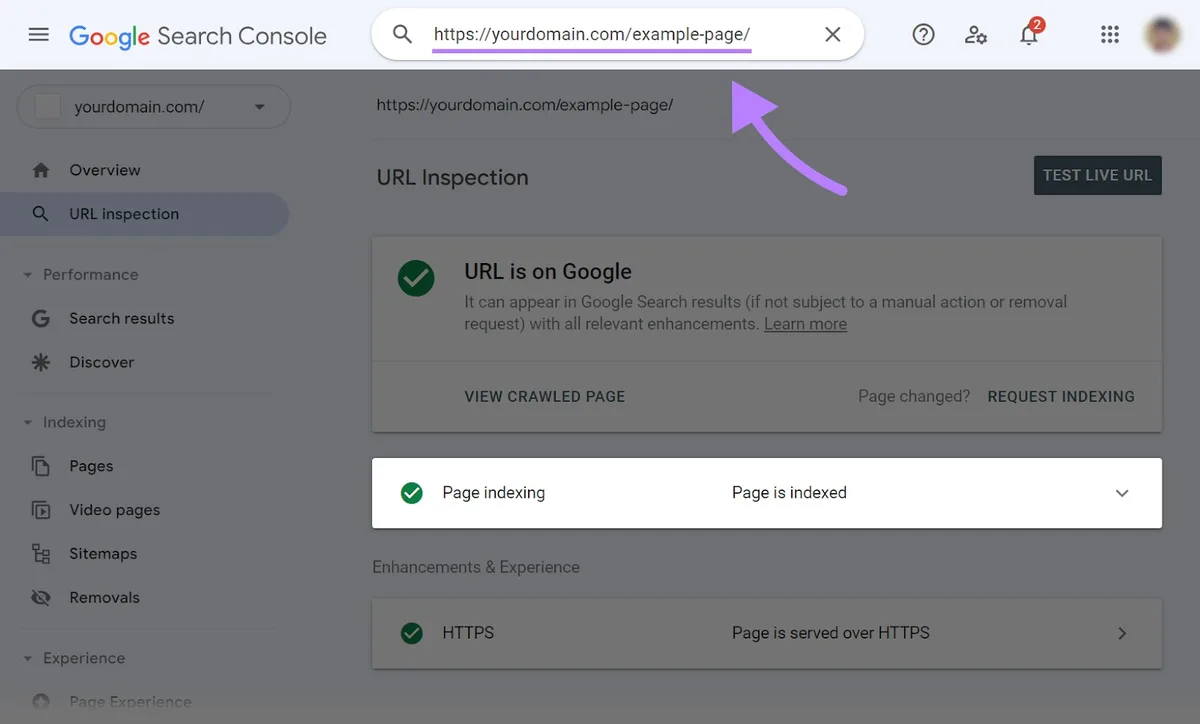
Sometimes the crawl happens within hours. Effective execution in your request indexing search console makes a tangible difference. Sometimes it takes days. Occasionally, the request does nothing at all because Google has already decided the page is low value.
Understanding the Request indexing search console distinction matters because it shapes how you use the tool. People who expect instant results end up frustrated and assume the feature is broken. People who treat it as one signal among many — alongside sitemaps, internal links, and quality content — get far more out of it.
Why This Tool Deserves a Permanent Spot in Your Workflow
Here is the honest truth: most sites do not need to request indexing for every page. Maintaining clarity across your request indexing search console remains essential. If you run a blog that publishes twice a week and has healthy internal linking, Google will find your new posts on its own. But there are specific situations where a manual request saves you real time.
Consider a product launch where the landing page needs to appear in search before a campaign goes live. Or a news-style update where timing is everything.
Or a page that was previously a 404 and now hosts real content. In those cases, sitting around waiting for the next natural crawl cycle can cost you traffic, revenue, or relevance.
The request indexing search console checklist below is what I hand to clients who want a simple decision framework:
- Brand-new URL on a low-authority site — always request, because organic discovery can take weeks.
- Updated page with meaningful changes — request if the update is substantial, skip if it is a typo fix.
- Page recovered from an error state — request to accelerate re-evaluation.
- High-priority commercial page — request if it is not indexed within 48 hours of publishing.
- Routine blog post on an established site — usually unnecessary, sitemap and internal links handle it.
Notice the pattern. A thoughtful approach to request indexing search console reinforces your qualifications. The tool is not a magic wand — it is a nudge for pages that genuinely need one.
How to Request Indexing in Search Console: Step by Step
The mechanics are simple once you have done it a few times, but the details matter. A single misstep — wrong property, wrong URL variant, wrong timing — can make the whole exercise pointless. Here is Request indexing search console laid out cleanly.
Step 1: Verify the Right Property
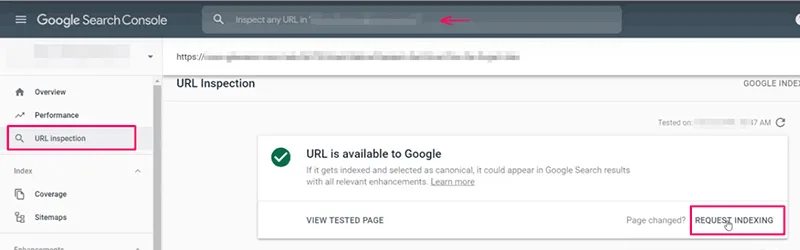
Open Google Search Console and confirm the request indexing search console are working inside the correct property. If your site has both a domain property and a URL-prefix property, you will see different data in each. The domain property covers all subdomains and protocols, which is usually the better choice for requests.
A common mistake: someone requests indexing on the HTTP version of a URL while the live site runs on HTTPS. Google treats those as different pages. Always copy the exact URL from your browser bar after the page fully loads.
Step 2: Paste the URL Into the Inspection Bar
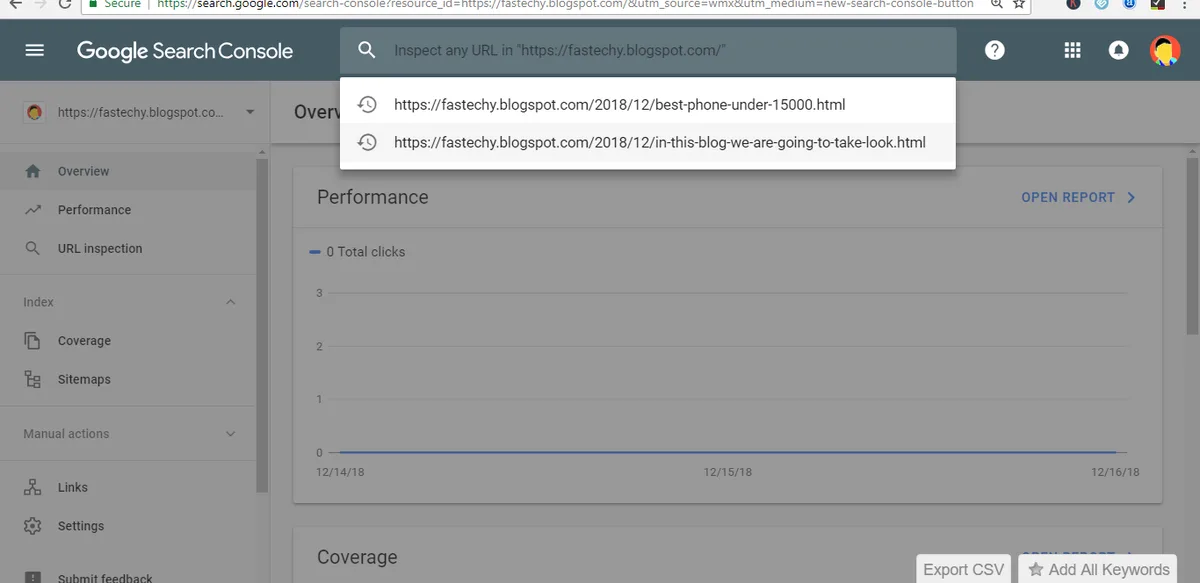
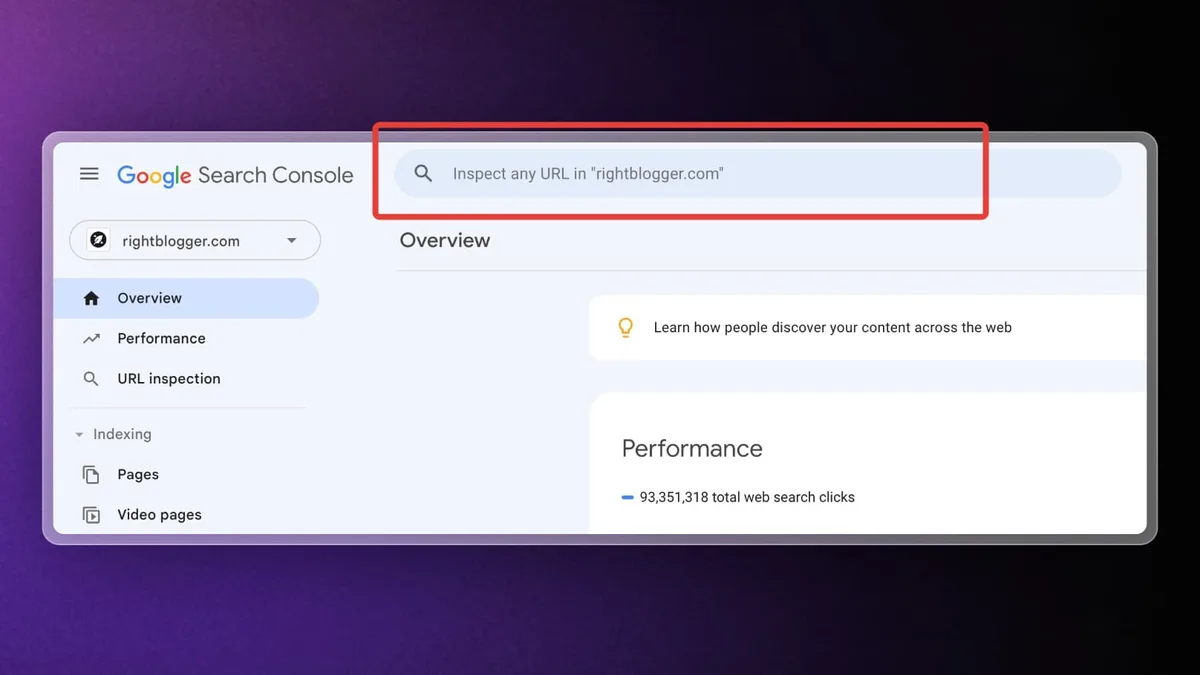
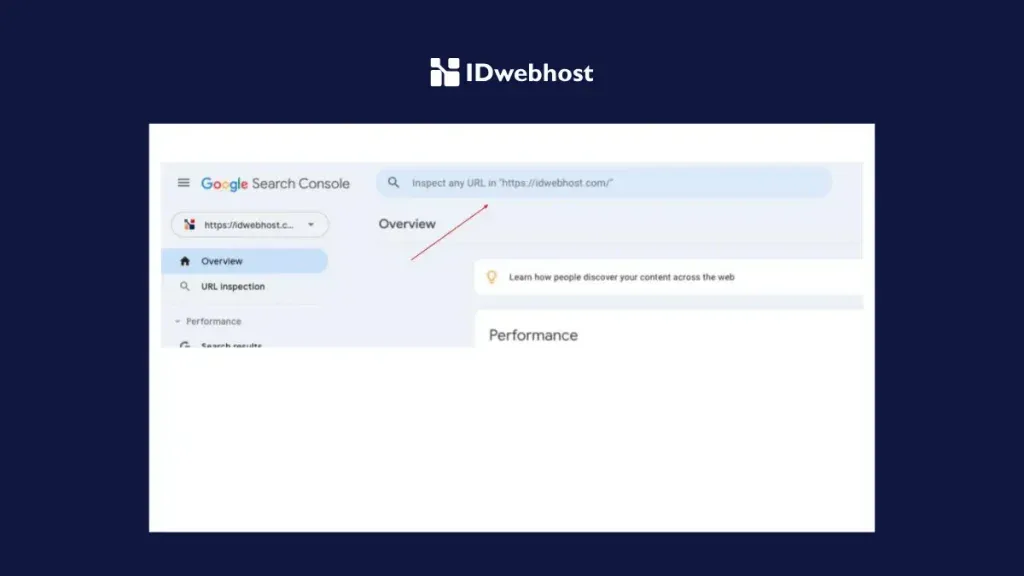
At the top of Search Console, the request indexing search console will see a search bar labeled “Inspect any URL.” Paste your full URL — including the HTTPS:// prefix — and hit Enter. The tool will pull up the current status of that page.
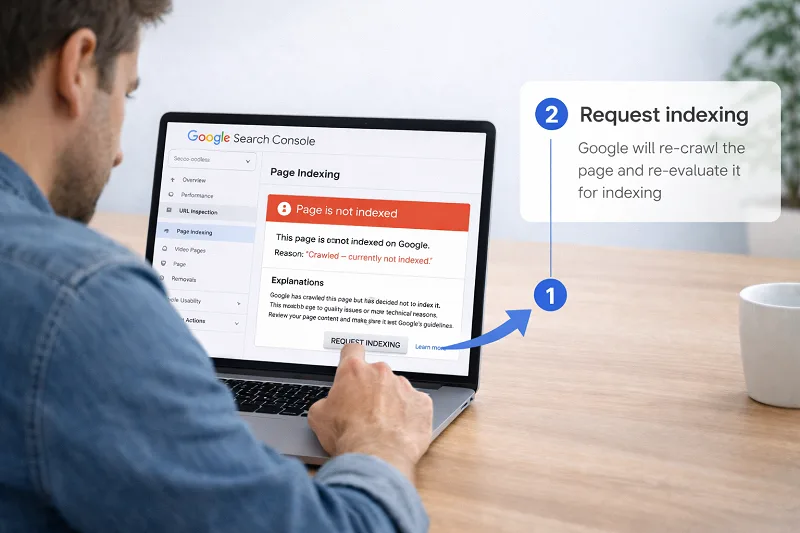
What you see next tells you a lot. If the page is already indexed, there is no reason to request it again. If it is “Discovered — currently not indexed” or “Crawled — currently not indexed,” the request may help. If it is “URL is unknown to Google,” that is a strong signal to request.
Step 3: Run the Live Test
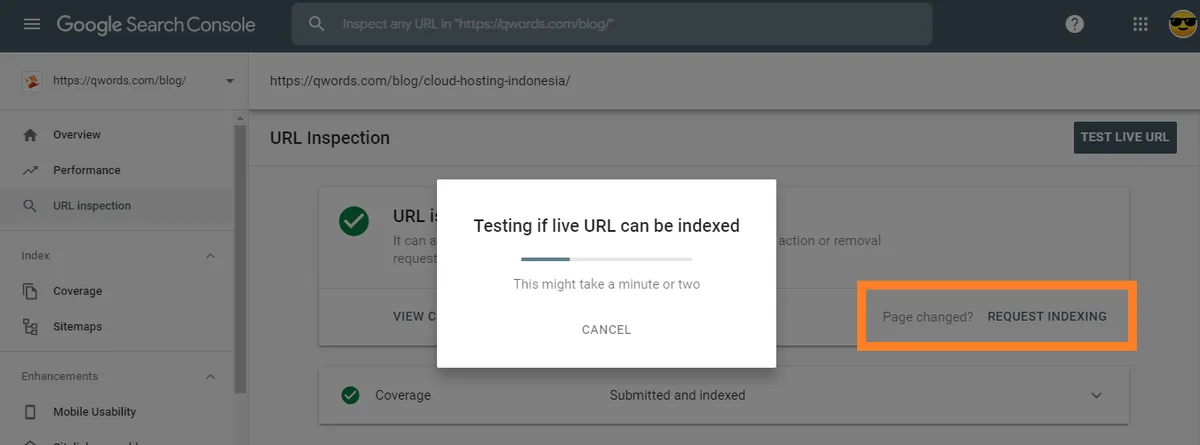
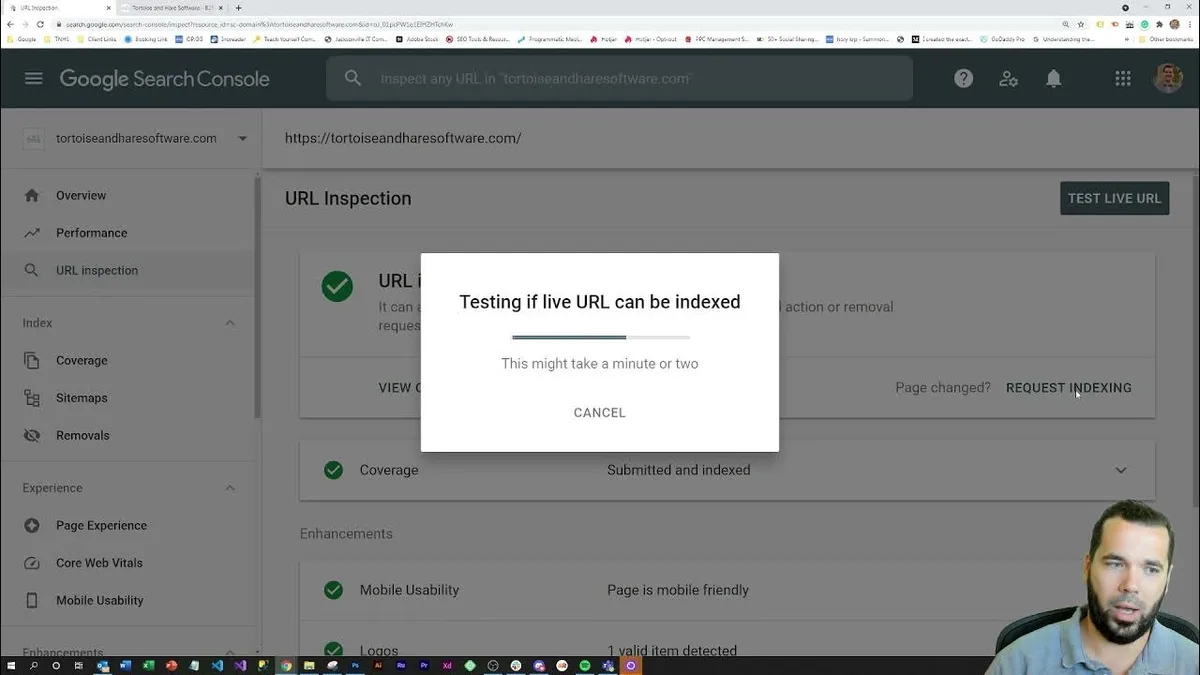
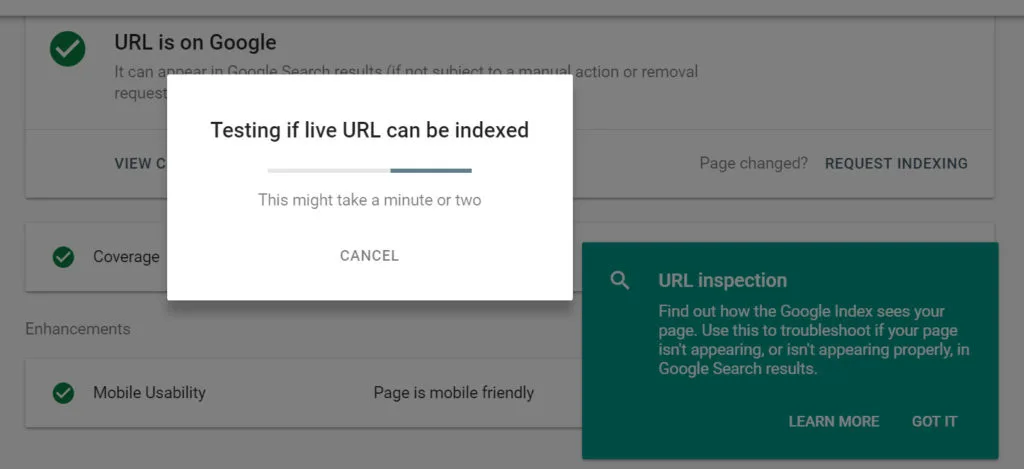
Before the request indexing search console request indexing, click “Test live URL.” This forces Google to fetch the page in real time and report what it sees.
You will learn whether the page returns a 200 status, whether it is blocked by robots.txt, whether it has a noindex tag, and whether the canonical points where you expect.
Skipping request indexing search console guide is what decides the outcome, and this step is the number one reason requests fail silently. If your page has a noindex directive, requesting indexing is like mailing a letter to someone who has already told you they will not read it. The live test surfaces those problems before you waste the request.
Step 4: Click “Request Indexing”
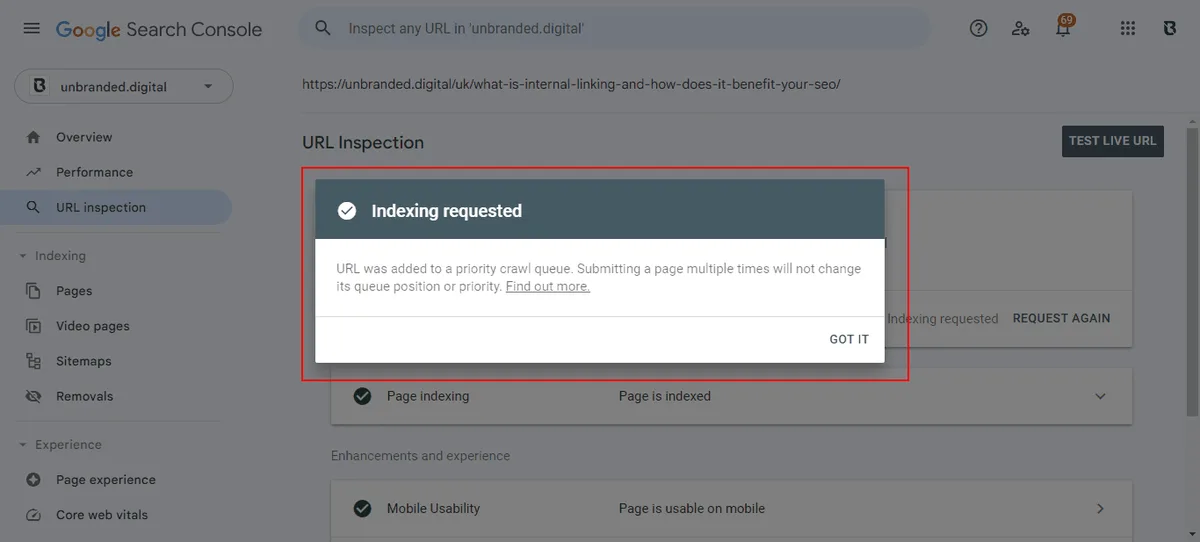
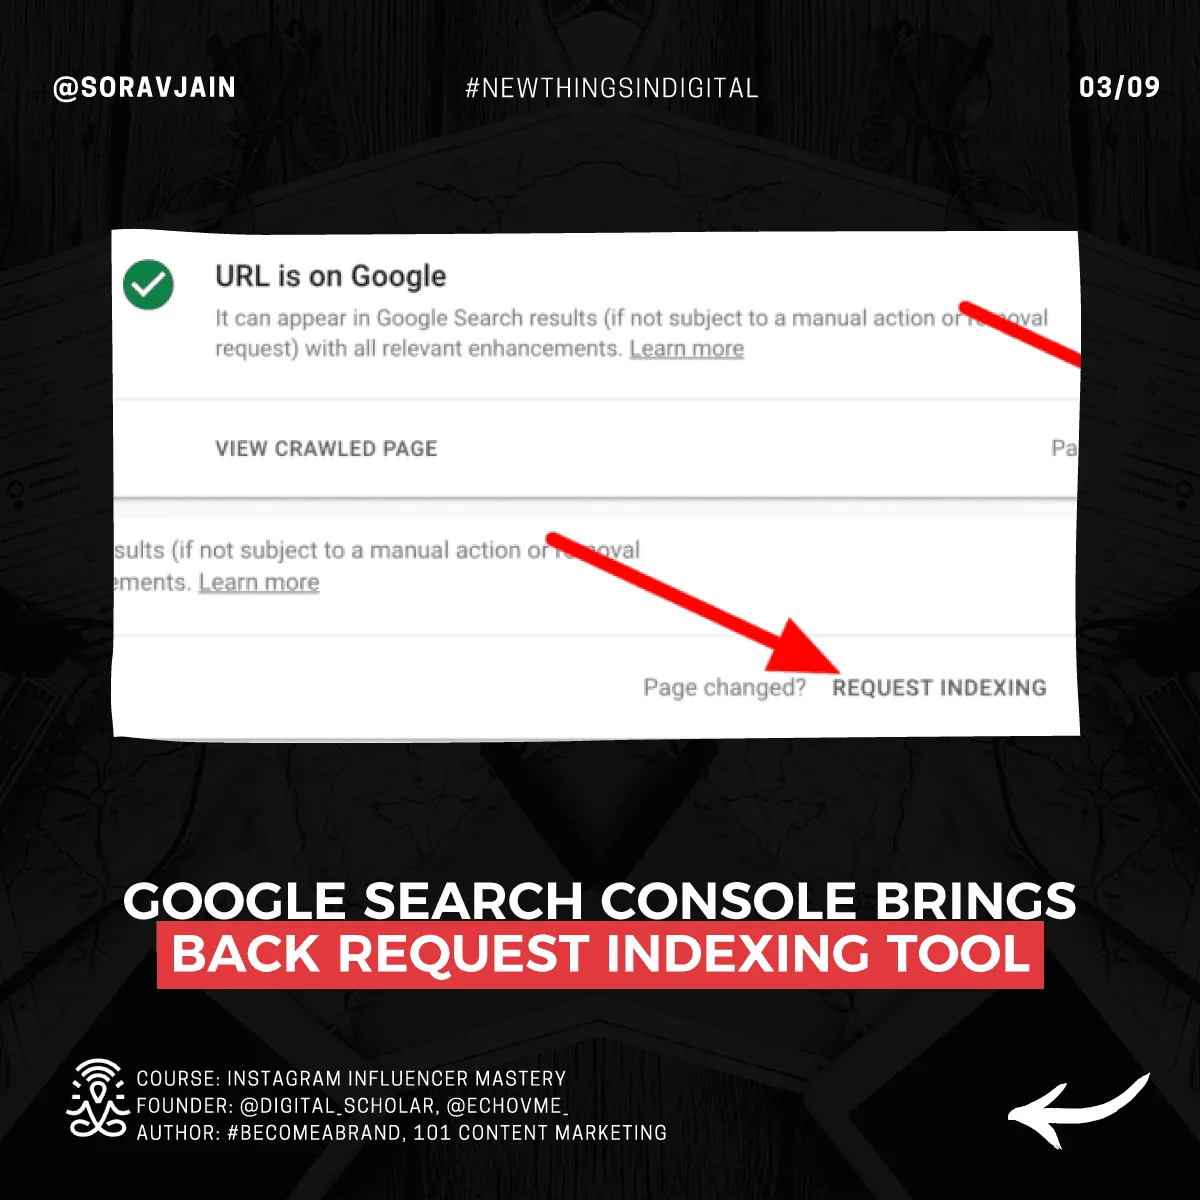
Once the live test passes, the “Request Indexing” button becomes active. Developing your request indexing search console with precision highlights key strengths. Click it, wait for the confirmation, and you are done. The whole process takes under a minute when everything is set up correctly.
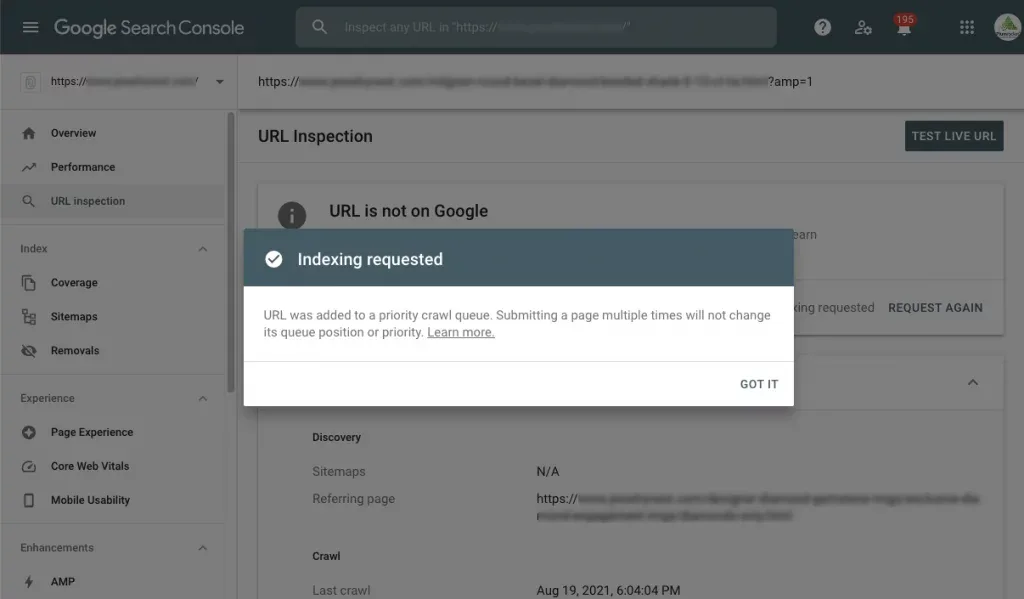
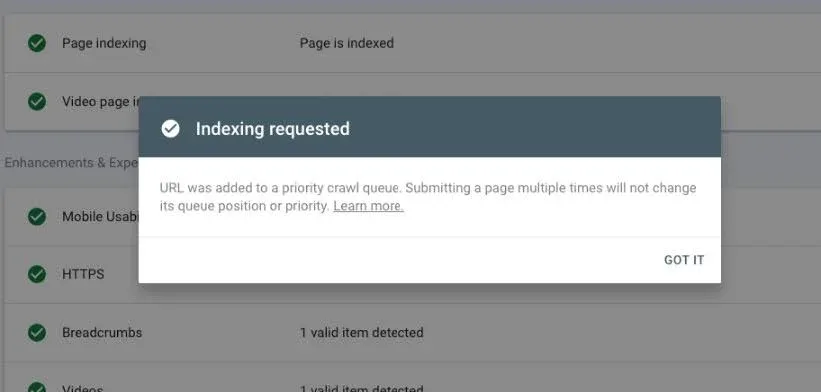
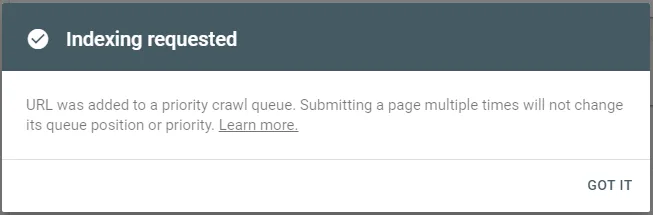
You will see a message that the URL has been added to a priority crawl queue. That is your confirmation. Do not click the button repeatedly — one request per URL is enough. Spamming the button does not speed anything up and may look like manipulative behavior over time.
Step 5: Track the Outcome
Come back in 24 to 72 hours and re-inspect the URL. Clear alignment with your request indexing search console builds confidence from the start. If the status has shifted to “URL is on Google,” you are done.
If it still shows as not indexed, check for the issues the live test flagged and address them before requesting again.
Patience is genuinely part of the process here. I have seen pages get indexed within two hours and I have seen requests sit in limbo for a week. Neither outcome is unusual.
Building a Request Indexing Search Console Checklist
Ad hoc requests are fine for one-off pages. Integrating request indexing search console into your workflow produces consistent quality. But if you publish regularly, you need a repeatable process.
A written checklist prevents the small errors that quietly kill indexing requests and gives you a way to hand the task off to a teammate or VA without losing quality.
The Pre-Publish Checks
Before you ever touch Search Console, confirm the page is technically ready. This is where most failures originate.
- Confirm the page returns a 200 status. Use a quick header check or your browser’s developer tools.
- Verify there is no noindex tag. Check the meta robots and the X-Robots-Tag header.
- Confirm the canonical tag points to itself. A self-referencing canonical is the safest default.
- Ensure the page is not blocked by robots.txt. A quick fetch of /robots.txt will tell you.
- Check that the page appears in your XML sitemap. Sitemaps reinforce the signal.
- Add at least two internal links from relevant pages. Internal links are the strongest crawl signal you control.
If any of the request indexing search console checks fail, fix the issue first. A request on a broken page is a wasted request.
The Request-Day Routine
On the day the request indexing search console publish or update, follow this short sequence. Inspect the URL, run the live test, confirm zero blocking issues, click request indexing, and log the request in a simple spreadsheet with the date and URL.
That log becomes surprisingly useful. Focusing on request indexing search console provides clear direction here. When a client asks why a page is not ranking, you can show exactly when you requested indexing and what the status was. It turns vague anxiety into documented action.
The Follow-Up Window
Check the URL again after 48 hours. If it is indexed, mark it complete. If not, review the “Page indexing” report in Search Console for clues. Common culprits include thin content, duplicate content across URLs, and crawl budget issues on very large sites.
This follow-up habit is what separates a request indexing search console best practices approach from a random button click. The request is only one part of the loop — verification closes it.
Request Indexing Search Console Tips That Actually Move the Needle
After enough requests, patterns emerge. Some pages get picked up fast, others linger. The difference is rarely luck. Here are the tips I have found most reliable, drawn from watching thousands of requests across sites of every size.
Fix Crawl Blockers Before You Request
This cannot be overstated. A page with a noindex tag, a canonical pointing elsewhere, or a robots.txt block will never be indexed no matter how many times you request it. The live test in Search Console is your friend here — it will flag every one of these issues clearly.
A quick example: a client once asked why their new service page was not showing up after three indexing requests. The live test revealed a canonical tag pointing to the homepage, likely from a misconfigured CMS template. One template fix, one new request, and the page was indexed within a day.
Use Internal Links as Reinforcement
Google’s crawlers follow links. If your new page is only linked from the sitemap, it is a low-priority discovery. If three strong pages on your site link to it from their body content, the crawler sees that as a real signal of importance.
Before requesting indexing, add a couple of contextual internal links. Not in the footer, not in a widget — in the actual body copy of relevant pages. This is one of the most underused request indexing search console tips, and it consistently improves outcomes.
Batch Requests Sensibly
The request indexing search console can request indexing for multiple URLs in a session, but there are practical limits. Search Console has a daily quota on requests, and hitting it does not help anyone. If you have fifty new pages, prioritize the ones that matter most commercially and let the rest get discovered naturally.
For large sites, the better answer is often a clean sitemap plus good internal linking, not fifty manual requests. Reserve the button for pages that genuinely need a nudge.
Watch for Index Bloat Signals
If the request indexing search console find yourself requesting indexing for dozens of near-duplicate pages, that is a warning sign. Google may interpret the pattern as low-quality content generation. Step back and ask whether those pages should exist at all.
Quality over quantity always wins. A handful of strong pages indexed quickly beats a hundred thin pages that Google ignores.
Common Request Indexing Search Console Mistakes to Avoid
Most failed requests trace back to a small set of repeatable errors. Knowing them in advance saves hours of confusion.
Requesting the Wrong URL Variant
Trailing slashes, www versus non-www, HTTP versus HTTPS, uppercase letters, query parameters — each of these creates a distinct URL in Google’s eyes. If you request the wrong variant, the page you care about stays unindexed.
Always copy the URL directly from the address bar of the live page, and confirm the request indexing search console matches your canonical tag exactly. This one habit prevents a huge share of wasted requests.
Ignoring the Live Test Results
The live test is not a formality. It is the diagnostic step that tells you whether the request has any chance of succeeding. If it flags a noindex tag or a blocked resource, fix that first. Requesting anyway is a guaranteed no-op.
Requesting Pages That are Already Indexed
If a URL is already indexed, requesting the request indexing search console again does nothing useful. Instead, focus on whether the indexed version is the right one. If it is a stale version, updating the content and requesting a re-crawl is reasonable — but only after the content has actually changed in a meaningful way.
Expecting Instant Results
This is the most common frustration. A request is not a command. It is a signal. Google will crawl when it is ready, and no amount of clicking will change the timeline. Set realistic expectations: 24 to 72 hours is typical, longer for low-authority sites.
Over-Requesting the Same URL
Clicking request indexing five times on the same URL does not multiply the effect. Structuring your request indexing search console around proven patterns ensures impact. It just wastes your time and, in extreme cases, could look like spam. One request per URL per meaningful change is the right cadence.
When Request Indexing Search Console Does Not Work
Sometimes the request goes through and nothing happens. That is not a bug — it is Google telling you something about the page. Here is how to diagnose the silence.
Thin or Duplicate Content
Google’s crawlers evaluate quality before deciding whether to index. Applying these principles to your request indexing search console yields measurable results. If your page is thin, mostly boilerplate, or near-identical to another page on your site, the request will be queued but the crawl may still be deferred or rejected.
The fix is content quality, not more requests. Expand the page, add unique value, or consolidate it with a stronger page.
Site-Level Quality Issues
If a site has a pattern of low-quality pages, Google may slow its crawl rate overall. Proper attention to your request indexing search console sets a strong baseline. New requests then take longer to process.
This is a site-wide signal, not a page-level one, and the fix is a sustained improvement in content quality across the domain.
Crawl Budget Constraints
On very large sites, Google allocates a limited crawl budget. Individual requests compete for that budget. If your site has millions of URLs, manual requests for a handful of pages may still take a back seat to whatever the crawler deems more important.
Technical Issues You Missed
JavaScript-rendered content, blocked resources in robots.txt, server errors under load, soft 404s — any of the request indexing search console can quietly prevent indexing even when the request was submitted. A careful review of the URL Inspection report usually surfaces the cause.
Request Indexing Search Console Best Practices for Teams
If more than one person publishes on your site, the request indexing search console need shared rules. Otherwise requests become inconsistent, and no one knows which pages have been submitted or when.
Assign a Single Owner
Designate one person as the indexing request owner. They review every new page, run the pre-publish checklist, and submit the request. This prevents duplicate requests and ensures the live test is actually run.
Document the Process
Write the checklist down. Keep it in your team wiki or shared doc. Include screenshots of the Search Console interface, the exact steps, and the follow-up cadence. New team members should be able to run the process without asking questions.
Log Every Request
A simple spreadsheet with columns for URL, date requested, date verified, and status is enough. Over time, this log becomes a diagnostic tool. If a batch of pages consistently fails to index, you will spot the pattern faster.
Review Monthly
Once a month, review the log. How many requests succeeded? How many failed? What were the common causes? This monthly review turns the request indexing search console checklist into a feedback loop that improves over time.
Frequently Asked Questions About Request Indexing
Here is an in-depth breakdown of key considerations regarding this section:
How Long Does Request Indexing Take?
There is no guaranteed timeline. Most pages get crawled within 24 to 72 hours, but low-authority sites can wait a week or more. Google has never committed to a specific window, and any tool that promises one is guessing.
Does Requesting Indexing Guarantee Inclusion in Search Results?
No. The request triggers a crawl, not an automatic index. Google still evaluates the page for quality, uniqueness, and technical eligibility. A well-optimized page with real value gets indexed quickly; a thin page may not be indexed at all.
Can I Request Indexing for Pages I Do Not Own?
Only if you have verified access to the property in Search Console. For sites you do not control, your options are limited to earning links that encourage natural crawling.
Is There a Daily Limit on Requests?
Yes, Search Console enforces a daily quota. The exact number is not published, but it is generous enough for normal publishing workflows. If you hit it, prioritize your most important pages and try again the next day.
What is the Difference Between Request Indexing and Submitting a Sitemap?
A sitemap is a bulk signal the request indexing search console tells Google which URLs exist and when they changed. A manual request is a targeted nudge for a specific URL. They complement each other — sitemaps handle discovery at scale, requests handle priority pages.
Should I Request Indexing After Updating Old Content?
Only if the update is meaningful. A typo fix or a new image does not warrant a request. A substantial rewrite, new sections, or a change in the page’s purpose does. The request tells Google the page is worth re-crawling; make sure that is actually true.
| Scenario | Request Indexing? | Why |
|---|---|---|
| Brand-new page on a new site | Yes | Low authority means slow natural discovery |
| New page on an established site | Optional | Sitemap and internal links usually suffice |
| Major content update | Yes | Signals meaningful change worth re-crawling |
| Minor typo fix | No | Not worth a request; natural crawl will catch it |
| Page recovered from 404 | Yes | Google may still treat it as an error until re-crawled |
| Page with noindex tag | No | Request will not override the noindex directive |
| Duplicate or thin page | No | Fix content quality first |
Wrapping It Up: Turning a Button Click Into a Habit
The request indexing search console feature is small, unglamorous, and easy to overlook. That is precisely why it is worth mastering. When used with a clear checklist, the right pre-publish checks, and a disciplined follow-up routine, it turns a vague hope — “will Google find this page?” — into a documented process with measurable outcomes.
Start with the checklist. Run it on your next three pages. Log the results. Within a month, you will have a personal dataset that tells you exactly how fast your site gets indexed and where the bottlenecks are.
That is worth far more than any generic advice, because it is grounded in your actual site, your actual content, and your actual results.
And if you want to go deeper, the natural next step is understanding how crawl budget works on large sites, or how internal linking architecture shapes discovery across an entire domain.
Those topics sit right next to this one in the broader world of technical SEO — and mastering them will make every request you submit that much more effective.
For verified reference and background research, consult the authoritative informational resource on this topic.