Why Duplicate Content Fix Matters More Than Most Site Owners Realize
A duplicate content fix is not glamorous work, but it quietly decides whether your pages ever reach the audience they were written for. Google does not hand out a penalty for every repeated paragraph, yet it does something far more damaging: it picks one version to rank and ignores the rest.
The Duplicate content fix silent selection process costs real traffic. Two URLs with the same product copy fight each other, Google splits whatever signals they earn, and both end up in position eleven while a competitor takes the click.
I have watched the duplicate content fix happen on ecommerce stores with 4,000 SKUs, on news sites that syndicate partner articles, and on small blogs where pagination accidentally created 60 near-identical archives. The pattern is always the same. Nobody set out to create duplication.
It crept in through filters, trailing slashes, UTM tags, printer-friendly versions, and lazy CMS defaults. Fixing it is mechanical once you know where to look, which is exactly what this duplicate content fix guide is designed to map out.
Below the Duplicate content fix will find seven proven fixes. Each one is a working method I have applied or seen applied on live sites, with the reasoning behind it and the execution detail that actually matters.
Before the methods, though, the Duplicate content fix need to understand what you are dealing with. Misdiagnosis is the reason so many cleanup projects burn budget and change nothing.
What Counts as Duplicate Content, and What Google Actually Does About It
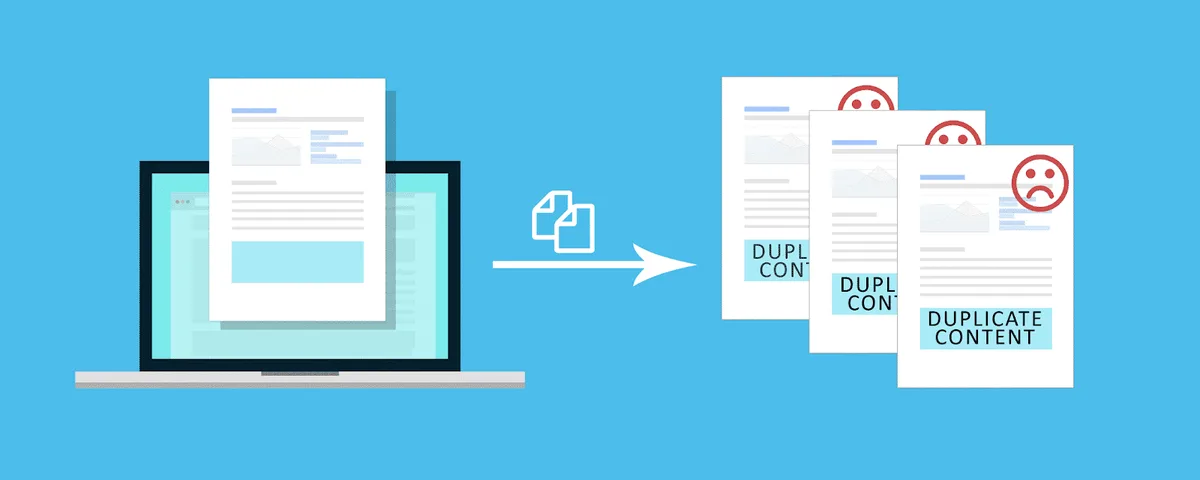
Google defines duplicate content loosely: substantial blocks of content the duplicate content fix appear in more than one place on the web, or in more than one place on the same site. It is not limited to word-for-word copies.
Rewriting three sentences in a spun article does not make the Duplicate content fix unique, and neither does swapping synonyms. The search engine compares meaning and structure, not just strings of characters.
Here is the part people get wrong. A thoughtful approach to Duplicate content fix reinforces your qualifications. There is no duplicate content penalty in the classic sense. Google’s own documentation states that duplicate content is handled algorithmically through consolidation, not manual punishment.
The practical damage still stings. Effective execution in your duplicate content fix makes a tangible difference. Crawl budget gets wasted on redundant URLs. Link equity is diluted across near-identical pages. Analytics reports become unreliable because traffic lands on whichever version Google picked.
Worse, when syndicated copies appear on higher-authority domains, the original publisher sometimes gets outranked for its own work. Focusing on Duplicate content fix provides clear direction here. That is not a penalty, but it may as well be one.
The Duplicate content fix can inspect the official guidance on consolidating duplicate URLs and see the language yourself. Read it carefully and you will notice how much discretion Google keeps for itself.
Internal versus External Duplication: Two Different Problems
Duplicate content comes in two flavors, and the duplicate content fix need different treatments. Internal duplication happens within your own domain: parameter URLs, www versus non-www, HTTP versus HTTPS, paginated archives, and accessibility-style print pages.
You control all of that. A duplicate content fix for internal cases is about consolidation and clear signals, and it is entirely within your power.
External duplication is other people’s doing. Focusing on duplicate content fix provides clear direction here. Scrapers, affiliate feeds, syndication partners, and content aggregators republish your material with or without permission.
The Duplicate content fix cannot always eliminate external copies. What you can do is establish the canonical version so clearly that Google knows whose page is the source.
Syndication partners should be asked to add a canonical tag pointing back to the duplicate content fix. Most legitimate partners agree, because they are not trying to compete with you. Scrapers are a different conversation, and often the correct response is a DMCA notice rather than an SEO tactic.
How to Diagnose Duplication on a Site of Any Size
Start with a full crawl using a tool like Screaming Frog or Sitebulb, then sort by page title and by H1. Identical titles across multiple URLs are the fastest way to spot the problem at scale.
Next, export the crawl and compare content hashes where your tool supports it. Ahrefs and Semrush both flag near-duplicate pages, and Google Search Console’s Pages report will show you which URLs it considers alternate versions of another page.
Look specifically for these patterns: uppercase and lowercase variants, trailing slash inconsistencies, index.php or default.asp appended to homepages, faceted navigation parameters, session IDs, and paginated series where page two is treated as a copy of page one.
If you run a small site, a manual search will do. Type a distinctive sentence from your page in quotation marks and see how many results come back. Do this for your five most valuable pages first, because that is where the money is.
Document everything in a spreadsheet before you touch a single tag. The most common failure mode in any duplicate content fix is making changes faster than you can record them.
The Seven Proven Fixes, Ranked by Effort versus Impact
Not every fix deserves the same priority. Some take fifteen minutes and recover thousands of sessions. Others are week-long engineering projects with marginal returns.
The order below reflects what I would do on a typical site, starting with the highest impact per hour of work. Structuring your duplicate content fix around proven patterns ensures impact. Your situation may shift the sequence, but the logic holds.
1. Canonical Tags: the Signal That Does the Heavy Lifting
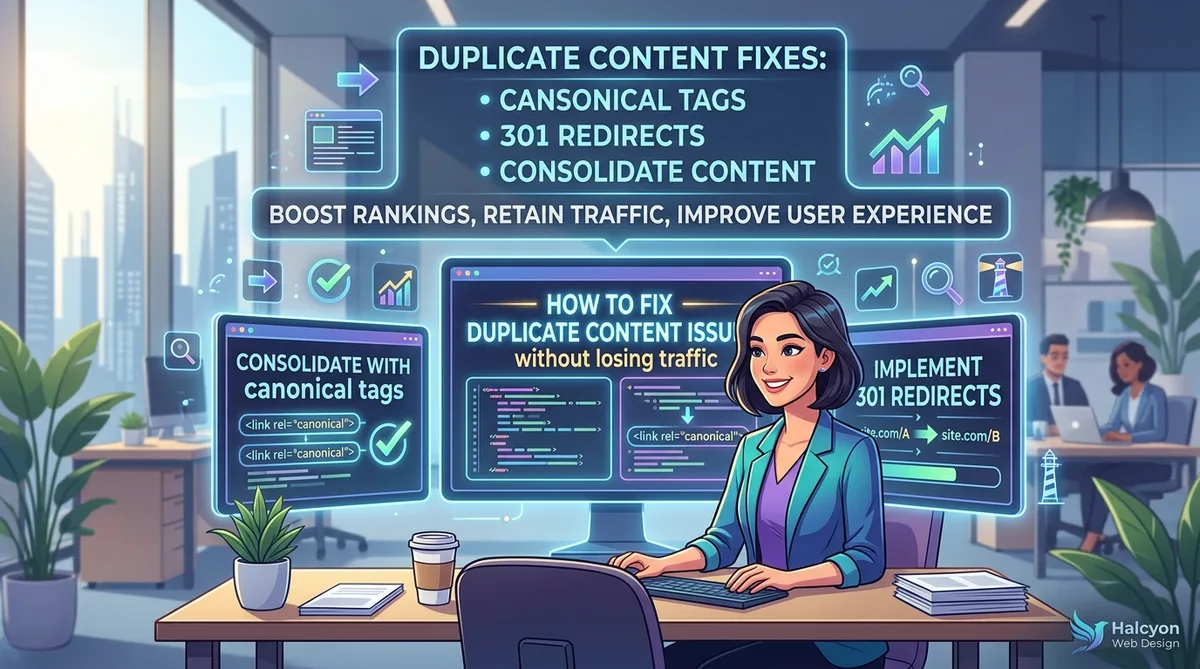
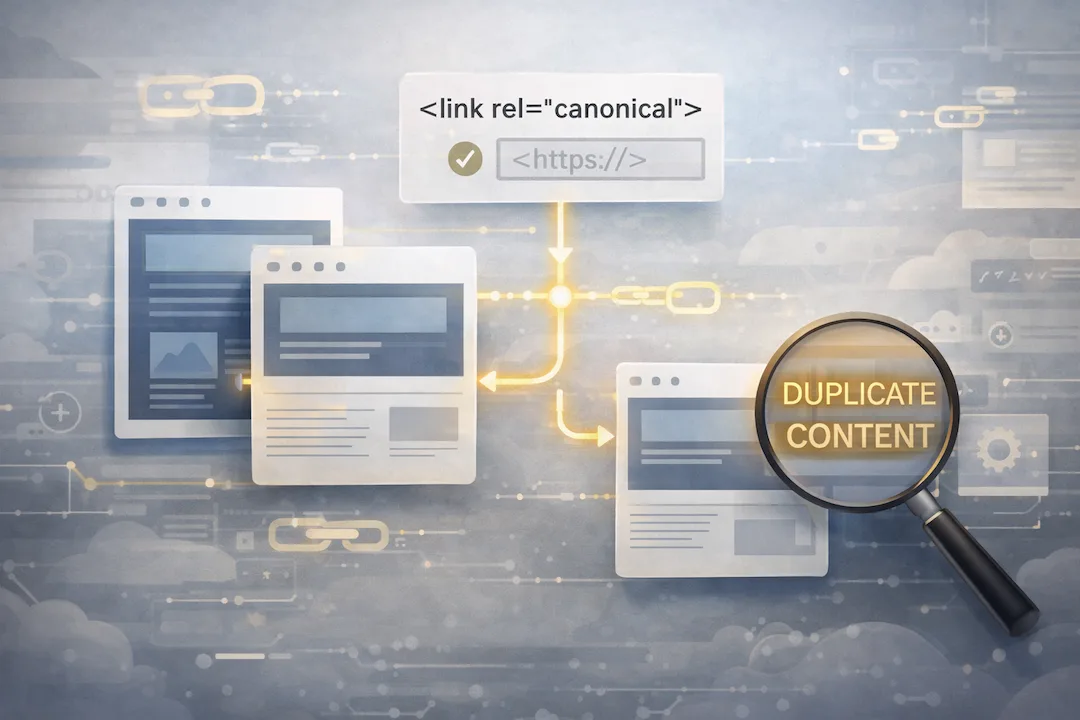
The rel=”canonical” tag tells Google which URL is the authoritative version when multiple URLs serve essentially the same content. It is the single most useful tool in any duplicate content fix, and it is also the most commonly misapplied.
Place the tag in the head of every alternate version, pointing to the one you want indexed. Make sure the canonical URL returns a 200 status, is not blocked by robots.txt, and is not itself a redirect target.
Self-referencing canonicals are not optional. Every indexable page should declare itself as canonical, even if no duplication exists, because it prevents future mistakes from compounding.
A common trap: ecommerce platforms generate canonicals pointing to a filtered version of a category page. Applying these principles to your duplicate content fix yields measurable results. Google then ignores the whole cluster. Audit your canonicals quarterly rather than trusting the platform default.
Another trap is using a canonical tag and a noindex tag on the same page. Those two instructions contradict each other, and Google tends to follow the noindex, which removes the page entirely.
For a duplicate content fix checklist item you can hand to a developer, write it like this: every URL in the duplicate set must carry a canonical pointing to the chosen primary, and the primary must carry a self-referencing canonical.
2. 301 Redirects for Content That Should Not Exist
When a page has no independent value, a canonical tag is a half measure. The cleaner answer is a permanent redirect that removes the duplicate from existence altogether.
This applies to HTTP versions of HTTPS pages, www versions of non-www domains, old permalink structures after a slug change, and duplicate product pages created by a CMS migration.
Redirects pass nearly all link equity and eliminate the duplicate in one move, which is why they outperform canonicals in cases where the old URL will never serve a purpose again.
Do not redirect in chains. A URL that redirects to another that redirects again loses equity with every hop, and Google’s crawler may abandon the chain entirely. Flatten the path so every redirect lands on the final destination in a single step.
Also avoid redirecting everything to the homepage. Proper attention to your duplicate content fix sets a strong baseline. That is a soft 404 in disguise, and it teaches Google nothing about which content replaced which.
On a client’s site that had accumulated eleven years of URL changes, flattening the redirect chains alone recovered roughly 18 percent of previously lost organic sessions within two months. That was the whole fix. No new content, no link building.
3. Parameter Handling and Faceted Navigation Cleanup
Ecommerce and directory sites generate duplicate URLs through filtering, sorting, and tracking parameters without anyone intending it. A single category can spawn hundreds of crawlable variants.
Sort parameters, session identifiers, and tracking tags should not create indexable URLs. Developing your duplicate content fix with precision highlights key strengths. Handle them at the server level with canonical tags pointing to the clean category, or block them in robots.txt if they never need to be crawled at all.
Be careful with robots.txt. Blocked URLs can still be indexed if external links point to them, and Google cannot read a canonical tag on a page it is forbidden to crawl. For parameter variants that must exist but should not rank, a canonical plus a noindex where appropriate is safer than a block.
Faceted navigation deserves its own audit. Attributes like color, size, and price range are useful to shoppers but devastating to crawl budget when every combination gets its own URL.
Pick the facets the duplicate content fix reflect genuine search demand, such as a specific size plus a specific material, and let the rest be canonicalized or handled with JavaScript. This is the pattern that separates well-built stores from ones that drown in their own index.
A Duplicate Content Fix Checklist You Can Run This Week
A duplicate content fix checklist saves you from the most expensive mistake in this work, which is fixing things twice because you lost track of what changed.
| Step | Action | Who Owns It | Verification |
|---|---|---|---|
| 1 | Crawl the site and export all indexable URLs | SEO lead | Crawl covers at least 95 percent of known pages |
| 2 | Group URLs by identical title and H1 | SEO analyst | Every group has a documented decision |
| 3 | Check protocol, www, and trailing slash consistency | Developer | One version returns 200, others 301 |
| 4 | Audit canonical tags on every group | Developer | All point to a 200, self-referencing primary |
| 5 | Review parameter and facet URLs | Developer plus SEO | No indexable variants outside the approved set |
| 6 | Inspect pagination handling | SEO lead | Self-canonical on every page of the series |
| 7 | Confirm in Search Console after recrawl | SEO analyst | Duplicate clusters shrink within four to six weeks |
Print it, assign owners, and date each row. That tiny bit of discipline is what turns a duplicate content fix tips article into an actual project with an endpoint.
Tick every row before declaring victory. Half-finished consolidation often makes reporting worse than it was before you began.
4. Pagination and Archive Pages: Handling Series Correctly
Pagination is where even experienced teams slip. Each page in a series should carry a self-referencing canonical, not a canonical pointing to page one.
Why? Integrating duplicate content fix into your workflow produces consistent quality. Because page two of a product listing contains different items than page one. Declaring it a duplicate of page one tells Google to drop page two, and the products on that page lose their only path to discovery.
Google now recommends self-canonicals for paginated series, and the duplicate content fix also dropped the old rel=”next” and rel=”prev” hints from its supported signals. Keep them if you like, but do not rely on them.
The same reasoning applies to date archives and tag pages. If a tag page lists the same posts as a category page, you have a duplicate. Either consolidate the tag into the category or add distinct value to the tag page.
One publisher I worked with had 340 tag archives, of which 290 duplicated categories. Targeted refinements to your duplicate content fix streamline the entire review. Removing the redundant ones shrank the index by 12 percent and let the crawler spend its budget on the articles that actually earned traffic.
This is a classic duplicate content fix best practices case: ask not “how do I rank this page” but “does this page deserve to exist at all.”
5. Content Consolidation for Genuinely Overlapping Pages
Sometimes two pages deserve to exist, and sometimes they should become one. That decision is the hardest part of this work, and it needs a human eye.
Two blog posts on nearly the same query compete with each other. Neither accumulates enough authority to rank. Merge them into a single stronger page, redirect the weaker one, and keep the best sections from both.
Ask three questions. Do both pages target the same search intent? Does each have unique information the other lacks? Would a reader benefit from finding everything in one place?
If the answer to the second is yes and the first is no, keep both and differentiate them clearly. If the first is yes, merge. If both are no, delete and redirect.
The merge itself is craft work. Do not simply concatenate the two pages. Rebuild the outline around the strongest angle, absorb the unique sections, and rewrite the transitions so the article reads as one piece.
On a SaaS support site, three separate troubleshooting articles covered the same login failure. Refining each detail of your duplicate content fix strengthens this section. Consolidating them into one page with clear sections took two afternoons and moved that page from position fourteen to position four in about nine weeks.
That result is not guaranteed, but the logic behind it is sound. Google generally prefers one strong page over three mediocre ones.
6. Absolute URLs and Consistent Internal Linking
Inconsistency in your internal links quietly manufactures duplicates. Linking to /products/shoes on one page and /products/shoes/ with a trailing slash on another creates two crawlable paths to the same content.
Pick one URL structure and enforce the duplicate content fix everywhere. That means navigation menus, breadcrumbs, sitemap entries, structured data, and every in-body link.
Relative versus absolute URLs does not matter much for duplication. Consistency does. A relative link resolves to the same absolute URL every time, which is fine, as long as the base is unambiguous.
Run a link audit after any CMS migration. Migrations are the single largest source of accidental duplicate content, because old URLs stay alive while new ones go live.
The duplicate content fix tips here are unglamorous but effective: set a canonical pattern in your CMS template, enforce it with a pre-publish check, and stop relying on manual cleanup.
Sitemaps are your declaration of which URLs matter. Maintaining clarity across your duplicate content fix remains essential. If a URL appears in an XML sitemap, it should be the version you want indexed. Include only canonicals and only 200-status pages.
7. Rendering, JavaScript, and Mobile Variants
Modern JavaScript frameworks create a duplication problem the duplicate content fix older checklists miss. Server-rendered HTML and client-rendered content can differ, and Google may index either version.
If your framework serves an empty shell to crawlers and fills it in with JavaScript, make sure the rendered result matches the canonical you declare. Otherwise you may be canonicalizing to a page Google never sees.
Test with the URL Inspection tool in Search Console. Compare the rendered HTML against your source. If key content appears only after JavaScript execution, verify that Google executes it and indexes the result.
Separate mobile URLs, once the standard m-dot pattern, introduced their own duplication. If you still run a separate mobile domain, make sure the mobile version points its canonical to the desktop URL and the desktop version points back to itself.
Most sites have moved to responsive design, which eliminates the issue entirely. If you can, do that.
AMP versions followed a similar arc. Google dropped the AMP requirement for its main results, and many publishers retired their AMP pages entirely. If you still maintain AMP, check the canonicals carefully, because those pages were notorious for pointing at the wrong URL.
One more rendering case: print stylesheets and “printer-friendly” URLs. These should redirect to or canonicalize to the main article. If they are indexable, fix that today.
Real-World Cases: Three Sites, Three Different Fixes
Abstract advice is easy to nod along to. Real cases show where the theory bends.
Case one: a regional news site syndicated articles to four partner publishers. Their aggregate traffic dropped 23 percent over two quarters because the partner copies were winning. The duplicate content fix was straightforward once the contracts were renegotiated, and each partner added a canonical pointing to the original. Traffic recovered in about eleven weeks.
Case two: a home goods retailer with 9,000 products and an open faceted navigation. Every filter combination was crawlable, and Google had indexed 340,000 URLs for a catalog of 9,000. Canonicalizing the non-priority facets and blocking the rest cut the index by 82 percent and raised organic revenue per session by roughly 19 percent.
Case three: a solo blogger whose paginated archives had accidentally created 112 pages Google treated as near-duplicates. The fix was a twenty-minute template change, adding self-canonicals to pagination. Nothing else changed, and impressions on the top ten posts climbed within a month.
Three different problems, three different fixes, one shared lesson. The duplicate content fix has to match the specific mechanism that created the duplication in the first place.
When Duplication Comes from Scrapers, Not Your CMS
Scraped copies are the most frustrating version of the problem because the duplicate content fix did not create them. A scraper takes your article, strips the attribution, and publishes it as its own.
Speed matters. Google usually credits the first-indexed version, so publishing on time and submitting your sitemap promptly gives you a head start. Indexing speed is your most reliable defense.
If a scraper outranks you anyway, file a DMCA takedown with the host and with Google. For aggregators that are technically operating legally, a polite message from a real domain often works better than a threat.
Long term, the defense against scrapers is the same as the defense against every other form of duplication: be unmistakably the primary source. Original research, first-hand experience, personal photographs, and data nobody else has do not scrape well.
A scraper can copy your text. It cannot copy your interviews, your original photography, or your proprietary dataset. That is the durable moat.
Common Mistakes That Sabotage a Duplicate Content Fix
The failure modes in the duplicate content fix work are predictable, which means they are avoidable. Here are the ones I see most often.
Mistake one: applying noindex to duplicates instead of canonicals. Noindex removes the page from the index but does not consolidate signals to the primary version. You lose the equity instead of transferring it.
Mistake two: canonicalizing to a page the duplicate content fix is itself noindexed or blocked. The chain breaks and Google ignores your instruction entirely.
Mistake three: redirect chains and loops. A redirect that points to a URL that redirects again is nearly useless, and a loop is worse than no redirect at all.
Mistake four: over-canonicalizing distinct pages. If two pages genuinely serve different audiences, forcing one to defer to the other means one of those audiences loses its entry point.
Mistake five: treating duplication as a one-time cleanup. New URLs appear every time someone publishes, migrates, or introduces a campaign with tracking parameters. This needs a recurring process, not a project with an end date.
The teams that win here are the ones that build duplication checks into their publishing workflow, not the ones that run a heroic cleanup once and forget about it.
Frequently Asked Questions About Duplicate Content Fixes
Here is an in-depth breakdown of key considerations regarding Frequently Asked Questions About Duplicate Content Fixes:
Is Duplicate Content Actually Penalized by Google?
No, not in the traditional sense of a manual action. Google consolidates duplicate URLs algorithmically, choosing one version to rank and suppressing the others. The damage comes from diluted signals and wasted crawl budget rather than a formal penalty.
That said, the duplicate content fix is often indistinguishable from a penalty from the site owner’s perspective. Traffic disappears from the pages you spent weeks writing, and no message appears in Search Console explaining why.
Deliberately manipulative duplication, such as spinning content across dozens of doorway pages, can trigger manual action. Accidental duplication almost never does.
Does Rewriting Content Make It Unique Enough?
Rarely. Surface-level synonym swaps change almost nothing from Google’s perspective, because the search engine evaluates semantic similarity, not character matching. Three rewritten sentences in a paragraph still convey the same information.
Genuine uniqueness comes from added value: original data, direct experience, different examples, a distinct argument, or a different angle on the same subject.
If all you can do is reword, you probably should not publish the page at all.
How Long Does It Take to See Results After a Duplicate Content Fix?
Expect four to eight weeks for consolidation to show in Search Console, assuming you request a recrawl after making changes. Large sites with deep crawl backlogs can take longer.
The fastest results come from redirects, because Google processes them quickly. Canonical consolidation is slower, since Google treats it as a hint and waits for confirming signals.
Watch the duplicate clusters in the Pages report rather than day-to-day keyword rankings. Ranking fluctuations are noisy; cluster size is a cleaner indicator.
Should I Delete Duplicate Pages or Redirect Them?
Redirect, almost always. A thoughtful approach to duplicate content fix reinforces your qualifications. Deleting a page that has earned backlinks throws away whatever equity those links carried. A 301 passes roughly all of it to the destination.
Delete only when the page has no external links, no traffic, and no unique value. Ask for confirmation before pulling anything permanently, because deletions are irreversible in a way that redirects are not.
If a page has real traffic but genuinely duplicates another, redirect it rather than deleting. That preserves the entry point for existing visitors.
Can Canonical Tags Hurt My Rankings if I Use Them Wrong?
Yes, and it happens constantly. Canonicalizing distinct pages to a single URL tells Google to ignore the others entirely. If those pages were earning traffic on their own, you have just handed that traffic to a competitor.
Audit canonicals before and after any template change. CMS platforms are notorious for generating canonicals that point somewhere unexpected.
What About Product Variations Like Size and Color?
Each variation can earn traffic if the duplicate content fix has its own search demand and unique reviews or specifications. Canonicalizing all of them to the parent product eliminates that potential.
A practical rule: if the variation has independent search volume and genuinely different content, give it its own page. If not, canonicalize it and consolidate.
How Do I Handle Syndicated Content With Partners?
Ask partners to add a canonical tag pointing to your original, and to delay publication by at least a few days if possible. Most legitimate partners will agree to both, especially if you provide the content free of charge.
If a partner refuses to add a canonical, consider whether the syndication is worth the ranking risk. Sometimes exposure is worth it, sometimes it is not.
For scrapers who will not cooperate, DMCA filings and prompt indexing are your best available tools.
Where This Fits in a Larger SEO Structure
Duplicate content consolidation sits inside a broader topic cluster: technical SEO hygiene. It shares a parent category with crawl budget management, index bloat control, and site architecture planning.
Treat it that way and the work compounds. A site that fixes its duplication, tightens its internal linking, and keeps its sitemap clean gets more out of every subsequent content investment.
The seven fixes above cover the mechanisms that create duplication on most sites. Work through them in order, document every change, and verify the outcome in Search Console before moving on.
One more point deserves emphasis. Every duplicate content fix is ultimately an exercise in clarity. You are telling Google, in the plainest terms available, which page is the real one. Do that clearly and consistently, and the search engine will usually reward you for it.