If you have ever stared at a schema tab in the console and wondered which column type would actually keep your pipeline from breaking, this guide to data types BigQuery is built for you.
I have spent years loading messy CSVs, streaming JSON events, and migrating legacy warehouses into BigQuery, and the single most common source of pain is always the same: choosing the wrong type.
The good news? Focusing on data types bigquery provides clear direction here. Once the type system clicks, everything downstream gets easier. Queries run faster, storage costs stay predictable, and weird timezone bugs stop haunting your dashboards. So let’s walk through it together, slowly but thoroughly.
Why Understanding Data Types BigQuery Matters So Much
BigQuery is not just a pretty face on top of a file system. Focusing on data types bigquery provides clear direction here. It is a strongly typed analytical database, which means every value you insert gets checked against the column definition at write time.
If you declare a column as INT64 and then try to push a string with a decimal into it, the load job will fail. Refining each detail of your data types bigquery strengthens this section. That’s not a bug; that’s a feature working exactly as designed.
Understanding data types BigQuery exposes helps in three separate areas that people often think are unrelated. First, correctness: your numbers stay numbers, dates stay dates, and aggregations return what you expect. Second, performance: narrow types mean less bytes scanned, and less bytes scanned means lower cost per query.
Third, join behavior. Mixing types across join keys silently forces implicit casting, and implicit casting is one of those things that “works” in dev on 10,000 rows and then explodes in production on 50 million. I’ve been on the wrong end of that; it taught me to lock types down early.
The Full Catalog of Data Types BigQuery Supports
Let’s start with the big picture, then zoom in. Effective execution in your data types bigquery makes a tangible difference. BigQuery groups its types into a handful of families, and once you internalize the families, reading the docs becomes much less intimidating. The families are numerics, strings, bytes, booleans, temporal types, geographic types, structs, arrays, and JSON.
Here’s a compact reference that I keep next to my keyboard when designing tables. Trust me, it saves a lot of Alt-Tab.
| Family | Type | Typical Use Case | Notes |
|---|---|---|---|
| Numeric | INT64 | Counts, IDs, whole numbers | Up to 9.2 quintillion |
| Numeric | NUMERIC / BIGNUMERIC | Money, precise decimals | Fixed precision, no floating-point drift |
| Numeric | FLOAT64 | Measurements, ratios | Approximate; avoid for currency |
| String | STRING | Names, URLs, raw text | UTF-8, up to 10 MB |
| Bytes | BYTES | Hashes, encrypted payloads | Raw binary, base64-friendly |
| Boolean | BOOL | Flags, is_active, has_paid | Only TRUE/FALSE/NULL |
| Temporal | DATE, DATETIME, TIME, TIMESTAMP | Bookings, event logs | TIMESTAMP is absolute UTC |
| Geographic | GEOGRAPHY | Points, polygons, routes | WKT/GeoJSON compatible |
| Complex | ARRAY, STRUCT | Nested events, multi-value fields | Nested but not unlimited |
| Flexible | JSON | Semi-structured payloads | Queryable with JSON functions |
That table is a good bookmark, but each family deserves a proper discussion. Let’s take them one at a time, because when someone says “data types BigQuery is confusing,” they usually mean one specific family is giving them trouble.
Numeric Data Types BigQuery Offers (And When to Use Each)
Numbers are the most deceptively simple family. Maintaining clarity across your data types bigquery remains essential. Everyone reaches for INT64 by reflex, but money, scientific measurements, and IDs each want different treatment. Picking well the first time is far cheaper than fixing it later with a scheduled backfill at 2 a.m.
INT64: the Backbone Integer Type
INT64 handles whole numbers anywhere from roughly negative nine quintillion to positive nine quintillion. Refining each detail of your data types bigquery strengthens this section. It covers almost every counting, aggregation, and identifier use case you’ll ever throw at BigQuery. User IDs, order counts, pageviews, session lengths—all of these belong in INT64 without hesitation.
Watch out for two things, though. A thoughtful approach to data types bigquery reinforces your qualifications. First, if you’re migrating from a system with BIGINT that exceeds the INT64 range (which is rare but happens with hash-derived IDs), BigQuery will reject the load. Second, INT64 does not allow decimals.
Even an integer stored as 42.0 from a CSV will fail if BigQuery’s autodetect guesses STRING for that column and then you cast back.
NUMERIC and BIGNUMERIC: Precision You Can Trust
Currency almost killed me on my first BigQuery project. Structuring your data types bigquery around proven patterns ensures impact. I used FLOAT64 because it “looked fine” in dev, and then finance reconcilation reports were off by a few cents on aggregated totals. The culprit is floating-point representation error—FLOAT64 cannot store many decimal fractions exactly, so small errors compound across sums.
Enter NUMERIC (up to 38 digits of precision and 9 decimal places) and BIGNUMERIC (76 digits of precision, 38 decimal places). For invoice totals, ledger balances, and tax calculations, always reach for NUMERIC. Store in the same currency unit (typically cents) and format on output.
My rule of thumb: if the value touches money, use NUMERIC. Applying these principles to your data types bigquery yields measurable results. If the value is a scientific calculation that tolerates approximation, FLOAT64 is fine.
FLOAT64: When Approximation is Acceptable
FLOAT64 is a double-precision binary floating-point number, similar to a double in Java or a float64 in Go. Effective execution in your data types bigquery makes a tangible difference. It’s excellent for statistics, sensor readings, percentages, and percentile calculations. It’s terrible for anything where humans expect exact decimal output.
One practical trick: when comparing FLOAT64 values in a query, never use = on the raw values. Proper attention to your data types bigquery sets a strong baseline. Use a tolerance, like ABS(a - b) < 0.0001. It reads a bit defensive, but it will save you from “joins that sometimes miss.”
Choosing Among the Numeric Data Types BigQuery Exposes
Here’s a simple decision path I follow in design reviews. If it’s a count, flag, or ID, use INT64. If it involves money or regulatory-grade precision, use NUMERIC. If it’s a scientific measurement, ratio, or weighted average that will only ever be consumed by analytics, FLOAT64. That covers the majority of decisions.
There’s one more subtle case: decimal inputs that originate as strings. Developing your data types bigquery with precision highlights key strengths. If your source system stores amounts as text (for example, legacy ERP extracts), don’t have BigQuery autodetect as FLOAT64. Explicitly cast to NUMERIC in your schema. Autodetect is a convenience, not a strategy.
String and Bytes Data Types BigQuery Handles
Strings are the most abused type in any warehouse. Everything becomes a STRING when someone is in a hurry, and then suddenly you’re parsing dates out of “-05” or casting currency out of “competitive direct manufacturer pricing”. Learning the STRING family properly pays off immediately.
STRING: UTF-8 Text With a Hard Cap
BigQuery STRING holds variable-length UTF-8 encoded text up to 10 MB per value. Clear alignment with your data types bigquery builds confidence from the start. That’s huge; almost no normal application data hits it. But it does mean you can hold multi-megabyte JSON blobs as strings if you want (even though you probably shouldn’t).
Two things to remember: STRING values are compared and sorted lexicographically, and Unicode normalization is not implicit. Maintaining clarity across your data types bigquery remains essential. If you’re doing string equality across systems, run a NORMALIZE call first. Otherwise, an accented character encoded two ways will fail the join despite “looking identical” on screen.
BYTES: Binary Payloads That Skip Encoding
BYTES holds raw binary data. Integrating data types bigquery into your workflow produces consistent quality. Common uses are encryption keys, hashes (SHA-256 outputs), and Avro/Protobuf serialized payloads. It’s also useful when you want to store payloads that are not valid UTF-8; STRING will reject those, but BYTES takes them happily.
You can convert between STRING and BYTES with explicit functions. That’s good for interoperability with things like base64 encoded payloads. But treat BYTES as an opt-in; using it when you just “don’t want encoding issues” usually makes everything harder downstream because BigQuery UI, Looker, and most BI tools display BYTES as unreadable blobs.
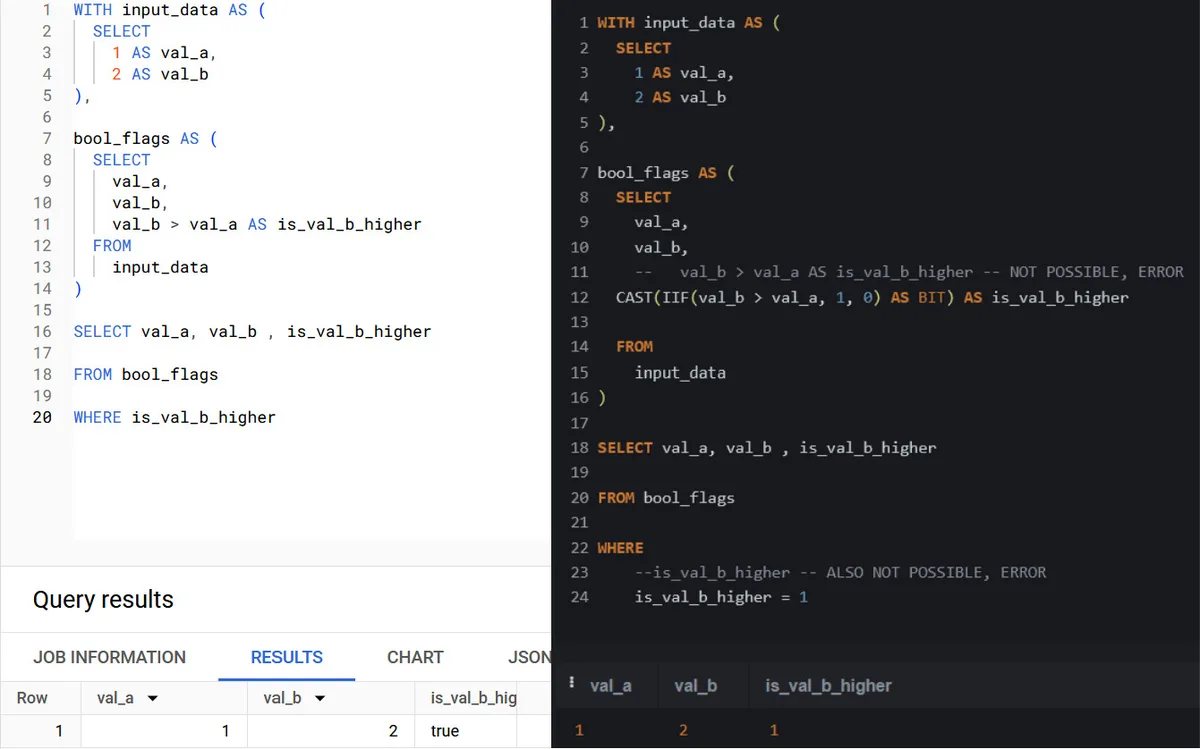
Boolean Data Types BigQuery Supports
BOOL is simple and underrated. Targeted refinements to your data types bigquery streamline the entire review. TRUE, FALSE, and NULL—nothing else. It’s the right choice for flags like is_churned, has_completed_onboarding, or is_employee. Store as BOOL, and your queries read naturally (WHERE is_churned = TRUE) instead of decoding integers.
The one wrinkle is NULL handling. BOOL allows NULL, which causes three-valued logic in filters. A filter like WHERE is_churned = TRUE will silently drop NULL rows, while WHERE NOT is_churned will also drop them (because NOT NULL is NULL, not TRUE). If your reporting depends on non-null flags, either fill defaults at ETL time or use IFNULL(is_churned, FALSE) in queries.
I’ve stopped counting the number of “missing rows” bug reports I’ve traced back to exactly this NULL behavior. A thoughtful approach to data types bigquery reinforces your qualifications. It’s worth an automated test in your pipeline.
Temporal Data Types BigQuery Provides (Dates, Times, Timestamps)
Temporal types cause the most confusion in real-world projects. Part of that comes from timezone surprises, and part of it comes from picking the wrong family member. There are four distinct types, and they are not interchangeable.
DATE: Calendar Days Without Time
DATE holds a calendar date with no time component and no timezone. It’s perfect for booking dates, hire dates, birthdays, fiscal period endpoints, and any dimension that a business user would write on a whiteboard. If your users ever say “the 15th,” they probably mean a DATE.
One warning: DATE values compare in local calendar terms. Structuring your data types bigquery around proven patterns ensures impact. DATE '-01-31' is always that date, regardless of timezone. That is what you want for consistency in reporting.
DATETIME: Local Civil Time
DATETIME combines a date and a time but stays timezone-less. It’s the right type when you’re recording “wall clock at the store” and don’t care about absolute moments. Appointment slots, store opening times, and shift schedules are common DATETIME users.
The pitfall is that DATETIME does not mean “UTC.” If you pick DATETIME because you saw a timestamp string, you might be subtly wrong. For event timestamps, use TIMESTAMP. For local schedules, DATETIME is correct.
TIME: Clock Time Only
TIME stores hours, minutes, seconds, and fractional seconds within a single day. Applying these principles to your data types bigquery yields measurable results. It’s the type to use for recurring schedule values (e.g., “notification fires at 08:30 every morning”) where the date itself doesn’t matter.
Keep in mind it will roll over between timezones; if a schedule needs to be timezone-aware, store the timezone alongside it.
TIMESTAMP: Absolute Moments in UTC
TIMESTAMP is the most misunderstood of the data types BigQuery exposes, and it’s also the most important. A TIMESTAMP represents an absolute point in time, internally normalized to UTC. When you display it with a timezone, BigQuery converts for you.
My rule: event ingestion, click streams, log lines, and API response times all belong in TIMESTAMP. Store the raw event moment in TIMESTAMP and store the user’s local timezone in a separate STRING column. Never fake a local time by adding an offset to TIMESTAMP; you’ll break daylight saving time within a year.
Choosing Between the Data Types BigQuery Offers for Time
Here’s the mental checklist I hand to junior engineers. Proper attention to your data types bigquery sets a strong baseline. Does the value represent an absolute moment? TIMESTAMP. Is it a local calendar day? DATE. Is it a local wall clock timestamp? DATETIME. Is it just a time-of-day value tied to a schedule? TIME.
Two extra habits save lives. First, always store timestamps in UTC and convert at the presentation layer. Second, write a quick unit test that compares a known timezone conversion. If you don’t test it, a bug will surface during a daylight-saving transition, and it will absolutely land on a Friday.
Geographic Data Types BigQuery Uses: GEOGRAPHY
GEOGRAPHY stores points, lines, and polygons using the WGS84 coordinate system. It’s the type behind store locators, delivery radius calculations, and any “closest warehouse” query.
If you have latitude and longitude columns, you can wrap them into POINT values with a function, or you can store GEOGRAPHY directly and preserve all the geospatial features.
The practical decision is: if all you need is distance between two points, keep FLOAT64 latitude/longitude columns and use a distance function. If you need containment (“is this delivery address inside our polygon service area?”), store GEOGRAPHY. The specialized functions like ST_CONTAINS and ST_WITHIN expect it.
One caveat: geographic calculations are correct but not cheap. If you’re running them across tens of millions of rows, pre-filter by a coarse bounding box first. It’s the standard move and it dramatically cuts query cost.
Complex Data Types BigQuery Lets You Nest: ARRAY and STRUCT
This is where BigQuery really flexes. Developing your data types bigquery with precision highlights key strengths. Unlike many warehouses, BigQuery supports nested and repeated fields natively, and used well, they make modeling tight and elegant. Used badly, they turn every query into an exercise in explosive unnesting.
ARRAY: Ordered Lists of a Single Type
ARRAY is an ordered list whose elements all share one type. You can have arrays of INT64, arrays of STRING, arrays of STRUCT, and so on.
Event streams with variable tags, product lists on an order, or sets of tags on a document are all archetypal ARRAY users.
Querying ARRAY columns uses UNNEST to flatten. Clear alignment with your data types bigquery builds confidence from the start. There’s a subtle but important cost consideration: unnesting a large array on a huge table is expensive, so filter before you unnest when you can. The WHERE tag IN UNNEST(tags) pattern is often a smarter filter than unnesting in the SELECT clause.
STRUCT: Named Fields Grouped Together
STRUCT bundles named fields into one value. It’s essentially a typed record. Address, user profile, and dimension bundles are common. You can reference fields with dot notation, which reads naturally: user.address.city.
One of my favorite patterns is the “wide but organized” table—using STRUCT to group related fields without flattening everything. Instead of 40 columns called dimension_1 through dimension_40, use a couple of STRUCTs. Your schema panel in the console becomes navigable instead of a scroll marathon.
The main watch-out: STRUCTs cannot be directly indexed, and joins on STRUCT fields require you to reach into individual leaf values. Integrating data types bigquery into your workflow produces consistent quality. So if a leaf column will be joined frequently, consider promoting it to a top-level column. Nested is not always better.
Rules and Limits for the Complex Data Types BigQuery Enforces
BigQuery enforces a few rules that catch newcomers. Arrays of arrays are not allowed directly (wrap them in a STRUCT to work around). STRUCTs cannot contain themselves recursively. And there’s a limit of roughly 15 levels of nested STRUCT depth. These limits rarely matter in practice, but knowing them helps you anticipate errors before the load job fails.
There’s another one worth flagging: you can’t add a required ARRAY column to an existing table with the ADD COLUMN statement if the table already has data.
Instead, define it at creation time, or add it as a nullable ARRAY. Targeted refinements to your data types bigquery streamline the entire review. It’s a small detail that trips people up during schema evolution sprints.
JSON Data Type in BigQuery for Semi-Structured Data
BigQuery added a native JSON data type, and it changes how you handle semi-structured payloads. Unlike STRING containing text that happens to be JSON, native JSON is validated and queryable with specialized functions like JSON_VALUE, JSON_QUERY, and JSON_EXTRACT.
When should you use JSON instead of the alternative? Use JSON when the schema genuinely varies (raw webhook payloads, mixed experiment results, third-party API responses). Use STRUCT when the fields are stable. JSON gives flexibility; STRUCT gives clarity and better performance.
One performance rule of thumb: if you’re querying the same JSON key over and over in dashboards, extract it into a proper column in the ETL layer. Focusing on data types bigquery provides clear direction here. The JSON storage overhead is real, and column extraction is a genuine optimization.
Common Source Types, Conversions, and How Data Types BigQuery Resolves
When you load data from files or stream records, source types don’t always map one-to-one. CSV gives you strings, Avro and Parquet give strongly typed columns, and JSON gives you primitives that BigQuery must infer. Each source has its peculiar handling, and knowing the mapping saves a lot of debugging.
The safest pattern is to define an explicit schema before you load: no autodetect for critical pipelines. Autodetect is a wonderful convenience for exploration but a liability at scale.
It has a sampling behavior that can be confused by mixed columns, and you don’t want your nightly job to fail because someone shipped a slightly new file format on a Friday afternoon.
For streaming, always declare the schema in your producer library and let BigQuery validate it. Type mismatches fail fast, which is exactly what you want—better a lightning-fast rejection than a silent corruption discovered three weeks later during the board meeting.
Implicit and Explicit Conversions Between Data Types BigQuery
BigQuery coerces types in some contexts and rejects in others. Implicit conversion (supertype coercion) happens when comparing INT64 and NUMERIC, or INT64 and FLOAT64.
The smaller type is promoted to the larger. Refining each detail of your data types bigquery strengthens this section. That’s usually fine except when it silently changes precision, which is a real risk with FLOAT64.
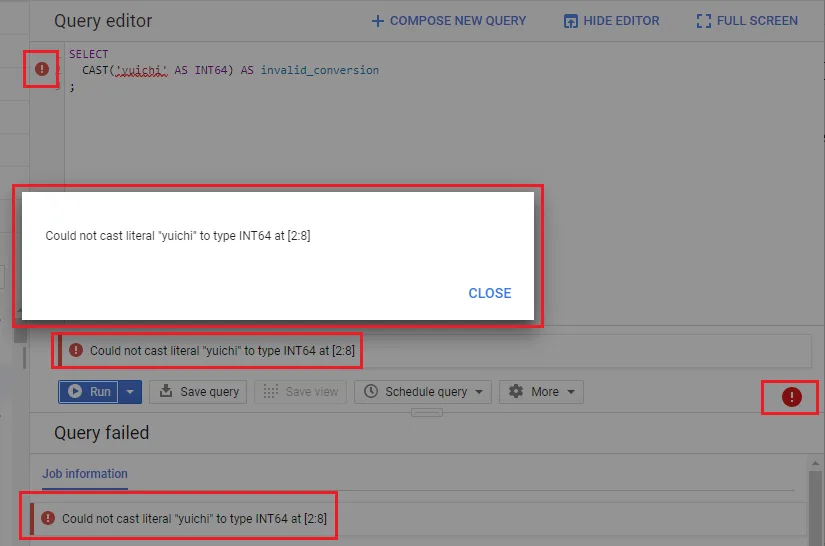
Explicit conversion uses CAST or SAFE_CAST. CAST fails hard on invalid values; SAFE_CAST returns NULL. For semi-clean data, SAFE_CAST is your friend. For production pipelines where NULL is unacceptable, use CAST and fail loudly—then fix the source.
Here’s a subtle one that trips up SQL veterans: comparing STRING to INT64 does not implicitly coerce in BigQuery. You have to cast explicitly. That behavior is stricter than MySQL or Postgres, and it’s a good thing—it prevents mystery joins.
Casting and Safe Casting in Data Types BigQuery Workflows
Casting deserves its own space because it’s the primary tool for wrangling the type system across joins and unions. In practice, when refining a data types bigquery, most casting is necessary because data arrived in a different type than it was supposed to. That usually means a source-side problem, but the warehouse must cope regardless.
Three casting habits I recommend. First, cast early in the pipeline so downstream queries never deal with ambiguity. Second, use SAFE_CAST in exploratory or data-quality queries to avoid aborting runs. Third, log every row that SAFE_CAST turns into NULL; the count is a useful data-quality metric.
One extra: casting between DATE and STRING uses a format string. Always specify the format explicitly. Relying on the default can produce ambiguous results with locales, and a silent misparse is much worse than a loud failure.
Designing Schemas Around Data Types BigQuery Actually Uses Well
Schema design is where data types BigQuery knowledge pays the biggest dividend. There’s a well-known trade-off between normalized (many small tables) and denormalized (few wide tables). BigQuery leans toward denormalized, but not blindly: nested and repeated fields let you have “denormalization without the explosion.”
Here’s what that looks like in practice. Maintaining clarity across your data types bigquery remains essential. Instead of a separate line_items table for every order, store line items as an ARRAY of STRUCT directly on the order row. Querying is still straightforward (UNNEST(line_items)), storage is tight, and joins collapse away.
The counter-case is any dimension that will grow or change frequently (customer profile fields, product metadata). Those are better normalized. Denormalization benefits read performance; it punishes write flexibility. Pick based on the workload, not fashion.
One thing I insist on with every team: naming conventions should reflect type. Suffix _at for TIMESTAMP, _date for DATE, _count for INT64, _amount for NUMERIC. It’s a small discipline that prevents a lot of “wait, is this cents or dollars?” questions.
Working With the Data Types BigQuery Uses in Real Pipelines: Practical Examples
Concrete examples are worth more than theory. A thoughtful approach to data types bigquery reinforces your qualifications. Here are scenarios I’ve actually run into, along with the type decisions that made them work. Think of these as field notes rather than a reference manual.
- E-commerce order table. order_id as INT64 (or STRING if it’s a UUID), order_date as DATE, order_ts as TIMESTAMP, total_amount as NUMERIC, currency_code as STRING with fixed length 3, line_items as ARRAY of STRUCT containing sku (STRING), quantity (INT64), unit_price (NUMERIC). The line_items array removes the need for a join while keeping analytics fast.
- Web analytics event stream. session_id as STRING, event_name as STRING, event_ts as TIMESTAMP, user_properties as STRUCT with browser (STRING), country (STRING), and plan (STRING), plus event_params as JSON for the flexible payload. Structuring the stable properties and leaving the variable ones JSON prevents schema churn.
- IoT sensor readings. device_id as STRING, reading_ts as TIMESTAMP, temperature_c as FLOAT64, humidity_pct as FLOAT64, battery_mv as INT64, location as GEOGRAPHY. Store location as GEOGRAPHY only if you need geofencing; otherwise two FLOAT64 columns (lat, lon) are cheaper to work with.
- Financial ledger. transaction_id as STRING (UUID), posted_at as TIMESTAMP, amount_minor_unit as INT64 for exact cent-level storage, currency, account_id, and a separate amount as NUMERIC for presentation layer. Having both representations is often handy: INT64 is fast for sums, NUMERIC is authoritative for reporting.
- Content publishing metadata. article_id as STRING, published_at as TIMESTAMP, publish_date as DATE (for calendar-based reporting), tags as ARRAY of STRING, seo_metadata as JSON holding varying structures, word_count as INT64. The mix of ARRAY and JSON lets content evolve without schema changes.
- User profile dimension. user_id as INT64, created_at as TIMESTAMP (UTC), birth_date as DATE, marketing_opt_in as BOOL, address as STRUCT, phone as STRING, preferred_language as STRING. Structuring the address prevents the seven-column sprawl you see in poorly designed dimension tables.
Each of those examples works because the type was chosen for the semantics, not the storage representation. When you pick data types BigQuery semantically, the system stays honest about what values mean.
Anti-Patterns and Pitfalls in Data Types BigQuery Migrations
I’ve seen a lot of mistakes across projects, and they cluster into recognizable patterns. Avoiding the following will save you months of collective head-scratching.
Storing timestamps as STRING. Never store a TIMESTAMP as a string. Every filter, every ordering, every time-zone conversion becomes an exercise in parsing. If you must keep the raw string for provenance, keep it in a separate column and the typed value in the primary column.
Using FLOAT64 for money. I mentioned this earlier but it bears repeating. Structuring your data types bigquery around proven patterns ensures impact. Half-cent errors compound across millions of transactions, and the resulting audit is not fun. NUMERIC is the answer.
Over-nesting arrays. Arrays are great, but if your UNNEST chain goes four levels deep, most queries look like a math exam. If a nested structure gets queried as independent tables more often than as a bundle, promote it to a table.
Relying on autodetect in production. Autodetect is exploratory gold. In production, define your schema. This is a hard rule for me and the teams I work with.
Ignoring NULL semantics in BOOL. Three-valued logic is not a bug, but the surprising filter behavior costs debugging time and shipping velocity. Applying these principles to your data types bigquery yields measurable results. Convert to non-null when sensible.
Best Practices for Choosing and Evolving Data Types BigQuery Tables
Best practices aren’t universal, but there are good defaults. Pick the narrowest type that fits the domain; wide generic types bloat storage and slow queries. Store UTC timestamps and convert at read. Prefer NUMERIC for money. Prefer DATE for calendar dimensions. Prefer STRUCT for grouped stable fields and JSON for genuinely variable payloads.
For schema evolution: adding nullable columns is cheap; changing types in place often requires rewriting data. Use partitioning and clustering to keep query costs down as tables grow. And test every type change against your most complex downstream query—joins are where type surprises most often appear.
One trend I’m noticing: teams are increasingly treating type definitions as code. Storing schemas in a repository, running schema diffs in CI, and enforcing conventions with a linter. It sounds heavy, but for data types BigQuery the investment pays back quickly once a few pipelines are live.
Frequently Asked Questions About Data Types BigQuery
Here is an in-depth breakdown of key considerations regarding this section:
What are the Main Data Types BigQuery Supports?
The main families are INT64, NUMERIC, BIGNUMERIC, FLOAT64, STRING, BYTES, BOOL, DATE, DATETIME, TIME, TIMESTAMP, GEOGRAPHY, ARRAY, STRUCT, and JSON. Once you group them by family (numerics, strings, temporals, geographic, complex, flexible), the list becomes much easier to reason about.
Is There a Difference Between DATETIME and TIMESTAMP in BigQuery?
Yes, and it’s important. DATETIME is a local wall-clock value with no timezone; TIMESTAMP is an absolute moment normalized to UTC. If the value represents something on a calendar in a specific place, use DATETIME. If it’s an event that happened at a real moment in time, use TIMESTAMP.
Why Does BigQuery Prefer NUMERIC Over FLOAT64 for Money?
FLOAT64 stores values as binary doubles and cannot represent many decimal fractions exactly. Tiny representation errors compound across sums, which is unacceptable for financial reporting. NUMERIC provides fixed-precision decimal storage that matches how money is actually defined.
Can I Store JSON Directly in BigQuery?
Absolutely. BigQuery has a native JSON data type that lets you store and query semi-structured payloads without losing schema flexibility. Just avoid treating JSON as a parking lot for every attribute; extract frequently queried fields into real columns for performance.
What is the Difference Between ARRAY and STRUCT?
ARRAY is an ordered collection of values sharing the same type, such as a list of tags. STRUCT groups named fields of potentially different types into a single value, similar to a record. They’re often combined: an ARRAY of STRUCT represents a list of line items, each with fields like SKU, quantity, and price.
How Does BigQuery Handle Type Conversion During Joins?
BigQuery applies supertype coercion for compatible numeric types, such as INT64 joining NUMERIC. However, it does not implicitly convert between STRING and numeric types; you must cast explicitly. Explicit casting is a good habit because it documents intent and prevents accidental data loss.
Can I Change a Column’s Data Type in BigQuery Later?
Some changes are allowed (for example, widening INT64 to NUMERIC), but many require a rebuild: recreating the table and copying data over. Plan for schema evolution in your initial design by choosing types that will hold future values without widening.
What’s the Safest Way to Migrate Legacy Types Into BigQuery?
Define an explicit target schema before loading. Use SAFE_CAST during preliminary loads to spot issues, then switch to CAST once data quality is high. Run a data-quality check that counts NULL-ified parses. Only then enable the pipeline in production.
Wrapping Up Practical Guidance for Data Types BigQuery
If there’s one takeaway from this whole guide, it’s that data types BigQuery offers are not decoration—they’re the contract your pipeline runs on. Choose them intentionally, choose them early, and treat schema definitions as first-class code.
Start small. Run one field audit on your most important table this week. Review each column, ask whether the current type really captures its meaning, and fix the ones that don’t. That single hour of work will have a bigger impact on query reliability than almost anything else you could do.
And honestly, that’s the kind of fix that quietly prevents a dozen 2 a.m. Incidents you’ll never even know you avoided.
[ META_DESCRIPTION ]: Data types BigQuery made practical—choose the right numeric, string, temporal, and nested types, avoid silent cast bugs, and design schemas that scale.
For verified reference and background research, consult the authoritative informational resource on this topic.